# Smicolon
> Production AI engineering, software development and workflow automation.
## Agent access
- [Search](https://smicolon.com/search): Search published articles, services, case studies and pages.
- [Search API](https://smicolon.com/api/site-search?q=AI&type=articles): JSON results; q, type (all, articles, services, case-studies, pages), page and limit (1–20). Locale follows the website domain.
- [Full editorial text](https://smicolon.com/llms-full.txt)
- [Page text](https://smicolon.com/content.md?path=%2F): Pass a canonical public pathname in path.
- [Project brief](https://smicolon.com/value-project)
- [Contact](https://smicolon.com/contact)
- [Sitemap](https://smicolon.com/sitemap.xml)
Compatible browsers expose WebMCP tools while the page is open. Enquiry and newsletter forms require review and submission. Opening the booking scheduler does not book an appointment.
## Published content
---
# We Fixed What Offshore Software Development Broke — The Pain Points No One Dares to Talk About
Source: https://smicolon.com/blog/fixing-offshore-software-development-pain-points
Updated: 2026-07-31T23:28:05.368Z
For years, startups and small businesses placed their hopes in offshore software development — convinced it was the shortcut to building products faster and scaling smarter. But what once promised “speed and savings” slowly turned into something else: communication barriers, limited ownership, endless revisions, and teams delivering code without context. Many founders now describe the experience as babysitting a remote team instead of building their product.
Then came SaaS (Software as a Service) — a subscription-based model that turned software into a scalable, predictable service that anyone could adopt with ease. But SaaS only solved half the problem — it changed how software was delivered, not how it was built. Behind those sleek platforms, teams were still trapped in the same loops — disconnected, disorganised, and struggling to maintain consistent, optimised quality while outsourcing software development.
The same story kept repeating — brilliant ideas lost in translation, startup budgets drained on half-built MVPs, and white-label partners forced to redo vendor work just to protect their reputation. Around 60% of companies admit their vendors often miss the mark, leading to wasted time, reduced performance, and mounting costs.
After years of dealing with miscommunication and half-delivered promises, today’s companies no longer seek developers — they seek strategic partners who think, build, and grow alongside their vision. That’s where Smicolon’s Software Development as a Service (SDaaS) model comes in.
Born from the industry's growing frustration with unreliable outsourcing, Smicolon was created to restore confidence, consistency, and craftsmanship to custom software development services. Our mission is simple — to make top-tier software development accessible to startups and SMBs worldwide through a subscription model with AI-enabled workflows, intelligent systems, and expert teams — all under one roof.
In this post, you’ll discover how Smicolon’s SDaaS model solves the biggest challenges of offshore software development — bridging time zones, closing cultural gaps, and turning miscommunication into smarter collaboration.
The Real Pain Points: Why Offshore Software Development is Failing
For many founders, offshore software development begins as a dream: faster builds, lower costs, and effortless scaling. But too often, reality paints a different picture — missed deadlines, AI-driven instability in teams, and endless fixes.
To understand why, we conducted interviews with startup founders, analysed over 150 discussions across Reddit, LinkedIn, and tech forums, and six recurring pain-point patterns appeared — consistent across startups, small businesses, and white-label agencies alike.
1. Communication Gaps & Time-Zone Friction
>It feels like we’re throwing money into a black hole." >"It’s like playing email ping-pong across continents.
Sound familiar? Many startup founders feel stuck in that “black box” outsourcing loop — paying invoices without real visibility. Add time zones to the mix, and even a simple update turns into a full-day delay. A survey found that 20% of remote workers cite time-zone differences as one of the biggest barriers to effective collaboration.
2. Task Completion Over Product Thinking
>They only tick boxes — they don’t think like our team." >"Even small changes feel like climbing a mountain.
Ever felt that way? Many startups have. Developers rush to complete their tasks but often overlook the bigger picture. They get things done, sure — but not the kind of momentum that drives real growth. According to Atlassian’s leadership research, teams that lack an ownership mindset deliver 30% fewer innovative outcomes, leading to slow innovation, and lost momentum.
3. The Hidden Cost of ‘Cheap’ Outsourcing
>We spend more fixing outsourced mistakes than doing real work." >"It feels like we’re paying twice for the same result.
Going cheap sounds smart — until the fixes start piling up. Many startups go for the lowest bid, only to spend twice as much fixing poor-quality work. Nearly 50% of companies underestimate the hidden costs of outsourcing software development, with rework and technical debt draining budgets without intelligent oversight.
4. High Turnover, Low Stability
>High team turnover makes projects unstable." >"Every few months, someone new joins, and we start from zero.
If it feels like you’re always onboarding new developers, you’re not alone! Frequent turnover breaks momentum, kills consistency, and erases accountability. Within months, no one remembers who owns what — or how the product actually works. In fact, turnover in outsourced teams can cut productivity by up to 40% — making stability one of the hardest things to protect in long-term projects.
5. Big Promises, Slow Delivery
>We ask for speed, they give us patience." >"They say yes to everything, but nothing meets our expectations.
It’s easy to say “yes” to win a project — but much harder to deliver on it. Offshore teams, especially in South Asia, often promise speed and affordability, but execution rarely matches the pitch. Without the startup mindset, they fall behind when agility and quick pivots matter most, leading to diminished delivery outcomes.
6. The White-Label Agency Struggle
>Our vendors act like strangers, not part of our team." >"One slip-up and our clients notice — we end up fixing everything ourselves." >"Quality goes up and down, and we pay the price.
If you run a white-label agency, you’ve probably felt this pain. Vendors say they’ll work like an extension of your team — but rarely do. One missed detail, one untested feature, and suddenly your client’s trust is on the line. Quality swings from great to questionable, communication gets messy, and you’re left cleaning up the chaos while deadlines slip away.
All these pain points point to a deeper issue — not a lack of talent, but a broken system. A system built for speed, not substance. One that rewards box-ticking over problem-solving and cost-cutting over collaboration.
Teams don’t need more developers; they need a better way to build — one grounded in clearer direction, smart processes, and shared ownership. That’s where a new kind of software development model comes in — one designed to fix what offshore software development broke.
The Smicolon Journey — Changing How Custom Software Development Services Are Done
When the founders of Smicolon GmbH met in Malaysia, they discovered a shared vision: to transform how companies build and scale digital products. They saw the same struggles everywhere: startups frustrated by unreliable offshore software development, white-label agencies struggling with inconsistent quality, and teams stuck in endless communication gaps.
From that spark came SDaaS — Software Development as a Service — an intelligent system that listens, understands, and truly partners with its clients. It’s a hybrid model that integrates the excellence of Western European software development services with the cost efficiency of offshore delivery, bringing the best of both worlds together in one seamless system. In practice, it blends onshore precision with offshore affordability, showing that quality and cost can finally work together.
What truly sets Smicolon apart is how it merges technology with intelligence. Our AI-assisted approach speeds up delivery and sharpens precision without losing the craftsmanship that defines us. Internally, we use intelligent workflows and business tools to streamline communication, automate routine work, and keep every project transparent, data-driven, and strategically managed from day one.
Our SDaaS model works on a simple subscription-based model — built for flexibility and scale, helping clients grow affordably and at their own pace. The subscription economy is expected to reach USD 996 billion by 2028, proving that companies now prefer ongoing partnerships over one-time projects. For short-term goals or one-time builds, our model also supports fixed project engagements.
Our services don’t stop at development; they extend to secure cloud hosting, available in both shared and dedicated setups, so every product runs fast, scales seamlessly, and stays under complete control.
And this is only the beginning. With Smicolon.ai — our upcoming AI-powered code generation platform, we’re taking custom software development services to the next level. It will create production-ready code, verified by Smicolon experts, making development faster, smarter, and more accessible than ever.
Our Promise
In today’s software landscape, the market feels divided. Onshore European providers deliver exceptional quality but at prices few startups can afford. Offshore teams cut costs but often sacrifice reliability and consistency. For founders, it’s a tough trade-off: excellence or affordability. Offshore shouldn’t mean distant, and onshore shouldn’t mean unreachable.
That’s where MidShore comes in — our way of bridging both worlds. We combine the precision and reliability of high-tier European development with the speed and accessibility of offshore delivery. It’s not just a position — it’s our promise: to make world-class enterprise software development attainable without compromise.
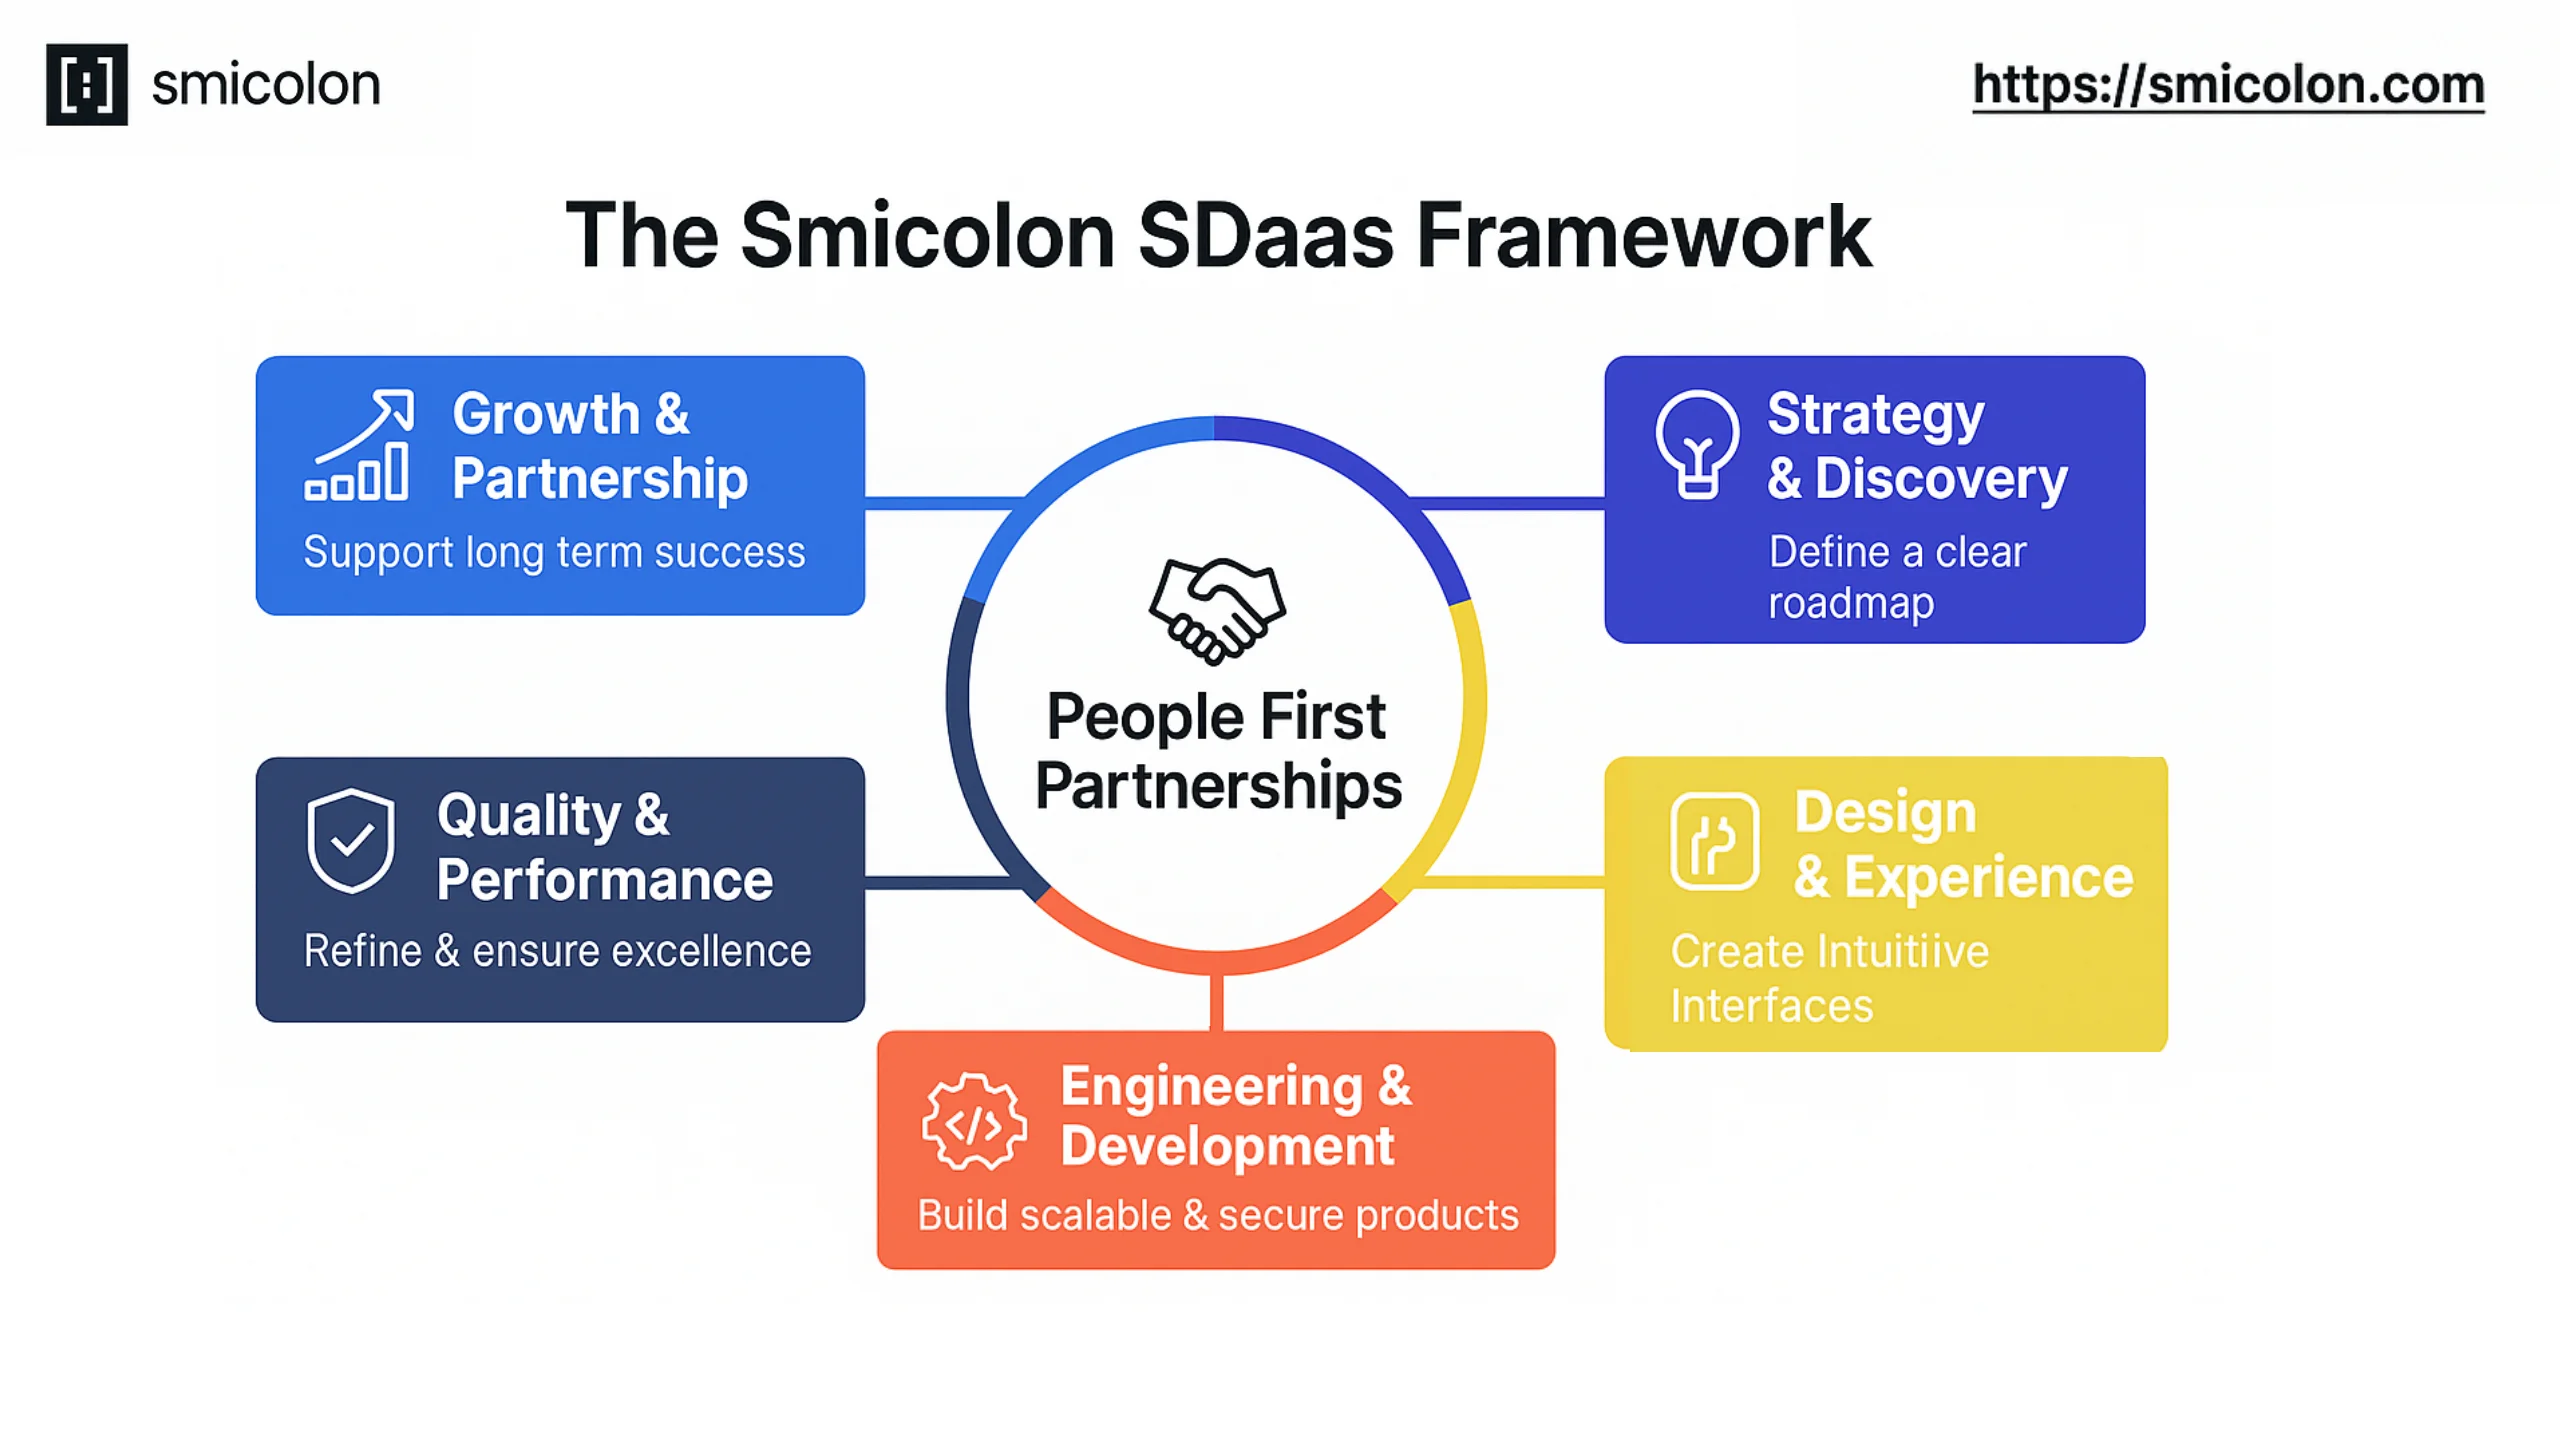
To bring that vision to life, we built a structured system that ensures every project moves with consistency, creativity, and collaboration — a model we call the Smicolon SDaaS Framework.
How the Smicolon SDaaS Framework Works
The Smicolon SDaaS Framework was designed to do one thing exceptionally well — make custom software development services predictable, transparent, and genuinely human-centred. Blending disciplined methods with modern technology, it simplifies complexity in software projects and brings strategic clarity to every stage of the development process.
Yet, behind every system and every line of code, it’s people who make the difference. Because every great product starts with people — not code.
The Heart: People-First Partnerships
At Smicolon, success begins with people — not projects. We focus on building long-term, trust-driven partnerships that go far beyond delivery. Our teams integrate seamlessly with yours, sharing the same goals, pace, and vision. When people move in sync, great products follow naturally, reflecting adaptive software development.
Once trust is built, we turn shared vision into action — creating the foundation for a structured, collaborative process that moves ideas from strategy to execution.
🔍 Discover → 🎨 Design → 💻 Build → 🚀 Launch → 📊 Measure → 🔧 Manage → ✅ Refine
1. Strategy and Discovery
Every partnership starts with understanding — not assumptions. We dive deep into your vision, users, and market to define a clear roadmap that aligns business goals with the right technology stack and execution plan, helping B2B SaaS companies uncover insights while leveraging AI-backed research and intelligent workflows from day one.
2. Design and Experience
We turn strategy into experience. Our design team transforms insights into intuitive, conversion-driven interfaces that embody your brand and make technology feel effortless, using AI-driven design systems to maintain consistency across every screen, sprint, and stakeholder.
3. Engineering and Development
This is where vision meets precision. Our engineers follow the discipline of high-tier European software engineering—writing secure, scalable code through agile sprints. Automated workflows enhance efficiency and precision, reflecting the standards of a top-tier software development agency.
4. Quality and Performance
Excellence lives in the details. Every build undergoes rigorous testing and peer review — powered by automated QA and AI frameworks that catch issues early and ensure reliability across clouds.
5. Growth and Partnership
Launch is just the beginning. We continue as your long-term technology partner — monitoring performance, integrating improvements, and evolving your product with your goals — guided by AI analytics and business-intelligent dashboards that reveal growth opportunities and help teams scale strategically.
Through this framework, Smicolon transforms software development from a transactional process into a transparent, dependable, and growth-driven partnership — one that closes the gap between strategic vision and flawless execution.
Our Core Services
At Smicolon, we don’t just code — we create complete digital systems. Our SDaaS model covers everything from product strategy to design, development, and ongoing management— powered by AI-assisted workflows and cloud-hosted reliability — so you can grow without juggling multiple vendors or facing delivery uncertainty.
Here’s what we bring to the table:
| Category | Service Groups | | | |
|------------------------------|---------|---------|---------|---------|
| Product Strategy |
Technology Consulting
|
Idea to MVP
|
AI-Assisted Development
|
Smicolon AI Coming Soon
|
| Design & Development |
Web & Mobile Development
|
UI UX Design
|
Cloud Hosting
|
Testing and QA
|
| Growth & Optimization |
Data Analytics & Insights
|
Application Management
|
Workflow Automation System
|
Continuous Optimization
|
Technology Consulting: We guide you toward the right tools, architecture, and roadmap to build with confidence.
Idea to MVP: We turn early-stage ideas into functional products fast — without compromising quality.
Web & Mobile Development: Scalable, high-performance apps built with precision and modern tech stacks.
UX/UI Design: Beautiful, intuitive interfaces that make technology effortless and user-friendly.
Testing & QA: Rigorous testing ensures every feature works flawlessly — before and after launch.
AI-Assisted Development: Intelligent tools accelerate coding and reviews while keeping the human touch intact.
Data Analytics & Insights: Turn complex data into clear, actionable insights for better decisions.
Application Management: We maintain, optimise, and evolve your product long after launch.
Cloud Hosting: Reliable, secure, and scalable hosting for every stage of growth.
Workflow Automation System: Streamline communication and operations with smart, transparent automated workflows.
Smicolon.ai (Coming Soon): AI-powered code generation verified by Smicolon experts — for faster, smarter builds.
Every service you see here solves a real problem founders face — misalignment, delays, quality gaps, and uncertainty. Together, they form the backbone of Smicolon’s SDaaS promise: a predictable, AI-empowered system that scales with you and evolves with your business.
Real-Life Proof (Case Study & Results)- SDaaS in Action
After building the foundation of trust, structure, and clarity, it’s time to see how our SDaaS model performs in the real world. These case studies showcase how Smicolon helps businesses achieve unmatched clarity, scalability, and measurable growth that speaks for itself.
Each example breaks down the challenge, our approach, and the outcome — showing how Smicolon drives measurable growth and lasting success.
1. SalesMinded — From Scattered Tools to One Scalable System
The Challenge: A fast-growing agency was buried in spreadsheets and disconnected tools. Freelancers delivered inconsistent quality, and there was no visibility or accountability across operations.
Our SDaaS Approach: We embedded a whole SDaaS Pod — Strategy, Design, and Engineering — into their workflow. Together, we built a unified SaaS platform powered by intelligent automation and integrated BI dashboards to connect sales, HR, and finance. The system automated approvals, reporting, and routine admin tasks, while real-time triggers kept teams aligned without manual checks.
The Outcome: SalesMinded operational overhead reduced by 35%, visibility improved company-wide, and white-label quality became consistent across every project.
2. Bravura S.A. — Design Precision Meets Engineering Speed
The Challenge: A luxury brand’s digital presence failed to reflect its premium identity. Previous developers left poor UX, broken layouts, and inconsistencies that weakened trust.
Our SDaaS Approach: We partnered directly with Bravura’s creative team to close the design-to-development gap. Together, we built a responsive, high-performance site enhanced with automated performance tracking and BI analytics to monitor engagement and conversions in real time.
The Outcome: User engagement increased by 48%, conversions by 32%, and the platform now self-optimises through data-driven performance insights.
3. 1UNI — Turning Manual Chaos Into Scalable Growth
The Challenge: This EdTech startup was managing operations through Excel and endless email chains. Manual errors, slow approvals, and unstable MVPs from previous vendors blocked growth.
Our SDaaS Approach: We rebuilt the platform using Smicolon’s AI-assisted framework — developing an AI-powered SaaS that connected over 3,000 courses and 120 universities. The system automated student matching, counselling workflows, and application tracking with complete sprint visibility.
The Outcome: Manual work dropped by 60%, onboarding doubled in speed, and founders finally gained visibility, stability, and full code ownership.
4. FeatureInbox — From Feedback Chaos to Product Clarity
The Challenge: Teams were drowning in scattered user feedback across multiple tools — with no analytics, prioritisation, or insight into what truly mattered.
Our SDaaS Approach: We analysed their workflows and engineered a central feedback dashboard that automatically collected, grouped, and analysed all user input. The system used automation tools to organise data, spot recurring themes, and generate quick insights. It also included BI visualisation for tracking feedback trends and product sentiment, while a modular backend ensured scalability and full data transparency.
The Outcome: FeatureInbox gained a single source of truth for user insights. Product teams now make decisions 2× faster, driven by clarity instead of guesswork, supported by AI analytics and automated reporting workflows. Smicolon’s SDaaS model solves what slows growing businesses — poor communication, inconsistent quality, and weak processes — by uniting strategy, design, and engineering into one scalable system.
The results speak for themselves — a clear look at how each business grew in delivery speed, quality, engagement, and efficiency after adopting Smicolon’s SDaaS model.
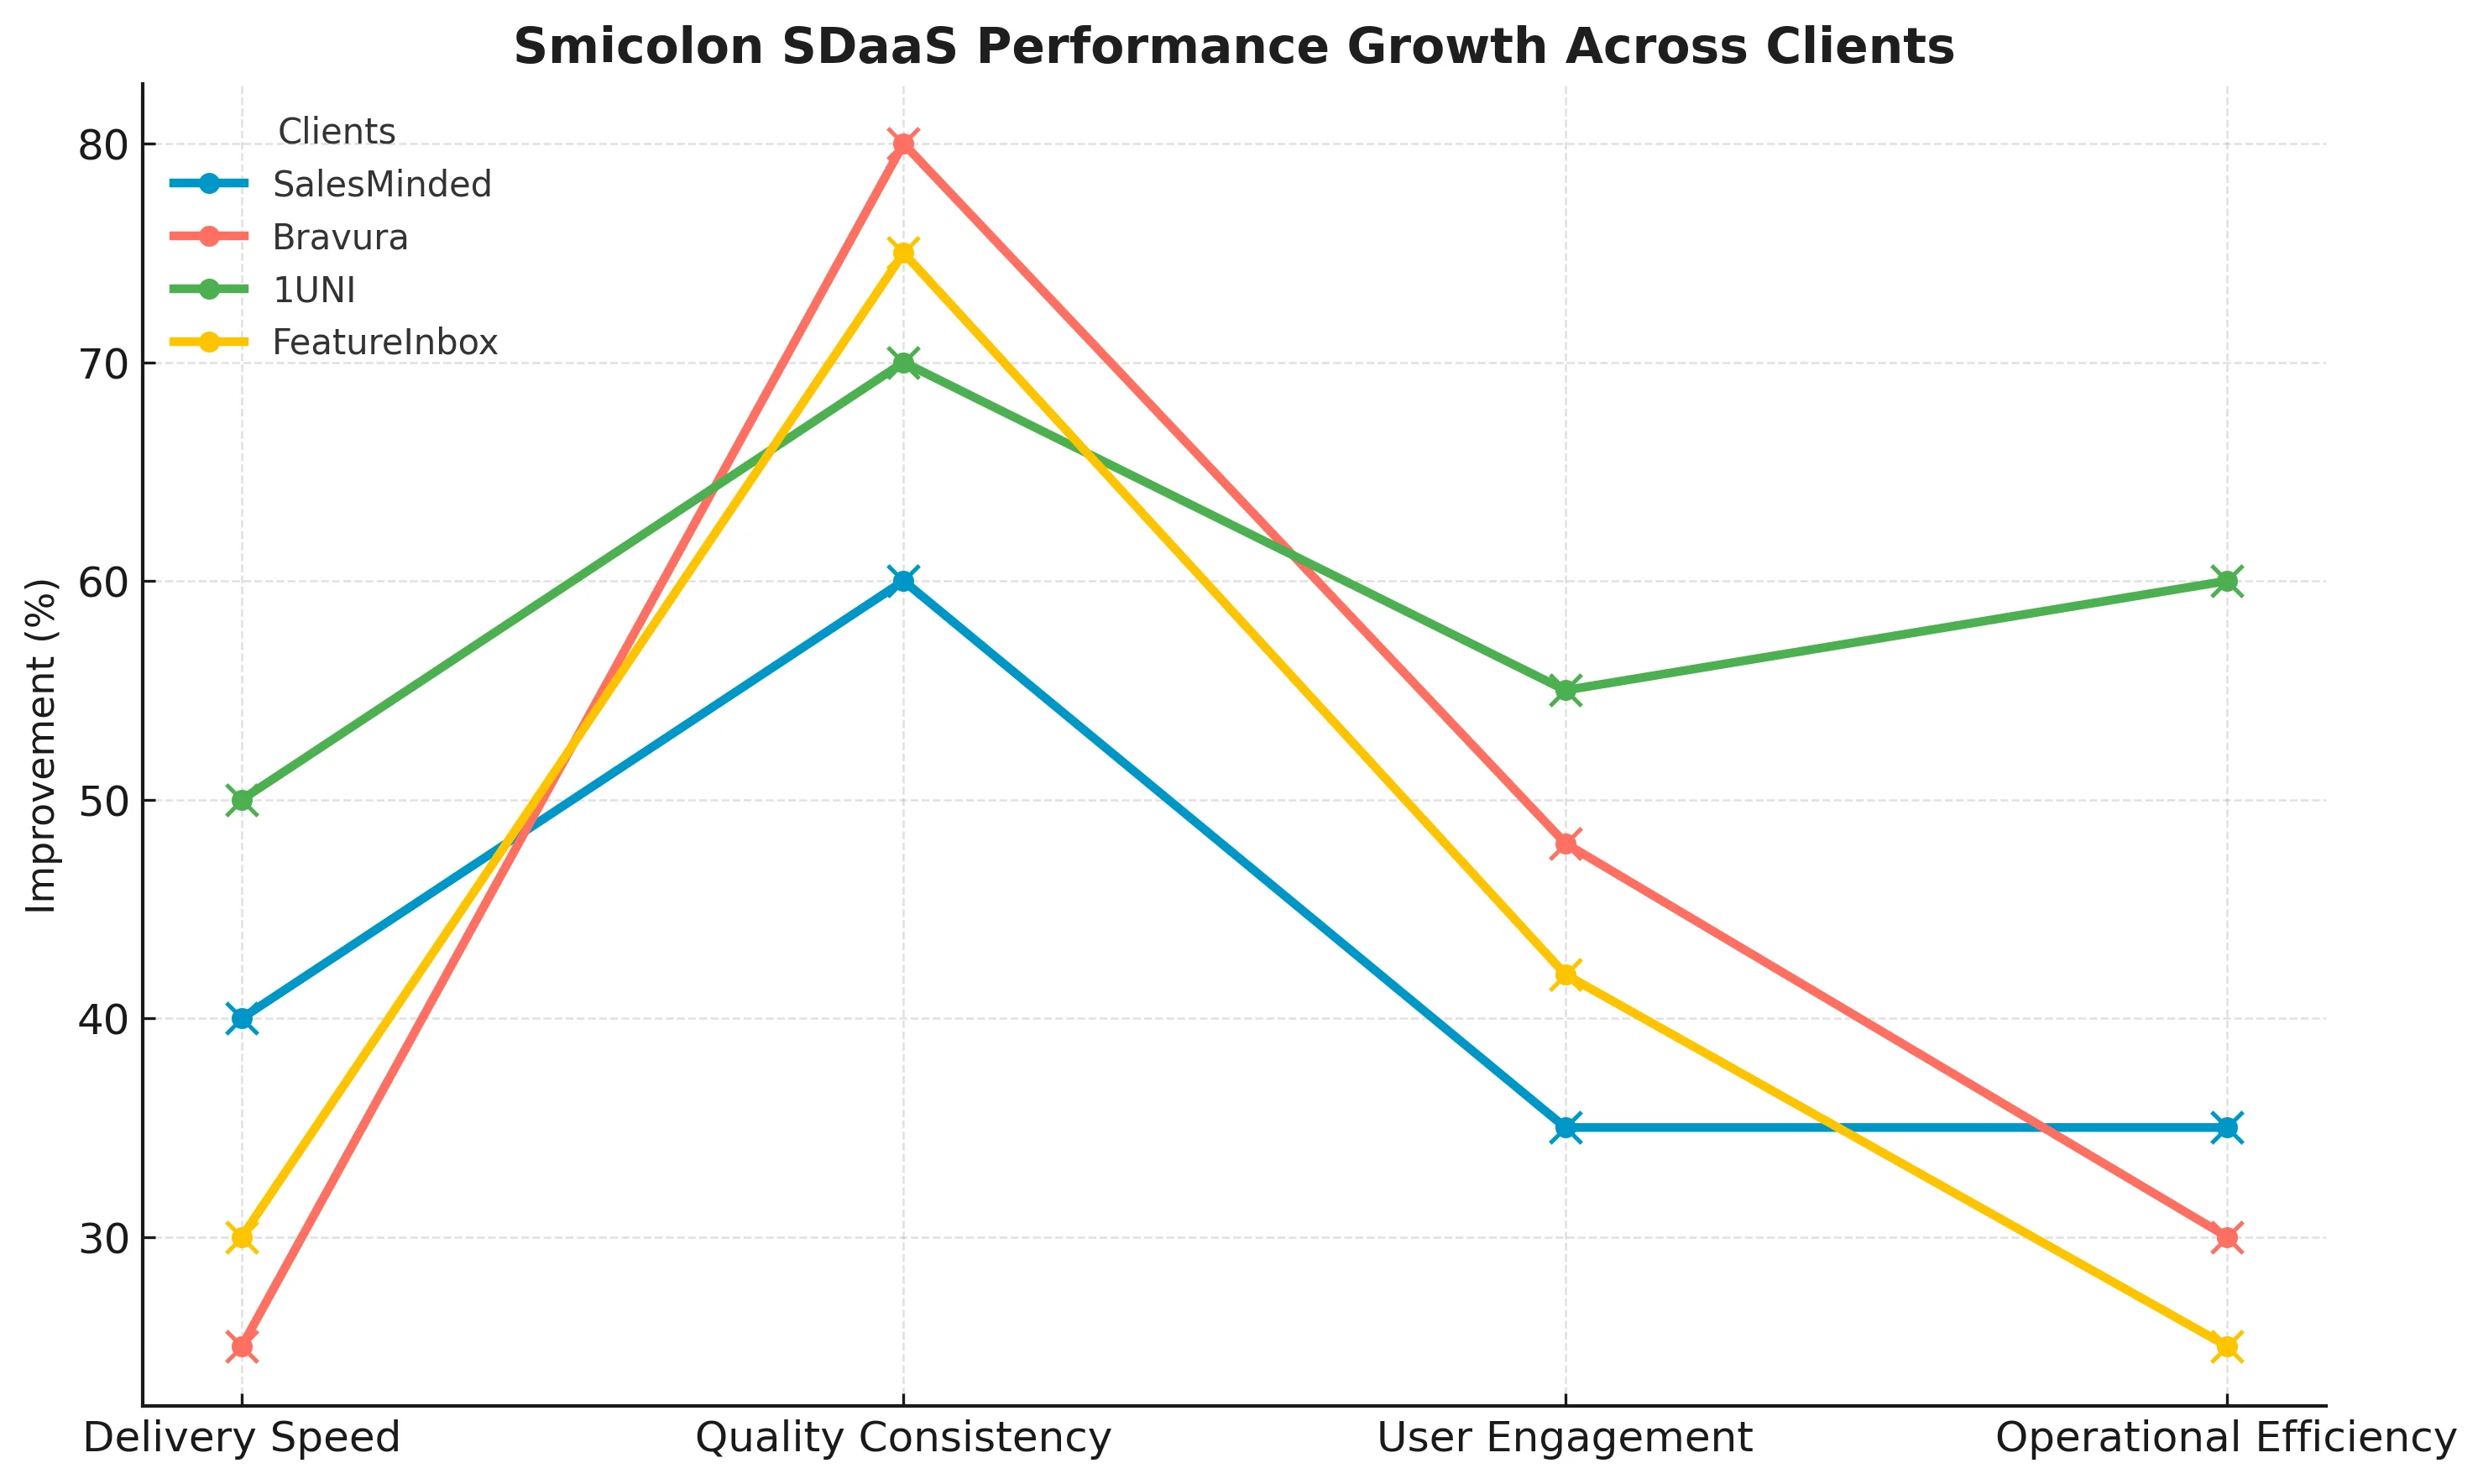
These aren’t projections — they’re real results from businesses that scaled faster and smarter with Smicolon.
Conclusion
Offshore software development didn’t fail because of talent — it failed because of disconnection. Brilliant ideas were lost in translation, trapped between time zones, and buried under layers of broken communication.
Smicolon’s SDaaS model was built to close that gap — uniting European engineering discipline with offshore efficiency and modern intelligence. We take pride in earning the trust of visionary founders and teams who choose Smicolon to turn their ideas into scalable, growth-driven products that make a real impact.
Smicolon GmbH — fixing what offshore broke and redefining what software development can be.
Your code is only as strong as the team behind it.
Build with engineers who take ownership, think ahead, and deliver with consistency.
Talk to a Smicolon pro →
Explore our Flexible SDaaS plans & Find the Perfect Fit for your Next Software Project.
See Our SDaaS Plans
---
# Why UX Matters: Business Success through Great Design
Source: https://smicolon.com/blog/why-ux-is-important-for-business
Updated: 2026-07-31T12:15:45.762Z
In today's digital age, user experience (UX) design plays a crucial role in the success of businesses. In fact, 52% of users say the main reason why they won’t return to a website is aesthetics, showing how important user experience (UX) design is for creating websites and digital products.
With an increasing number of consumers relying on websites and digital products, it is essential to prioritise UX design to provide a seamless and satisfying user experience. In this article, we will explore why UX design is important for business growth, from enhancing brand loyalty to increasing conversions and improving productivity. But before delving into the importance of UX design, let's first understand what it means.
What is UX Design?
UX design is a multifaceted concept that encompasses various disciplines such as interaction design, information architecture, visual design, and usability. It goes beyond creating visually appealing interfaces and focuses on ensuring a positive user experience:
Interaction Design
Interaction design involves designing intuitive interfaces that facilitate seamless interaction between users and the product. This includes elements such as buttons, touchscreens, and voice commands, aiming to make these interactions straightforward and rewarding.
Information Architecture
Information architecture is the science of organising and structuring information in a clear and understandable way. It helps users find what they need without obstacles, enhancing their overall experience.
Visual Design
Visual design plays a crucial role in creating the aesthetic appeal of a product. It encompasses colour schemes, typography, images, layouts, and graphics, all of which significantly influence a user's perception and experience.
Usability
Usability focuses on the ease of use of a product or service. It ensures that the product is user-friendly, easy to navigate, and functional. Usability testing is often conducted to gauge how user-friendly a product is and identify areas for improvement. At its core, UX design is about creating products that provide valuable and unique experiences for users. It prioritises the user's needs and preferences, aiming to exceed their expectations.
Why is UX Design Important for Business?
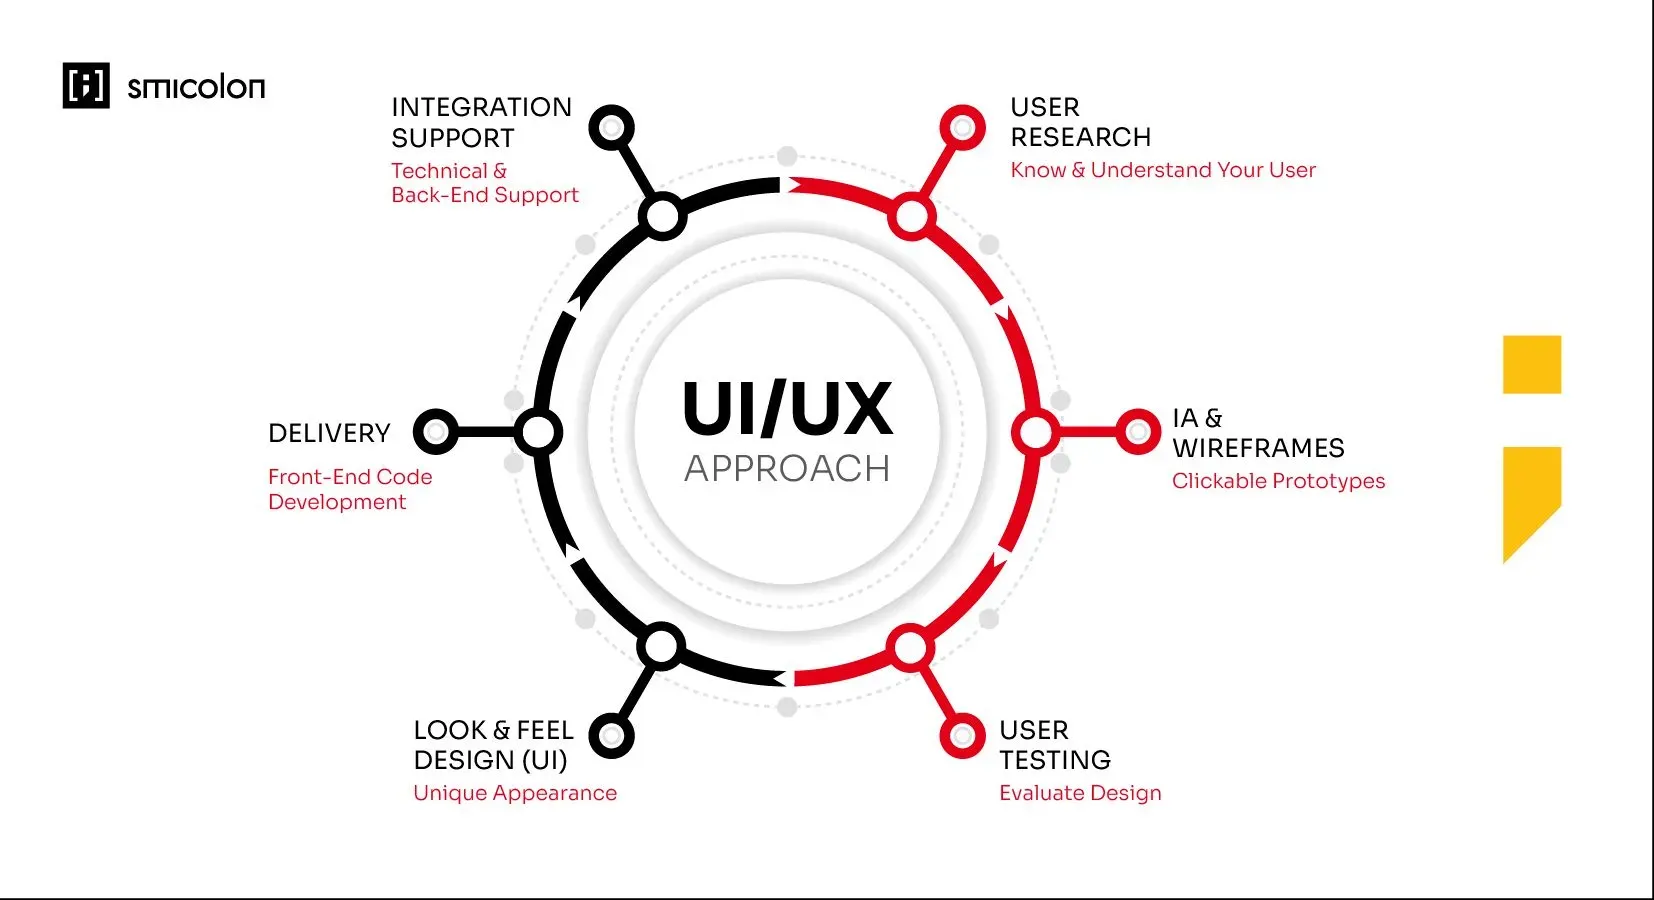 Now let's explore why UX design means for better business growth. Investing in UX design offers numerous benefits, ranging from increased return on investment to improved brand loyalty and customer satisfaction.
1. Higher Return on Investment
Investing in UX design at the early stages of a project significantly improves decision-making, design strategy, and the creation of effective solutions. By conducting UX research and understanding the needs of users, businesses can reduce the risk of failure.
To calculate the ROI of UX design, you can compare the initial investment in UX research and design to the subsequent reduction in risk and increased returns, with research by Forrester suggesting that every dollar invested in UX design yields a remarkable return of 100 dollars.
2. Improved Efficiency and Lower Costs
The iterative process of testing and validating designs and ideas ensures a good user experience and saves time and money. By understanding customer expectations and testing prototypes before full-scale production, businesses can reduce the risk of developing products that do not meet customer needs. This approach reduces time to market and ensures the delivery of cost-effective solutions.
3. Higher Conversions
A well-designed user experience can significantly impact conversion rates. A confusing and frustrating UX design can drive potential customers away, leading to missed opportunities for conversions. Thus, UX designers employ techniques to evaluate target groups, identify usability problems, and resolve pain points, ultimately increasing conversion rates. Research by Forrester also indicates that good UX can increase a website's conversion rate by as much as 200-400 percent.
4. Increased Brand Loyalty and Customer Satisfaction
A strong user experience builds trust, credibility, and long-term relationships with customers. It enhances brand loyalty and improves customer retention rates. By prioritising UX design principles, businesses can create satisfying experiences that positively impact their return on investment. Satisfied customers become loyal customers, leading to increased sales and sustained growth.
5. Improved Productivity
UX design aims to make tasks as effortless as possible for users, enhancing productivity. By prioritising intuitive work flows and minimising friction, UX design improves how people interact with your products and services. When businesses invest in UX design, they can increase productivity and gain an edge over competitors. It also leads to happier customers, who are more likely to spread the word about the positive experience they had.
6. Better User Retention
Last but not least, user experience plays a crucial role in retaining users and ensuring long-term engagement. UX designers create accessible designs that excite and engage users, increasing user retention. When users are genuinely excited about a product or service, they are more likely to continue using it and recommend it to others.
Conclusion
Investing in UX design is no longer a luxury; it is a necessity for businesses looking to thrive in the digital landscape. By prioritising user experience, businesses can unlock a range of benefits, from increased return on investment to improved brand loyalty and customer satisfaction. With the help of UX design experts, businesses can create enduring experiences that set them apart from the competition and drive long-term growth. Don't underestimate the power of UX design - it could be the key to unlocking your business's full potential.
How Can UX Design Help Your Business?
The benefits of UX design are clear, but how can you leverage this approach to enhance your business's growth? By partnering with experts in the field, you can unlock the full potential of UX design to create enduring experiences tailored to your target audience.
At Smicolon GmbH, we have a team of UX design experts who are skilled at identifying user experience problems and crafting effective UX strategies. We understand the importance of putting the user at the centre of everything we do, and our goal is to create exceptional experiences that drive business growth. For those keen to understand more, we offer insights into the differences and comparisons between UI and UX.
With our customised UX design solutions, you can:
Enhance customer satisfaction and loyalty through intuitive and user-friendly interfaces.
Increase conversions by optimising the user journey and eliminating pain points.
Improve productivity by streamlining workflows and minimising friction.
Retain users by creating engaging and accessible designs
Book a 30 min time-slot with Smicolon GmbH today to learn more about our UX design services and how we can help your business grow: https://calendly.com/mohamed-hussein-2/30min
---
# How to choose a web development company?
Source: https://smicolon.com/blog/how-to-choose-a-web-development-company
Updated: 2026-07-31T12:15:44.914Z
In today's digital age, businesses of all sizes are realising the importance of delivering transformative digital experiences to their customers. Web development has revolutionised the way we interact with the internet. It encompasses a wide range of technologies and processes that enable the creation of powerful and dynamic websites, web applications, and online services.
Custom web development plays a crucial role in achieving this goal. However, not all businesses have an in-house development team, which is where outsourcing to a web development company comes into play. But did you know that according to Statista, global spending for the outsourcing market is projected to reach $1,389 billion in 2023, a 33.56% growth over 5 years, indicating the demand for web development companies? Yup, it’s true!
But with so many web development companies out there, how do you choose the one that is right for your business? In this comprehensive guide, we will walk you through the process of selecting the perfect web development company that aligns with your unique needs and goals.
Why Do You Need a Web Development Company?
Before delving into the process of choosing a web development partner, it's essential to understand the reasons why you might need one. Here are some common scenarios where outsourcing web development can be advantageous:
Lack of In-house Expertise: If your business doesn't have a dedicated development team or lacks the necessary technical skills, outsourcing to a web development partner can provide the expertise you need to bring your vision to life.
Local Talent Shortage: Hiring and retaining top-tier developers can be challenging, especially for start-ups and businesses located in areas with a limited pool of IT professionals. Outsourcing allows you to tap into a global talent pool and access highly skilled developers.
Time-to-Market: Building an in-house development team from scratch can be a time-consuming process. Outsourcing allows you to accelerate your development timeline and get your product to market faster.
Budget Constraints: Hiring and maintaining an in-house development team can be costly, especially for start-ups and small businesses. Outsourcing offers a cost-effective solution, as you only pay for the services you need.
Unique Requirements: Some projects require specialised knowledge and experience that may not be available within your organisation. Partnering with a web development company that has expertise in your specific industry or technology can ensure the success of your project.
While there are instances where in-house development teams or off-the-shelf software solutions may suffice, outsourcing web development can provide a tailored and efficient solution for many businesses, such as yours.
The Process of Choosing a Web Development Partner
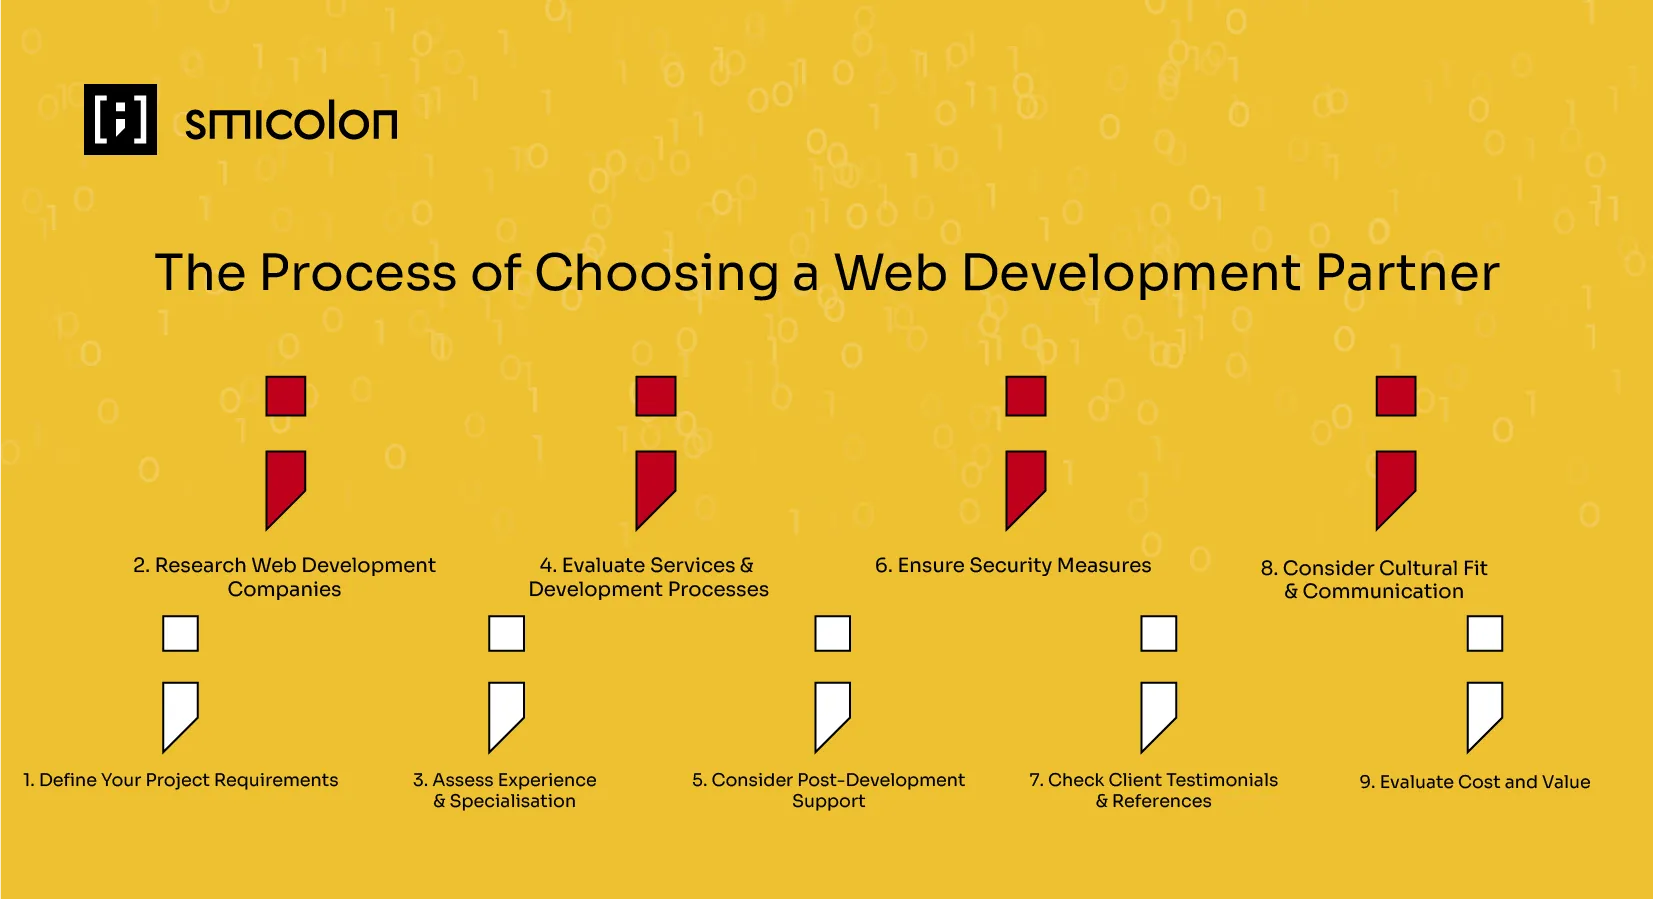
Choosing the right web development partner requires careful evaluation and consideration. Here are the key steps to follow in the selection process:
Define Your Project Requirements
Before you start searching for a web development partner, it's crucial to have a clear understanding of your project requirements. Define the scope, functionality, and desired outcomes of your project. This includes identifying your goals, target audience, and the specific features and functionalities you want your web application to have. This will help you communicate your needs effectively and ensure that potential partners can meet your expectations.
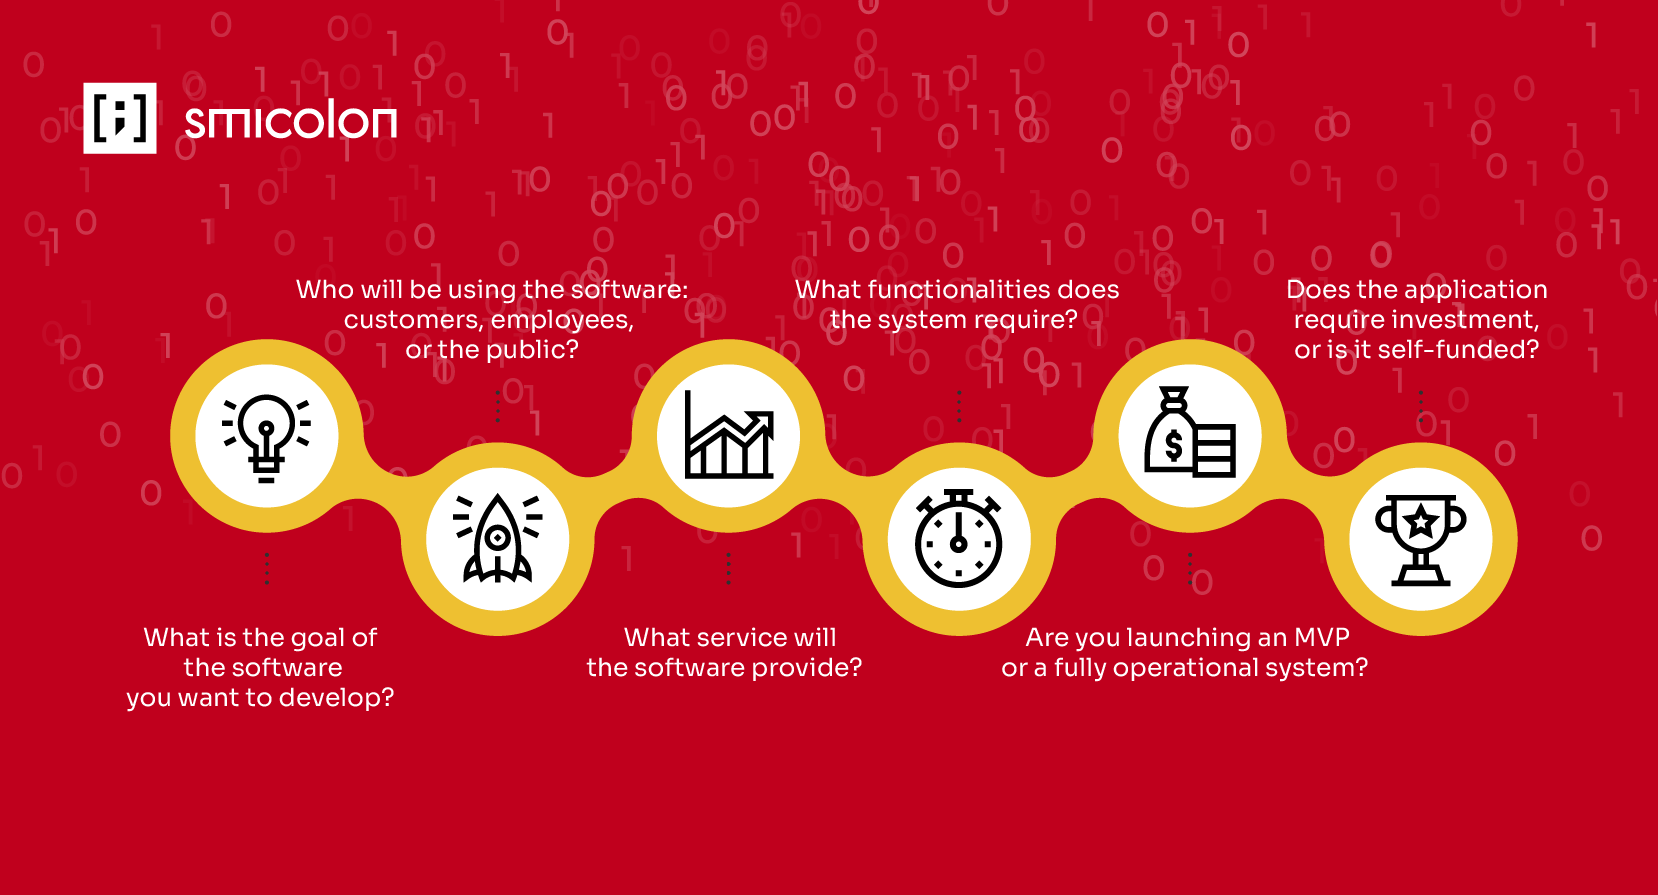
Consider creating a list of requirements, user stories, and basic mock-ups to provide a comprehensive overview of your project. By defining your business requirements upfront, you will have a solid foundation for evaluating potential web development companies and ensuring that they can meet your specific needs. This initial groundwork will save time and prevent miscommunication during the selection process.
Research Web Development Companies
Once you have defined your project requirements, it's time to research web development companies. Start by leveraging online resources such as search engines, directories, and industry-specific platforms to identify potential partners. Consider factors such as their industry focus, company size, experience, and services offered.
Additionally, seek recommendations from your professional network or industry peers who have previously worked with web development companies. Their first-hand experiences and insights can provide valuable guidance in the selection process.
Assess Experience and Specialisation
Evaluate each web development company's experience and specialisation to ensure their alignment with your project requirements. Review their portfolios and case studies to gauge their expertise in similar projects. Look for evidence of successful implementations, industry-specific knowledge, and technical capabilities relevant to your project.
Consider the technologies and frameworks they specialise in, as well as their ability to adapt to emerging trends. A web development partner with experience in your industry and technology stack will have a deeper understanding of your challenges and requirements.
Evaluate Services and Development Processes
Assess the range of services offered by each web development company. Evaluate their development processes, methodologies, and quality assurance practices. Look for companies that follow industry best practices such as Agile development, iterative testing, and continuous integration.
Good communication and collaboration are critical for successful web development. Ensure that the web development company has effective communication channels and project management tools in place. Clear and transparent communication will help facilitate a smooth development process and ensure your project stays on track.
Consider Post-Development Support
Web development is an ongoing process, and post-development support is crucial for maintaining and enhancing your web development solution. Inquire about the web development company's post-development support offerings, such as bug fixes, updates, and maintenance.
A reliable web development partner should be committed to long-term support, ensuring that your web app remains functional and up-to-date. Additionally, discuss their approach to handling future changes and scalability to accommodate your evolving business needs.
Ensure Security Measures
Security is of paramount importance when outsourcing web development. Inquire about the security measures and protocols implemented by each web development company to protect your sensitive data and intellectual property.
In addition to general security inquiries, it is highly recommended to discuss the use of Non-Disclosure Agreements (NDAs) and intellectual property protection, particularly if you are engaging with an overseas web development agency. Ensure that the company you choose has robust measures in place to prevent code leakage or theft, as this can be a critical concern. It is essential to address these aspects to guarantee comprehensive protection for your assets and data.
Furthermore, ask about their data protection practices, encryption methods, and their compliance with industry standards. A reputable software development partner should prioritise data security and have stringent measures in place to mitigate potential risks to your intellectual property.
Check Client Testimonials and References
To gain further insights into each web development company's capabilities and reputation, review client testimonials and references. Look for feedback from previous clients to gauge their satisfaction with the company's services, communication, and overall project outcomes. If possible, reach out to their past clients to obtain first-hand feedback and recommendations. This will provide you with a more comprehensive understanding of their strengths and weaknesses.
Consider Cultural Fit and Communication
Working with a web development partner requires effective communication and collaboration. Assess the cultural fit and communication style of each company. Consider factors such as time zone differences, language proficiency, and responsiveness. Choose a partner that aligns with your organisational culture and values, as well as one that can effectively communicate and understand your requirements. This will foster a productive and collaborative working relationship throughout the development process.
Evaluate Cost and Value
While cost is an important factor, it should not be the sole determinant in choosing a web development partner. Evaluate the cost structure and pricing models of each company, considering factors such as hourly rates, project complexity, and ongoing support costs. Focus on the value that each web development partner can provide rather than solely on the cost. A partner that offers a balance of quality, expertise, and competitive pricing will ultimately deliver the best return on investment.
Benefits of Custom Web Development For Your Business
If you're considering enhancing your business operations with a software solution but are unsure which category suits you better, understanding the benefits of tailor-made software will help you make an informed decision on which partner to choose.
Personalisation: Tailored Solutions for Unique Challenges
Custom applications offer a distinct advantage in terms of personalisation. Unlike off-the-shelf software that caters to a broad audience, tailor-made solutions are built to fit your specific project requirements. By developing software exclusively for your business needs, you can establish a leading position in your industry and gain a competitive edge.
Working with an experienced web development company allows you to address your unique challenges and deliver exclusive advantages. The custom solution built for your business will include features and technologies of your choice, ensuring that your project stands out from the crowd.
Cost-Effectiveness: Long-Term Value and Budget-Friendly Options
While off-the-shelf software may initially seem like a cost-effective option, it often comes with recurring expenses that diminish its long-term value. These ready-made apps typically require customisation to effectively support your operations. Over time, you may find that they lack essential functionality, leading to the development of entirely new software from scratch. Additionally, hidden costs can emerge if you need to scale up your project.
On the other hand, for many corporate users, a primary concern when relying on third-party, off-the-shelf apps is the prospect of the software provider being acquired by another entity. This scenario can result in the abandonment of the software, leaving users without ongoing support or updates. Furthermore, the fear of sensitive data falling into the hands of an unfamiliar company, especially in cross-border acquisitions, like a Chinese company purchasing a U.S. software firm, is a significant apprehension for both U.S. and EU businesses.
High Security & Reliability: Safeguarding Sensitive Data
Custom software is known for its reliability, as it is designed to meet the highest security standards and utilise cutting-edge technologies specific to your business and industry. This is especially relevant for industries like healthcare, insurance, and fintech, where security standards and regulatory compliance are crucial for safeguarding sensitive data. The development of tailored solutions entails a comprehensive analysis of your requirements, incorporating industry best practices and considering potential hidden risks and challenges. Through rigorous testing, custom software becomes less susceptible to intrusions and more likely to perform with high reliability, ensuring maximum value for your business.
Continuous Support & Maintenance: Maximising Value and Minimising Risks
Another key benefit of a custom web app is the continuous support and maintenance provided by your dedicated web development partner. In case you encounter any issues, they can efficiently provide technical support and make necessary updates or tweaks to the software. This level of personalised attention is not typically available with off-the-shelf solutions, where you are dependent on product providers to fix issues or deliver updates. Additionally, renewals that are essential to your company's operations may come with additional costs, and sometimes, providers may even stop supporting the product, negatively impacting your business operations.
Flexibility & Scalability: Adapting to the Ever-Changing Business Environment
In today's fast-paced business world, staying competitive means constantly adapting to the ever-changing environment. While off-the-shelf solutions may offer a quick fix for current needs, they often fall short in the long run, lacking the flexibility and scalability that companies seek to accommodate their shifting needs.
Custom software, on the other hand, supports it all. Through thorough analysis during the discovery and prototyping phase, different scenarios can be considered, even as business needs evolve over time. Custom tech tools offer the necessary flexibility and scalability to consider any future requests, whether it's adding new features, increasing product capacity, or supporting the growing demands of a company.
Seamless Integration: Enhancing Business Operations with Efficient Communication
Today, software tools play a vital role in ensuring the smooth functioning of almost any business operation. The efficiency of these tools largely depends on their ability to communicate with each other to provide desired outcomes.
Custom-tailored solutions offer a significant advantage over template alternatives, as they support a high level of integration. Custom solutions are designed to match the existing systems and processes that a company employs, offering real-time visibility into business operations, enabling accurate data management and analysis. Custom tools can streamline business operations, automate work flows, and empower informed decision-making.
Increased Productivity: Custom Solutions for Enhanced Efficiency
Custom software is designed exclusively to address your goals and consider all of your tech and business requirements, leading to increased productivity within your company. Employees will spend less time on daily operations, gain more insights while working with data, and manage multiple activities simultaneously.
Additionally, as your team achieves better efficiency and productivity through custom software solutions, you can expect to see a positive impact on your bottom line, further enhancing the overall performance and growth prospects of your business.
Exclusive Ownership: Full Control and Freedom to Adapt
Custom-built software gives your company exclusive ownership and control over the product. This means you have the flexibility to make changes and leverage its full potential according to your business needs, without any restrictions imposed by licence fees, rules, and regulations. In contrast, off-the-shelf solutions often come with limitations that can restrict how you use them. Custom-built software eliminates such limitations, offering complete freedom and flexibility to adapt and evolve alongside your business.
Conclusion
Choosing the right web development partner is a critical decision that can significantly impact the success of your project. By following the steps outlined in this guide and conducting thorough research, you can make an informed choice that aligns with your project requirements and business objectives. Remember to prioritise expertise, communication, cultural fit, and long-term support to ensure a successful partnership and the delivery of a high-quality custom web application solution.
The Role of Smicolon GmbH in Custom Web Development
Smicolon GmbH is an IT software company that offers tailor-made solutions to businesses of all sizes. With a team of skilled and experienced developers, we provide high-quality web development services. The development process at Smicolon GmbH is highly collaborative, ensuring that businesses receive the perfect solution that fits their unique requirements.
We not only specialise in delivering exceptional services but also focus on quality and customer satisfaction. By leveraging the power of Smicolon GmbH, businesses can use custom software development to drive success and provide a competitive edge.
After all, it’s time to embrace the power of custom web application development and unlock the endless possibilities it offers for your business's growth and success.
Contact us today to embark on your custom web development journey
---
# High Quality AI-Generated Code Speeds Up Development but Struggles with Long-Term Maintenance
Source: https://smicolon.com/blog/ai-generated-code-quality-maintenance
Updated: 2026-09-27T01:21:26.447Z
Why Is AI-Generated Code Hard to Maintain?
AI-generated code is hard to maintain because the tool writes the code but not the reasoning behind it. When another developer has to change it later, they first have to work out why it was built that way, often without tests that show what it is supposed to do. Code accepted without careful review also tends to repeat existing logic and drift away from the structure of the system, so every change touches more than it should.
A Practical Review Checklist
Before AI-generated code is merged or handed over, check four things:
Tests: the main behaviour and the likely failure cases are covered by tests that run on every change. If nobody can say what a test proves, it does not count.
Ownership: a named person has read the code and can explain what it does, which business rules it protects, and what depends on it.
Architecture: the code follows the patterns the system already uses. It does not repeat logic that already exists, add a library for something the codebase already handles, or reach across module boundaries.
Handover: the reasons behind important decisions are written down next to the code, so the next developer does not have to guess them.
With modern AI tools, developers can move quickly from idea to execution, especially in the early stages of development. Tasks that once took hours can now be done in minutes, as AI handles much of the groundwork automatically. That visible speed makes it tempting to believe that software development itself has become easier. However, faster development alone cannot sustain AI-generated code quality over time.
Getting the first release out the door is just the beginning. Most of a developer’s time is spent understanding and working with existing code rather than building new features from scratch. That code is often maintained by engineers who were not involved in the original implementation. Once that transition happens, speed is no longer the deciding factor. Long-term maintainability and engineering discipline start to define the outcome.
At this stage, maintaining strong AI-generated code quality becomes less about speed and more about structure and review. Clear structure, consistent standards, and careful decisions make changes safer and less disruptive. Without that foundation, even well-written code becomes harder to maintain as complexity increases. Maintaining stability over time still relies on deliberate engineering practices.
This article looks at how software development actually changed after AI-assisted tools became widely used, what improved immediately, and what did not. It explores what happens when AI-generated code changes hands, corrects common assumptions, and explains why developer skill remains the strongest factor in long-term software quality. It also shows how AI shifts effort earlier in the lifecycle without removing it.
The goal is not to question AI’s value, but to set realistic expectations about where speed helps and where engineering still does the heavy lifting.
How Software Development Looked Before and After AI-Assisted Tools
Before AI-assisted tools entered everyday development workflows, a large portion of a developer’s time was spent on predictable yet unavoidable tasks. Setting up a new feature meant writing boilerplate from scratch, wiring CRUD operations, drafting initial tests, and documenting basic behaviour. Progress happened, but it often felt slow at the start. Real problem-solving usually came only after hours or days of groundwork.
After AI-assisted tools became widely used, that early phase started to look very different. Tasks that follow common patterns, such as generating basic endpoints, form handling, unit test scaffolding, or documentation drafts, can now be produced almost instantly. Developers no longer need to start from a blank file for routine work. Instead, they begin with a rough first version and refine it.
This shift has a noticeable impact on speed, especially early on. Many teams report that routine coding tasks take significantly less time with AI assistance, which allows them to reach a working version faster. That is why AI is often described as a productivity boost. It compresses the setup and repetition that used to dominate the beginning of a project. This pattern is also evident in Jellyfish’s article on the benefits of AI in software development, where AI shows its strongest impact on repetitive and early-stage work.
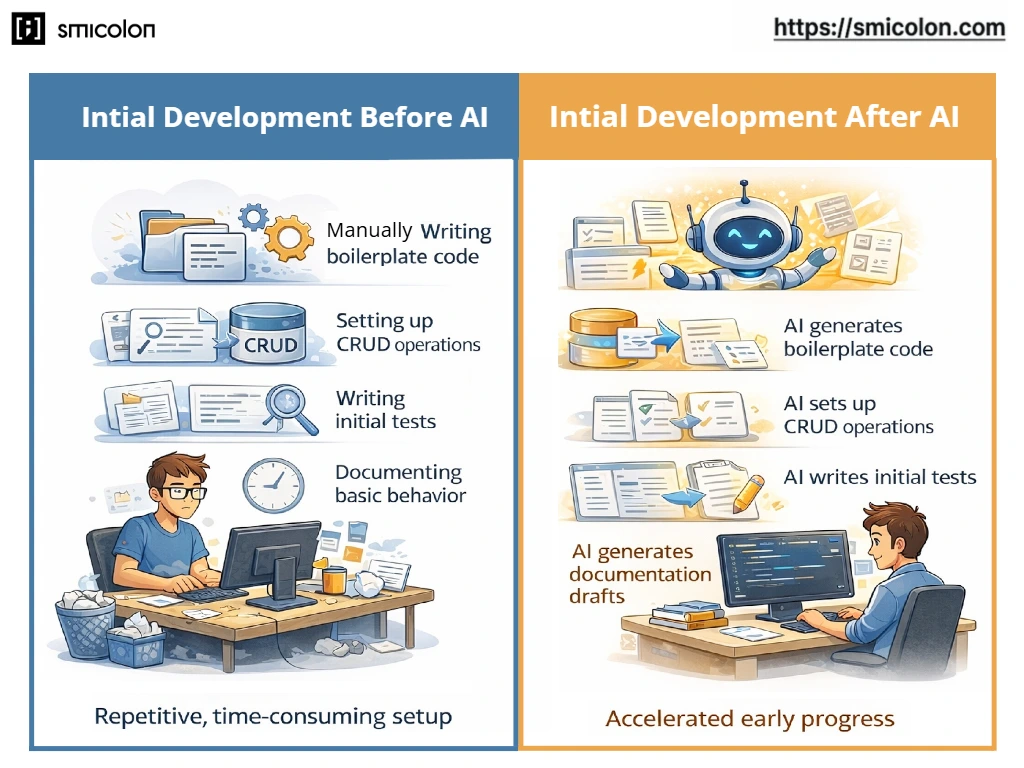
This difference is most visible when teams are building early versions or MVPs. Before AI, teams often spent weeks on setup before they could get anything usable in front of users. With AI-assisted tools, teams can assemble a first version much sooner, test ideas earlier, and iterate faster. That early momentum feels real, and it is.
But this does not mean the entire development process suddenly becomes faster. AI is strongest where patterns already exist. It helps most with repetition and first drafts, not with deciding what should be built or how a system should evolve. Developers still need to review what AI produces, adjust it to fit their codebase, and decide whether it actually makes sense.
In short, AI-assisted tools reshape the early stages of software development by reducing setup effort and speeding up initial progress. This makes it easier to get started and iterate sooner. How that speed holds up once software moves beyond its first version is a separate question.
What Happens to AI-Generated Code Quality When Code Changes Hands
In the software development lifecycle, the nature of the work shifts once AI-generated code changes hands. This usually happens when a different developer steps in to update or extend a feature that was originally built by another developer. In that situation, speed becomes less important, and understanding and changing the code becomes the priority.
This is the point where the limits of AI in software development become clear. AI can generate working code, but it doesn’t capture the reasoning behind those decisions. When that reasoning isn’t clear in the code, the next developer has to reconstruct it before making even small changes.
By the time software reaches this stage, speed is no longer the primary concern. The work shifts away from writing new code toward understanding existing behaviour, validating changes, and preventing regressions. Developers spend more time reading, reasoning, and testing than implementing. That effort does not shrink just because AI was used earlier.
Most maintenance effort is spent building understanding rather than producing new code. Developers need to reconstruct intent, trace data flow, and reason about existing behaviour before they can safely make changes. This work is unavoidable, regardless of whether the original code was written manually or generated with AI.
As systems grow, this effort increases. Dependencies multiply, side effects become harder to spot, and even small changes require broader context. At this point, maintainability is shaped by how readable and well-structured the system is, not by how quickly the first version was created.
Test coverage becomes especially important at this level. Reliable tests reduce uncertainty and give developers confidence when making changes. Without them, maintenance becomes slower and riskier, regardless of whether the code was written by a human or generated with AI.
Therefore, AI does not make software easier or harder to maintain on its own. What determines long-term maintainability is how systems are structured, reviewed, and tested over time. When that relationship between speed and structure is misunderstood, teams often assume that improvements in early development automatically translate into improvements across the entire lifecycle. These patterns often lead to common assumptions about what AI has actually changed in software development.
Myth vs Reality: What AI Really Changes in Software Development
This section breaks down the most common assumptions teams make about AI use cases in software development and contrasts them with how AI actually changes the work. Let’s look at the most common ones and separate perception from reality.
Myth: AI makes software development fast from start to finish. Reality: AI speeds up specific parts of development, not the entire lifecycle.
This is probably the most common assumption teams make after adopting AI tools. AI can generate code and documentation quickly, which creates the impression that the entire development process has sped up. Research from McKinsey shows that developers using generative AI can write code 35–45% faster, refactor code 20–30% faster, and produce documentation more quickly during the early implementation stages. That visible speed often leads to the expectation that if writing code is faster, everything that follows should be faster too.
However, the same research makes an important distinction. These gains are task-specific and appear primarily at the start of development. Later work, such as understanding existing systems, reviewing changes, coordinating with other developers, and maintaining software, does not speed up in the same way. AI does not eliminate the effort required to understand and safely evolve existing code. The software development process still slows wherever judgment, coordination, and deep understanding are required.
Myth: If AI writes the code, maintenance effort will be lower. Reality: AI does not reduce maintenance effort on its own; engineering decisions do.
This is another assumption that arises as teams use AI for longer periods. When AI can produce working code in seconds, it feels reasonable to expect that the same code will also be easier to maintain later. If less effort went into writing it, many teams assume less effort will be needed to understand and change it over time. This assumption often overlooks AI code quality concerns that surface over time.
In reality, maintenance effort still depends on human judgment rather than AI output. Despite widespread AI adoption, the Stack Overflow Developer Survey 2023 shows that many developers do not fully trust AI-generated code without reviewing it carefully. GitHub’s “Speed is nothing without control” article also points out that while AI accelerates code production, long-term code health relies on clear engineering decisions and guardrails rather than speed alone. Together, these insights highlight that AI can speed up writing code, but it does not reduce the effort required to maintain it responsibly.
Myth: Using AI reduces the need for experienced developers. Reality: AI makes developer skills more visible, not less important.
This assumption often comes from watching AI handle tasks that once required senior input, such as generating code, suggesting fixes, or drafting tests. When AI can produce solutions quickly, it’s easy to assume that experience matters less and that junior developers can now deliver the same results with the right tools.
In practice, experience becomes more important as responsibility shifts from execution to judgment. METR findings reported by InfoQ show that AI shifts effort toward review and judgment, reinforcing the importance of experienced developers. As AI takes on more execution work, experienced developers become responsible for evaluating whether the generated code fits the system, handles edge cases correctly, and can be safely maintained over time. Rather than replacing senior expertise, AI makes the impact of those decisions more visible across the system.
AI-Generated Code Quality Depends More on Developer Skill Than AI Usage
As AI becomes more capable, the deciding factor in software quality is no longer the tool, but the developer using it. The quality of their output is shaped by how developers use them, the decisions they accept, and the standards they enforce. This is why developer skill continues to play a larger role than AI usage itself, especially when integrating AI into real-world development workflows.
When experienced developers work with AI, they tend to apply judgment at every step. They review generated code critically, adapt it to fit existing structures, and align it with long-term design goals. AI becomes a support tool in their workflow, not a substitute for thinking. In these cases, the resulting code is usually easier to understand and change later.
Less experienced developers often interact with AI differently. Generated code is often used as it is, with little review or cleanup to make sure it fits well with the rest of the system. While this can temporarily boost developer productivity, it also increases the risk of unclear logic and weak foundations. Over time, this makes changes harder and slows teams down.
This difference shows up most clearly in code quality. AI can produce syntactically correct code, but it does not decide how responsibilities are split, how components interact, or how changes should be isolated. Those decisions depend on the developer’s understanding of the system. Strong developers use AI to reinforce good practices, while weaker practices are simply amplified when AI is used without care.
When teams apply disciplined engineering standards, AI outputs are typically treated as drafts rather than final results. Developers review what was generated, adjust it to fit existing patterns, and ensure it aligns with how the system evolves in order to reduce AI code quality issues. When that step is skipped, speed can hide problems rather than solve them. Code may work at first, but small design shortcuts tend to pile up. Over time, they turn into technical debt in AI coding and make later changes harder and more expensive.
Strong engineering practices play a central role in protecting overall AI code quality as systems evolve. In fact, AI acts as a multiplier, making good engineering more efficient and exposing weak engineering more quickly. Over time, outcomes like maintainability, reliability, and confidence when making changes continue to depend on developer skill rather than the tool used to write the code.
However, this pattern is not limited to individual developers. It reflects a broader shift in how work is distributed across the software lifecycle. To understand why speed does not reduce responsibility, we need to look at where AI actually concentrates effort.
AI Redistributes Effort Across the Lifecycle, It Doesn’t Eliminate It
What changes with AI is not the total amount of work required to build software, but when that work becomes visible. AI accelerates the early stages by reducing the time it takes to produce working code, yet the system’s underlying complexity remains. Architecture still needs to be defined, trade-offs still need to be evaluated, and dependencies still need to be coordinated.
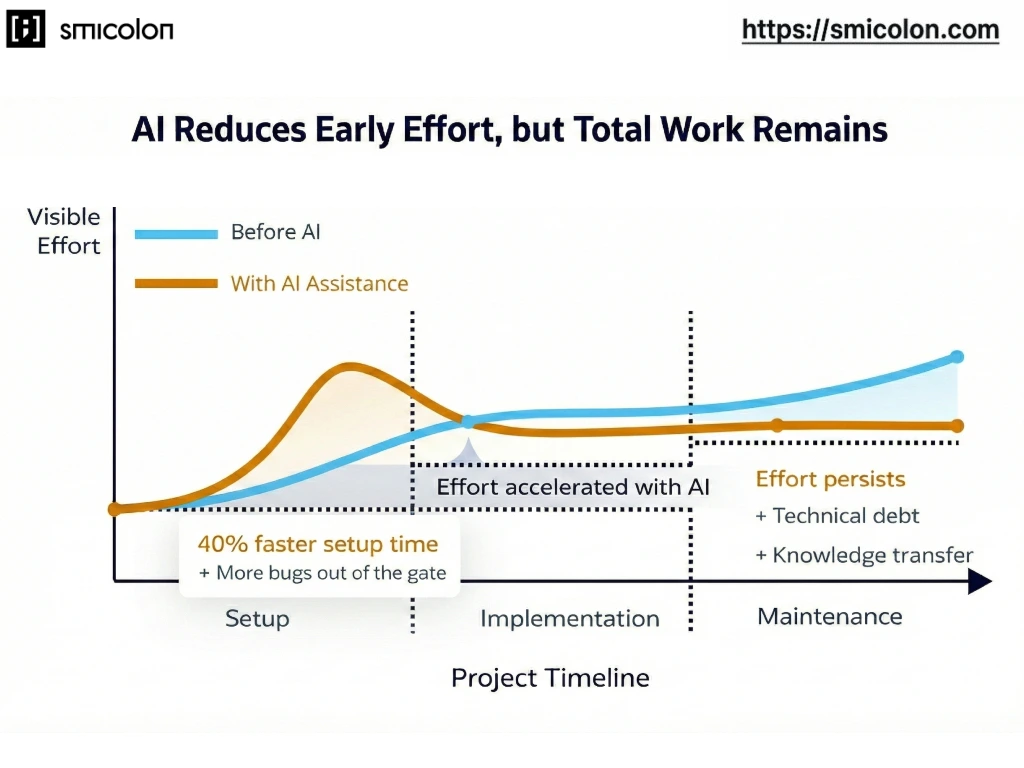
The chart illustrates how AI compresses effort during the setup and early implementation phases while leaving later stages largely unchanged. Although visible effort shifts forward, the overall responsibility across the lifecycle remains. Faster beginnings do not eliminate architectural complexity or long-term system care.
In practical terms, implementation may feel easier, but the work does not disappear. Teams can ship features faster, but they also have more code to review, more decisions to align, and more moving parts to manage. As output increases, so does the amount of code that must be understood and maintained.
This is why redistribution matters more than raw speed. When effort concentrates at the beginning, later stages absorb the impact. Validation becomes more critical, communication requires more attention, and design clarity becomes more important. If these areas are weak, acceleration quickly exposes them.
Teams often experience strong early momentum followed by familiar structural demands. Time saved during implementation reappears as coordination, reasoning, architectural upkeep, and long-term system care. Instead of the overall workload being reduced, it simply moves to a different stage of the lifecycle.
Recognising this shift helps teams focus on the real risks. As output grows, review discipline and architectural clarity must grow with it. Mature teams often introduce structured reviews and, in some cases, AI-driven technical debt analysis to manage complexity. AI may change the pace of development, but maintaining coherent, sustainable systems still depends on engineering discipline.
Conclusion
AI has played a crucial role in the evolution of software development, reshaping workflows, collaboration, and how teams approach the design and maintenance of systems. Before AI-assisted software development, reaching that point required long hours of repetitive groundwork just to get started. Developers wired features manually and built the structure from scratch before real progress could begin. The pace was deliberate, and much of the work was mechanical.
AI has clearly altered the rhythm of software development. Work that once required steady, incremental effort can now move forward with less visible friction. Early progress feels more fluid, and momentum builds faster. But that shift in pace does not remove what follows. As software evolves, complexity accumulates and small decisions compound, making clarity and consistency harder to preserve over time.
Improving code quality with AI in software development is not automatic. The responsibility for shaping how a system holds together over time still rests with engineers. The long-term AI-generated code quality of a system depends on the decisions they make about structure, trade-offs, and change management. AI can reinforce disciplined engineering practices, but it cannot replace the judgment required to keep systems coherent, maintainable, and sustainable as they evolve.
AI helps build. Engineering ensures it lasts.
At Smicolon, we bring both together to design systems that move fast and evolve responsibly.
See how Smicolon builds AI-powered systems
---
# What Are Billable Hours? & How the Hour Bank System Works Inside the SDaaS Model
Source: https://smicolon.com/blog/smicolons-guide-to-billable-hours-and-hour-bank-system
Updated: 2026-07-31T23:28:03.066Z
To understand how billable hours work in an SDaaS framework, you first need to see how the hour bank system organizes and tracks your hours each month. While it may sound technical at first, the Smicolon approach makes the entire structure much easier to understand. According to the GitLab Global DevSecOps Report, more than 40% of software teams face delivery slowdowns due to unclear or inefficient workflows, which is why having a predictable structure like the hour bank system makes such a meaningful difference inside SDaaS.
With that understanding, you can easily see how much development time you have each month and how that time supports your project. This means you no longer have to guess where your team’s time is going — you begin the month with a specified amount of time that’s clearly set aside for your project. All types of work, including planning, coding, testing, communication, reviews, and even design tasks, can fit naturally into this setup, making everything easier to understand and manage as the work progresses.
Since your development time is already planned, the team can start working right away without waiting for new quotes or approvals. This avoids delays, keeps progress steady, and makes it easier to adjust priorities as your project evolves. Your usage tracking is always visible, and you receive updates as you get closer to using most of your hours. It works much like any professional billable hours system, giving you a dependable system you can rely on throughout the process.
In this blog, you'll get a complete picture of how your hour bank system works every month, what counts as billable hours, how your usage is tracked, and what your options are when your hours are fully consumed. You'll also learn how Software Development as a Service uses this model to deliver a more predictable and client-friendly development experience. If you are new to this concept, our SDaaS guide can help you build a quick foundation. Once you have that context, you’ll see how the hour-bank structure and SDaaS model work together to deliver smoother progress, clearer visibility, and a far more reliable development experience overall.
Understanding Your Monthly Hour Bank
Your Monthly Hour Bank is simply the set of prepaid development hours that come with your SDaaS subscription, and, as Workmeter describes, it’s essentially a structured way to manage hours within a defined balance. This setup aligns with how we allocate your time and gives you a clear starting point each month.
When you pick a plan — Start (80 hours/month), Grow (160 hours/month), or Scale (240 hours/month) — that number of hours is reserved for you every month. You can compare these options on our Subscription Plans page.
Once your plan is selected, these hours are released from your larger prepaid hour bank, which you receive upfront when you purchase your package. This is guided by the hour bank system, which manages how your hours are distributed each month.
Think of it this way:
Hour Bank: total prepaid hours for the entire commitment period
Standard Monthly Hours: the hours released each month for active development
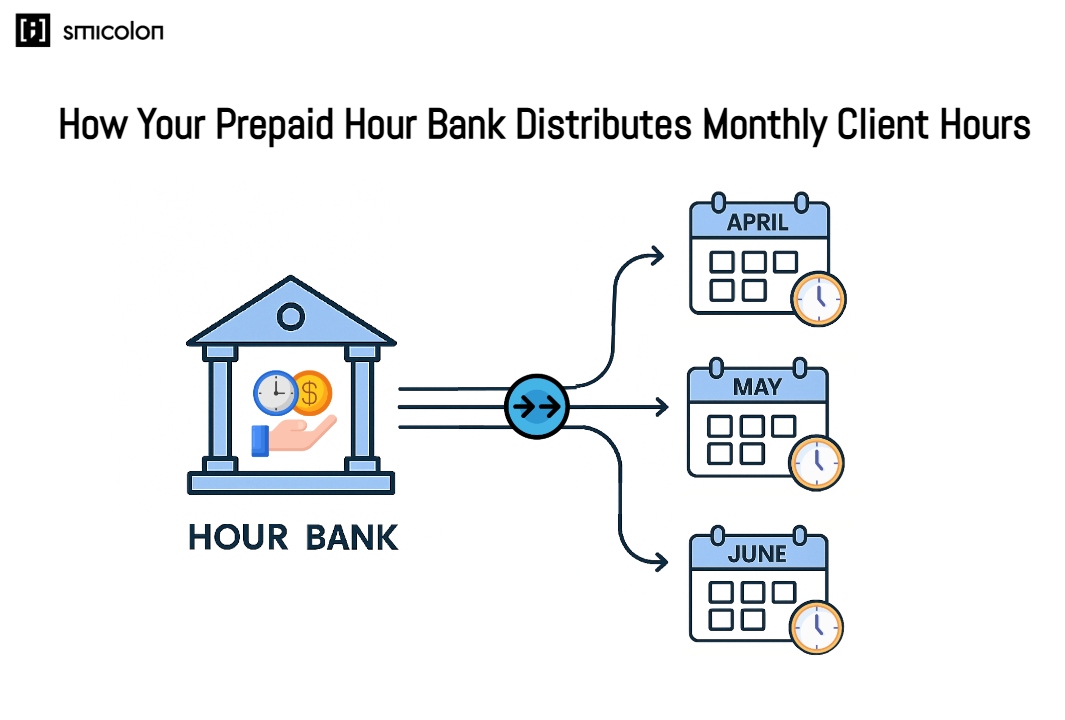
Your hour bank is the total pool of discounted, prepaid hours included in your commitment period. This bank sits in the background as your master balance. Each month, a fixed number of hours from your plan (80, 160, or 240) is deducted from this pool. Those hours fuel all the essential work that moves your project forward — planning, coding, testing, debugging, communication, documentation, and design tasks if you’ve added design add-ons. And if you use up your monthly hours early, you still have leftover hours stored in your hour bank, ready for you to decide how to use them.
From this hour bank, your standard monthly hours are released — this becomes your monthly operating balance. It’s the set amount of time your team works with each month, and everything they do is pulled from this balance.
This structure keeps things predictable and gives you a clear, real-time view of your monthly usage as the month progresses. Because every hour goes directly into active development work, you always know how your billable hours are being used and what your team is focusing on. This setup gives you steady monthly capacity while still showing you how your prepaid hours flow throughout your SDaaS engagement.
How the Hour Bank System Works Each Month
How Your Monthly Hours Are Used
Once your monthly hours are set, the Smicolon team just starts using them as they work on your project. The time they spend on any part of the work is deducted from your hour balance. Since everything is already prepaid, the team doesn't need to pause for new quotes or approvals. Tasks move forward within your existing balance, which keeps momentum strong and helps prevent delays. Throughout the month, your hour bank acts as your project's "fuel tank,” giving you a clear view of your usage tracking as work continues.
What Counts as Billable Hours
Billable hours include all the time the team spends actively working on your project. This covers the whole process — planning, building, testing, reviewing, and coordinating and each part is deducted from your monthly balance. All of these activities together form the billable tasks that make up your monthly hours. This structure makes the entire software development as a service model easier to follow because every type of work is accounted for within the same framework.
These tasks typically include:
Planning and architecture
Programming, testing, and debugging
Project management and coordination
Design tasks (if part of your package or added separately)
Meetings, workshops, and communication
Documentation and quality reviews
In simple terms, if the task requires hands-on effort from the team, it is treated as time deducted from your monthly hour balance.
Examples of billable hours include:
Writing or refining a feature's code,
A workshop session to align on requirements,
Reviewing pull requests,
Preparing technical documentation,
Fixing bugs identified during testing,
Creating UI/UX improvements based on feedback,
Setting up integrations with third-party services,
Configuring deployments as part of ongoing development.
How Your Hour Usage Is Tracked
Smicolon keeps track of your hour usage throughout the month, so you always know how much of your balance has been used. It shows you how your hours are distributed across different tasks, similar to how a billable hours tracker would display activity in real time. MinuteDock also explains this idea, showing how structured time tracking helps teams keep track of every hour, just like we monitor your usage across tasks each month. This makes it easy to stay aware of your usage.
As your usage gets close to 70–90%, you’ll receive a reminder that you’re nearing the end of your monthly hours. This doesn’t slow your work or change anything — it just keeps you updated so you’re not surprised later. Even if you miss the reminder, your work continues normally. The tracking system provides clarity and helps you plan ahead, making the SDaaS process more transparent and easier to manage.
To make this tracking more transparent, Smicolon uses a dedicated Hour Bank Calculator dashboard. The dashboard gives a real-time view of total prepaid hours, monthly usage, remaining balance, and recent activity—so you can clearly see how your billable hours are being used throughout the month.
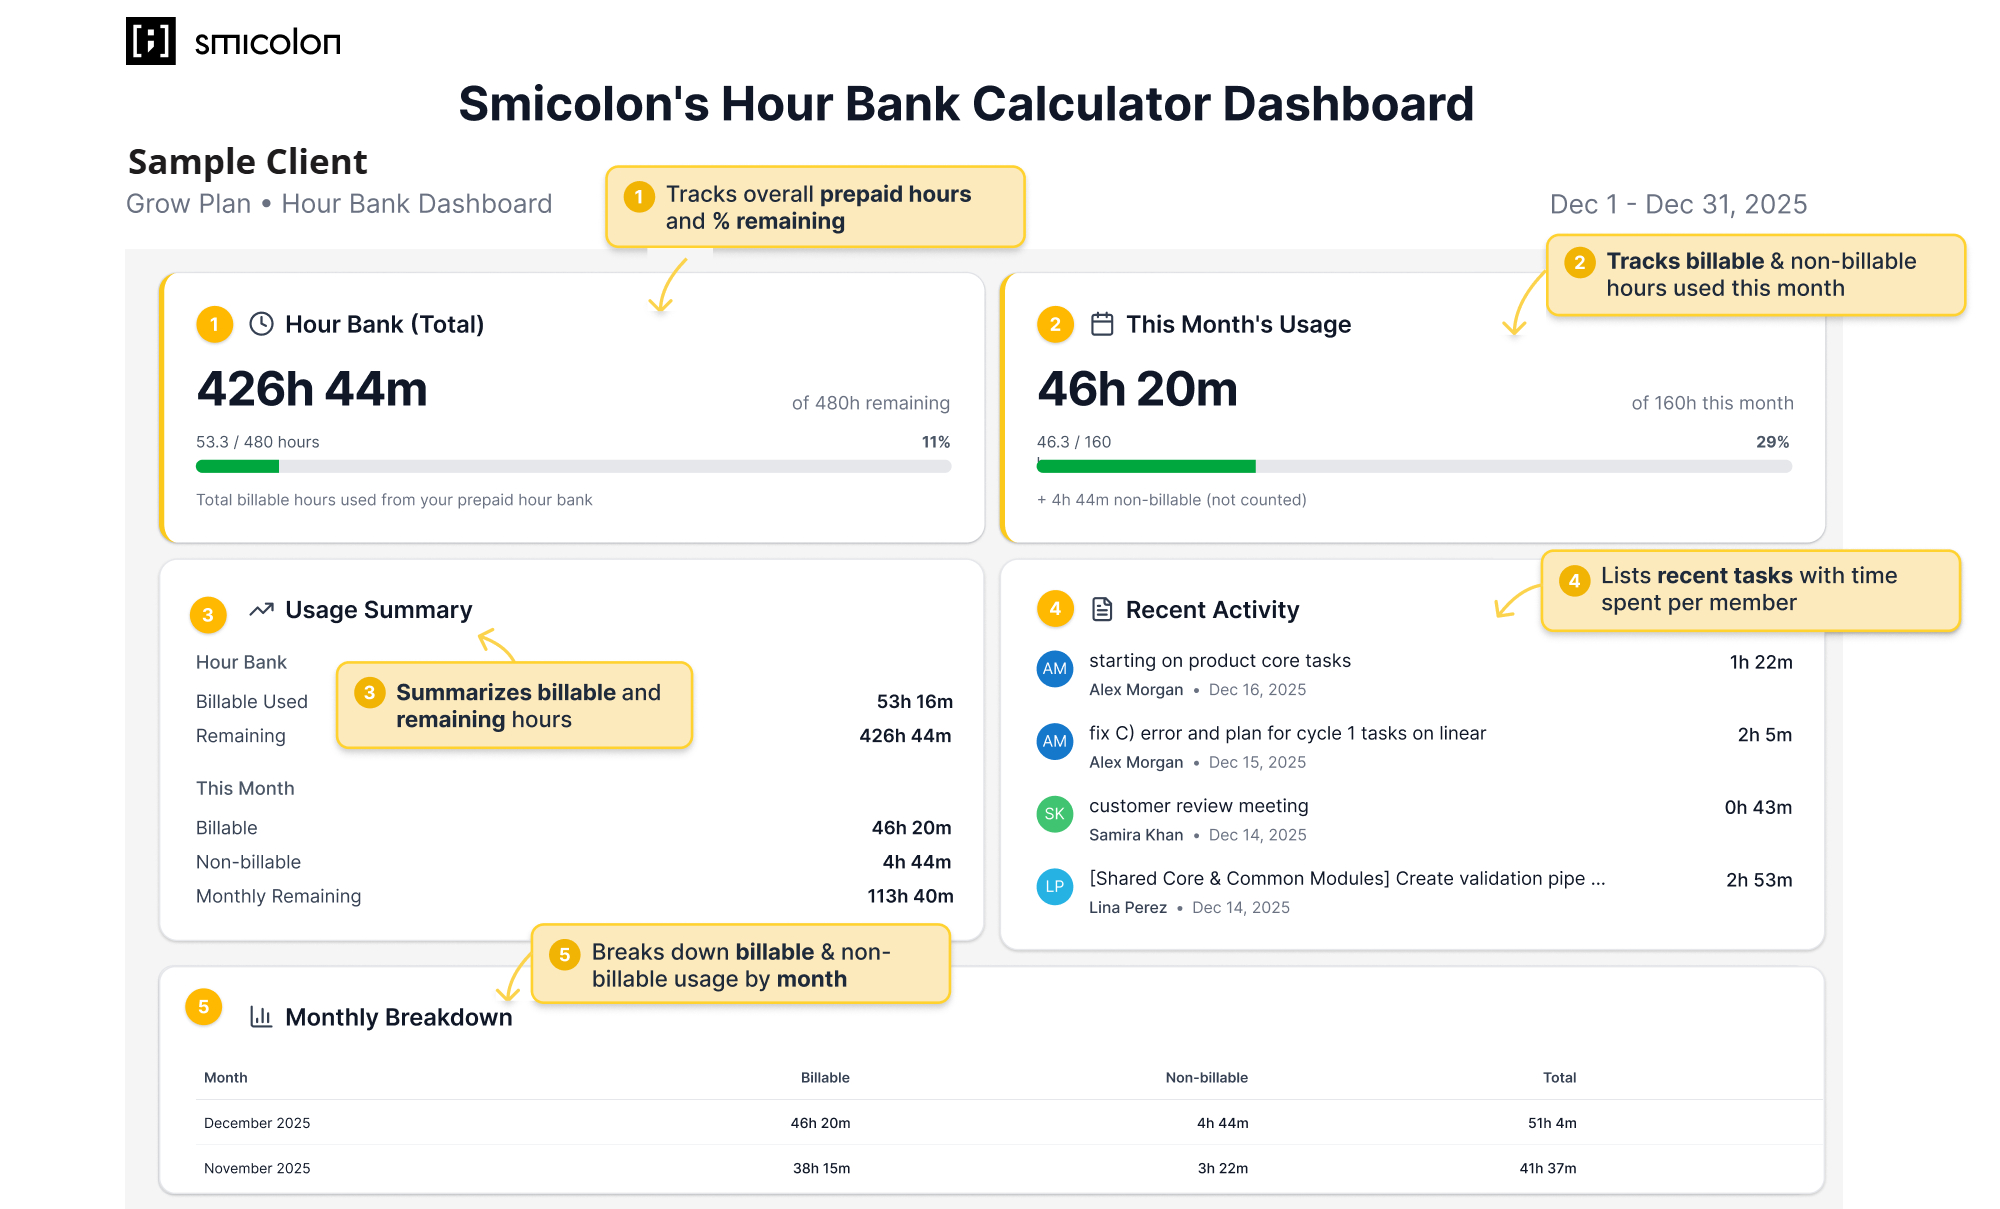
The dashboard highlights how hours are distributed across monthly usage, billable and non-billable work, recent activity, and historical breakdowns—giving full visibility into where time is spent and how much capacity remains.
How Unused Hours Work
When your Minimum Commitment Period ends, any unused hours in your Hour Bank expire. These hours are non-refundable because Smicolon keeps a dedicated team and resources available for your project throughout the entire period.
Since that time is reserved for you, unused hours can’t automatically be moved or carried over. If you want to transfer hours to another project, it can only happen with Smicolon’s written approval. This keeps scheduling clear and reliable, based on how your monthly usage has changed over the commitment period.
This end-of-period rule is separate from what happens when you run out of hours during the month, which works a little differently.
When Your Monthly Hours Finish Before the Month Ends
Some months simply move faster than others, and it’s completely normal to reach your monthly hours before the month is actually over. If you’re on the Grow plan, for example, you may use up your 160 hours even though there are still days left in the month. When this happens, you’ve essentially reached the limit of your billable hours for that cycle, but the work doesn’t have to stop.
You simply choose how you want to move forward. There are three ways to continue, and each option keeps you in control of your pace, priorities, and budget.
1. Pause Until Next Month
If things aren’t urgent, you can pause development and restart when the new month begins and your standard hours refresh. It’s the simplest option: no extra charges, no added complexity — just a clean reset when the next cycle starts.
2. Continue Using Your Prepaid Hours
Most clients prefer to keep moving, especially when their project is moving smoothly. This is Smicolon's default approach, where the team continues working without interruption. When you need additional work, the extra hours are simply pulled early from your prepaid hour bank at the same discounted rate.
Nothing changes in your workflow:
You hit your monthly limit,
The team keeps working,
Extra hours come from your hour bank,
Those hours appear on next month's invoice.
This option keeps everything running naturally without needing new approvals or changes to your plan.
3. Continue Using at a Premium Rate
If you want to save your hour-bank balance for future phases or only need a small push to finish something important, you can continue development at the premium hourly rate (€75–€100/hr). These hours are billed in the current month and give you flexibility without touching your prepaid pool. To make this easier to understand in a real project, let's look at a simple example.
Practical Overview of Your Options
Imagine you're on the Scale plan, which gives you 240 hours per month. This month, your project picks up speed, and all 240 hours are used by Day 20. Here’s how that scenario plays out — and the choices you have.
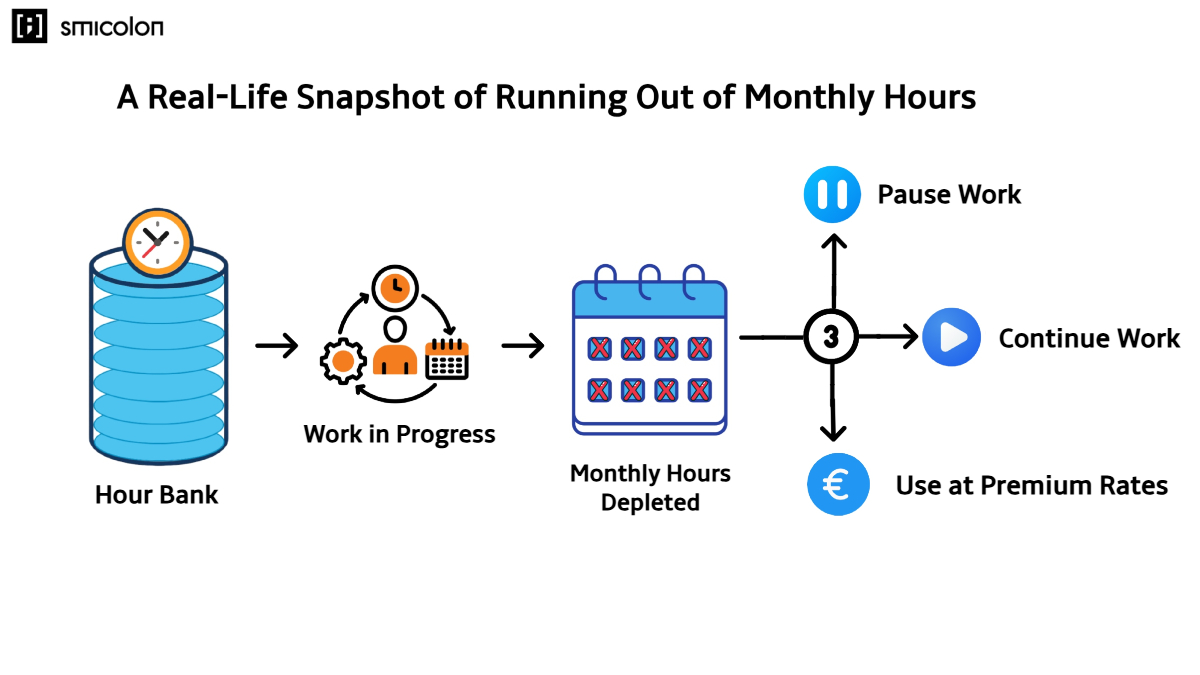 You've used all your monthly hours early. These are your options:
1. Pause Work
Work stops on Day 20 with no extra costs, and it resumes on the 1st of the next month when your 240 hours refresh.
2. Continue at the Discounted Rate
The team keeps working on Day 21. For example, if they use an extra 15 hours, those hours are simply taken early from your prepaid hour bank and will appear on next month’s invoice at your discounted rate. Your project continues without any slowdown.
3. Continue at the Premium Rate
The team also continues on Day 21, and the same 15 hours are completed, but they're billed at the premium rate and appear on this month's invoice. This option helps you save your hour-bank balance for later phases.
These choices let you decide whether to pause, continue at your discounted rate, or work at a premium rate — all while keeping your project entirely under your control. Together, they show how flexible the hour bank model is and how naturally it fits into the SDaaS process.
Now that you know how your options work, let’s look at why Smicolon uses this model in SDaaS and how it strengthens your overall development process.
The Power of Pairing SDaaS with an Hour Bank System
One of the biggest reasons Smicolon uses an hour-bank model in SDaaS is to make the entire development process more predictable and entirely in your control. If you want to learn more about how we deliver SDaaS as a service, you can visit our SDaaS service page. Within this model, your project begins with a clear structure and predictable workflow — creating a smoother, more transparent experience from the start.
By giving you a fixed pool of prepaid hours each month, the SDaaS model ensures that your project runs within a clear and agreed-upon structure. This gives you a stable framework where both your cost and your team’s capacity are already defined, allowing you to plan confidently and manage progress without uncertainty.
Because the hours are allocated upfront, the team can begin tasks immediately without waiting for new approvals or quotes. Unlike many offshore software development models, this structure eliminates delays and gives you full visibility from the beginning. Work moves forward as soon as priorities are defined, which keeps momentum steady and prevents unnecessary delays. You always know how much capacity is available, what the team is focusing on, and where your monthly balance is being used.
This model also gives you room to adjust as needed. Projects change, and priorities can shift quickly. With an hour bank inside a software development as a service model, adjusting the plan simply means deciding what matters most right now. You redirect your monthly usage toward the highest-value tasks without needing new approvals or updated estimates — keeping the entire workflow responsive and easy to manage.
Transparency is built into the structure. Your hour usage is tracked throughout the month, and you get a heads-up as you start getting close to the end of your monthly hours. This helps you stay aware of your monthly usage before decisions need to be made, allowing you to plan confidently without unexpected costs.
By combining SDaaS with a clear hour-bank system, Smicolon delivers a development process that’s easier to understand, easier to manage, and far more predictable. You get clarity, flexibility, and control — all within a framework designed to keep progress steady and aligned with your goals. In short, the hour bank turns SDaaS into a transparent and predictable structure, giving you clear visibility into progress, remaining hours, and what comes next.
Conclusion
The hour-bank model is central to how SDaaS works at Smicolon. By combining predictable monthly hours, transparent tracking, and a reserved development team, it creates a development process that is easier to manage, easier to plan, and easier to trust. You gain the clarity, flexibility, and control needed to move your project forward with confidence—making the SDaaS approach a more structured and client-friendly alternative to traditional offshore software development models.
Not sure which option suits you best? 🤔
Talk to us anytime — we’ll point you in the right direction.
---
# What is the difference between UI and UX design?
Source: https://smicolon.com/blog/what-is-the-difference-between-ui-and-ux-design
Updated: 2026-07-31T12:15:41.157Z
Learn about the difference between user interfaces (UI) and user experiences (UX) design, and how they contribute to user satisfaction.
In today's fast-paced world, where people have shorter attention spans, designing user interfaces (UI) and user experiences (UX) has become crucial for making a lasting impact on customers.
Did you know that 94% of first impressions of a brand’s website are influenced by its design? Having a polished and professional design can instantly make a positive impact on users and set the tone for a satisfying user experience. Recent findings from Forrester Research reveal that a well-planned and smooth user experience (UX) design could boost customer conversion rates by up to 400%. Additionally, 52% of users say they won't return to a website if it doesn't look good.
As a result, company stakeholders now recognise the importance of UX and UI in driving the financial success of their online services and products. It's no longer just a competitive advantage but a significant contributor to a company's bottom line.
As such, UI and UX design are essential disciplines in product design that work together to create a smooth and easy experience for users. Although UI and UX are sometimes used interchangeably, they actually refer to different parts of the design process.
In this article, we will discuss the main differences between UI and UX design, their significance in creating a memorable customer experience, and how they contribute to user satisfaction.
What is UI Design?
UI design refers to everything a user interacts with to use a digital product or service. It encompasses screens, pages, visual elements like buttons and icons, keyboards, sounds, and even lights. The UI designer's primary focus is on the look and functionality of a product's visual design.
During the early days of computers, users had to rely on the command line interface, which required coding skills to perform even simple tasks. However, the development of graphical user interfaces (GUI) revolutionised the way people interacted with computers.
GUI allowed users to visually submit commands through icons, buttons, menus, and checkboxes, making computers more accessible to a wider audience.
Today, UI designers work not only on computer interfaces but also on mobile phones, augmented and virtual reality, and even "invisible" or screenless interfaces like voice and gesture recognition.
Their goal is to create visually appealing and intuitive designs that enhance the user's interaction with the product.
What is UX Design?
UX design focuses on the overall experience of users when interacting with a product or service. It encompasses every aspect of a user's interaction with a company's products, services, and brand. UX designers work to understand user needs, emotions, and behaviours to create meaningful and enjoyable experiences.
The term "user experience" was coined by cognitive scientist Don Norman, who defined it as the encompassing of all aspects of the end-user's interaction with a company. UX designers go beyond the visual design of a product and dive deep into understanding user motivations and goals.
To create a positive user experience, UX designers conduct extensive research, analyse user behaviour, and iterate designs based on user feedback. They collaborate closely with UI designers, developers, marketers, and product teams to ensure that user needs are met throughout the design process.

UI vs UX Design: Unravelling the Distinctions
While UI and UX design are closely related, they have distinct focuses and responsibilities. When conducting a UI and UX comparison, it is crucial to understand the distinctive roles they play in product design. UI design concentrates on the product's visual elements and how users interact with them, while UX design encompasses the entire user journey and aims to create a delightful and seamless experience.
Solutions vs. Aesthetics
UI designers primarily focus on finding solutions to design problems that align with user needs. They pay close attention to the visual aesthetics of the product, ensuring that it is visually appealing and functional.
On the other hand, UX designers take a broader approach, considering how the product's visuals impact the overall user experience. They aim to create designs that evoke specific emotions and behaviours in users.
Individual Parts vs. User Flow
UI designers focus on designing individual parts of a digital product, such as specific pages or screens. They ensure that each element is visually coherent and contributes to the overall user interface. In contrast, UX designers pay attention to the user's journey through the entire product. They identify potential bottlenecks, areas of confusion, or opportunities for improvement in the user flow.
Importance of UI and UX Design
UI and UX design plays a crucial role in the success of a product or service. Good UI and UX makes it easy for the user to complete their tasks and achieve their goals. When a product is easy to use, users are likely to continue using it and recommend it to others.
A well-designed UI and UX considers the needs and abilities of users with disabilities. By designing for accessibility, companies can create products that are usable by a wider audience.
A good UI and UX can help keep users engaged with a product, leading to increased retention and loyalty. An enjoyable and intuitive experience can encourage users to keep using a product and come back to it in the future.
The UI and UX of a product can have a significant impact on the overall brand perception of a company. A consistent and attractive UI and UX can help build brand recognition and credibility.
Wondering why is UX important for business? Because it directly affects how users interact with a product or service. By designing a user-friendly and enjoyable experience, companies can create products that are more likely to be used and recommended to others.
The Benefits of UI and UX Design for Businesses
UI and UX design plays a crucial role in enhancing the user experience and driving business growth. Here are some of the benefits of UI and UX design for businesses:
Improved Customer Satisfaction
A well-designed UI and UX can lead to improved customer satisfaction. By creating a product that is easy to use and visually appealing, businesses can provide a positive experience for their customers, leading to increased loyalty and repeat business.
Increased Conversion Rates
UI and UX design can also help businesses increase their conversion rates. By making it easier for customers to navigate through the product and complete their desired actions, such as making a purchase, businesses can improve their conversion rates and revenue. One of the ways to assess the improvements in user experience is to calculate the ROI of UX design.
Competitive Advantage
UI and UX design can also provide businesses with a competitive advantage. By creating a product that is visually appealing and easy to use, businesses can differentiate themselves from their competitors and attract more customers.
Better Decision Making
By understanding user behaviour and preferences, businesses can make more informed decisions about product development and marketing strategies. UI and UX design provides valuable insights into how users interact with the product, helping businesses to make data-driven decisions.
Choosing UI? UX? Or Both?
The significance of both UI and UX design cannot be emphasised enough. There is a prevailing misconception that focusing on either one of these aspects would be sufficient.
However, in reality, these elements complement each other and play distinct roles in shaping user interactions. While UI concentrates on visual appeal and aesthetics, UX delves deeper to create intuitive and smooth user experiences. It is a common mistake to prioritise one over the other, as both UI and UX are equally vital for achieving the success you want for your brand.
To truly make a mark and leave a lasting impression on your users, it is imperative to acknowledge the value of both UI and UX and invest in a harmonious integration of captivating design and exceptional usability.
Finding the right balance between eye-catching visuals and seamless functionality is the key to engaging users and making a lasting impact on their overall experience. By embracing the synergy between UI and UX, your business can elevate its online presence and set itself apart from the competition.
Creating Lasting and Impactful Experiences
UI and UX design are not just additional features but essential components of the overall product design. They work hand in hand, collaborating closely to ensure the success of a product.
UI designers focus on crafting visually appealing and interactive elements that catch the user's eye and create an emotional connection. On the other hand, UX designers prioritise creating a seamless and meaningful user experience by understanding user behaviour and needs, streamlining navigation, and ensuring intuitive interactions.
At Smicolon GmbH, we specialise in creating impactful experiences. With our team of global talents, we tailor a process to develop and refine the customer experience through your products.
Don't miss the chance to transform your company's user experience. Contact us today to embark on this transformative journey and elevate your brand's digital presence to new heights. Our team is ready to help you create a user-centric product that users will love and remember.
---
# How much does it cost to build a simple website?
Source: https://smicolon.com/blog/cost-to-build-simple-website
Updated: 2026-07-31T12:15:40.303Z
In today's digital age, the importance of a well-designed and functional website cannot be overstated. It's the virtual shop front that can make or break a business's online presence. But have you ever wondered about the cost of building a website? Or perhaps you're unsure where even to begin, feeling like you're in a "chicken and egg" situation?
And did you know that 94% of first impressions are related to a website's design? This means that users form an opinion about a website within a few seconds of visiting it, emphasising the need for an attractive and well-designed interface. After all, as the old saying goes, “Don't judge a book by its cover”, but in the online world, your website's cover matters a great deal.
In this comprehensive guide, we'll delve into these questions and more, exploring the various factors that influence website costs, the different approaches to building a website, and the associated expenses. By the end of this article, you'll have a good understanding of what it takes to budget for a website and the crucial next steps to consider, ensuring you're not "flying blind" in the digital landscape.
5 Factors Affecting the Cost of Building a Website ##
The cost of building a website can be a real "wild card" in the world of business expenses, and it can vary widely depending on several factors. While every business has unique website needs, there are some key factors that generally "tip the scales" when it comes to cost.
Understanding these factors will help you "get a handle on" the expenses involved in building a website. So, without further ado, let's delve into the five major factors:
1. Domain Name The domain name is the web address that users type into their browsers to access your website. Buying a domain name is usually an annual expense, ranging from $10 to $20. However, several factors can affect the cost:
Domain Registrar: There are many registrars where you can purchase and register your domain name. Each registrar offers different packages and features at varying price points.
Top-Level Domain (TLD): The TLD is the extension at the end of the domain name, such as ".com," ".org," or ".net." Established TLDs tend to cost more than less common ones.
Length of Commitment: Most registrars offer different prices based on the length of the contract. Opting for a longer commitment can be cost-effective in the long term.
Domain Privacy: Registrars offer privacy features for an additional fee, allowing you to protect your personal information and maintain anonymity.
2. Website Functionality The functionality of a website refers to the features and capabilities it offers to users. The more functions you add to your site, the higher the cost. Here are some examples of common website functions and their associated costs:
E-commerce Functions: If you plan to run an online store, your website needs various design features for customers to find and purchase products. Design costs for a fully custom e-commerce site can exceed $2,000.
Membership Portals: These gated areas on a website allow registered members to access exclusive content. Implementing membership portals can cost anywhere from $89 to $399 per year, depending on the features and licence type.
Subscription Services: Setting up subscription models for recurring product deliveries requires specific functions, which can be integrated through apps like Bold Subscriptions starting at $49.99 per month.
Custom Programming: Complex websites, such as web portals that handle large amounts of data, may require custom programming. Hiring a web developer for custom coding can be done through platforms like Upwork.com or freelancer.com
3. Website Maintenance Website maintenance is crucial for keeping your site functional and secure. However, many businesses overlook the costs associated with ongoing maintenance. Some common website maintenance tasks include fixing broken links, patching software issues, testing forms and e-commerce functions, fixing security vulnerabilities, and regularly backing up the site. The cost of website maintenance varies based on the size and complexity of the website. It is typically handled by specialised agencies or web developers.
4. Size of the Site The size of a website, measured by the number of pages and the complexity of its architecture, can significantly impact the cost. Building a large website with many pages and intricate design elements requires more time and effort, resulting in higher costs. On the other hand, a simple website with a standard template and few pages can be built at a fraction of the cost. Here's a rough estimate of design costs based on website type:
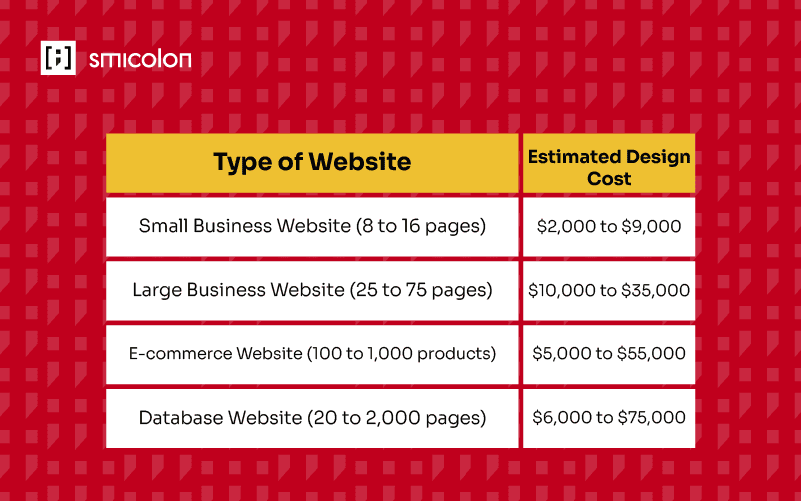
5. Website Hosting Platform The choice of a website hosting platform, also known as a content management system (CMS), affects both the cost and functionality of a website. Different CMS platforms offer varying features, ease of use, and cost structures.
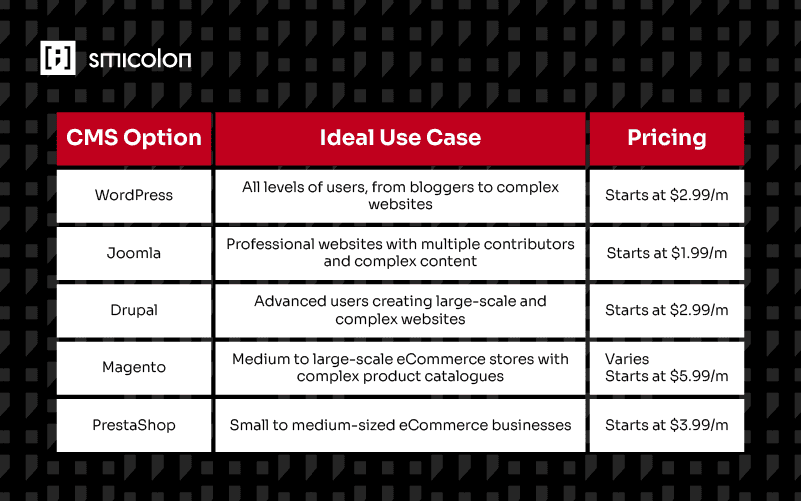
1. WordPress Over 43.2% of all websites use WordPress, making it the most popular CMS platform. WordPress is an open-source software that is well-known for its scalability and flexibility. Furthermore, its gallery of over 58,000 WordPress plugins enables users to create any type of website.
Pros:
Offers cost flexibility tailored to individual needs and budgets. Provides extensive customisation through a wide array of free WordPress themes and high-quality plugins.
If you choose a theme that utilizes a page builder to create your website, no coding skills are needed. However, it's a good idea to consider enlisting the assistance of a WordPress expert to ensure the theme aligns perfectly with your specific requirements.
Cons:
Some WordPress plugins and themes lack reliability or quality. Themes, particularly those using a page builder, can be heavy and may slow down your website's load speed, which can negatively affect SEO.
The platform relies primarily on community support, forums, tutorials, and documentation.
Best for:
Suitable for users at all levels, from those starting simple blogs to those developing complex websites.
Pricing:
Free WordPress software, but users require web hosting and a domain name.
Hosting providers like GoDaddy offer combined plans.
Key Features:
User management for assigning roles and access to various user types.
Media management, including editing names, setting alt tags, and adding captions, improves how search engines read and rank your website images.
Built-in comments for visitor engagement.
2. Joomla Joomla is an open-source CMS that powers over 2% of all websites. It distinguishes itself by offering robust features out-of-the-box, including multilingual support. However, the initial setup may pose challenges for non-technical users.
Pros:
Efficiently manages sites with numerous sub-pages. Implements 2-factor authentication for enhanced security.
Cons:
Control panel features terminology that may be less beginner-friendly.
Compatibility issues may arise between different modules, extensions, and plugins.
Best for:
Ideal for professional websites managed by multiple contributors.
Pricing:
Just like WordPress, you’ll need a web hosting and a domain name.
Key Features:
Banner management tool for advertising campaigns. Multilingual settings with support for over 70 languages.
Built-in search and smart search features for enhanced user navigation.
3. Drupal Designed for professional web developers, its flexible API architecture supports different digital platforms.
Compared to Joomla and WordPress, Drupal optimises its built-in features for better performance and security. It’s also worth noting that Drupal’s websites get higher web traffic than other CMS software.
Pros:
Regular security tests reduce vulnerability to threats. A range of built-in modules expands site functionality.
Cons:
Proficiency in coding languages like PHP, CSS, and HTML is required.
Management tasks, such as version upgrades, can be time-intensive.
Best for:
Suitable for advanced users with strong technical knowledge, especially for large-scale and complex websites.
Pricing:
Drupal pricing depends on web hosting and domain name choices.
Key Features:
Multilingual support with automated language translation.
Personalisation capabilities using geolocation and user behaviour data.
Marketing automation for increasing outreach.
4. Magento Magento is one of the best eCommerce platforms out there. The CMS software focuses on security, SEO, and customisation to optimise all types of eCommerce sites.
As it caters to bigger online stores, the platform is powerful enough to feature a high number of products and orders.
Pros:
Manages multiple stores across various locations, languages, and currencies.
Responsive content management for mobile devices.
Cons:
Initial setup can be intricate.
Customising design and listing products may consume time.
Best for:
Ideal for medium to large-scale eCommerce stores.
Pricing:
Magento's cost varies; the Open Source version is free, but additional costs arise from hosting and a custom domain.
Premium editions like Magento Commerce and Magento Commerce Cloud require contacting sales for pricing.
Key Features:
Secure checkout with Worldpay and Cybersource payment gateways.
Touch-friendly admin dashboard for user-friendly edits. Catalogue management with inventory control and dynamic pricing.
5. PrestaShop PrestaShop is another popular CMS platform for small to medium-sized eCommerce businesses. Its active community and broad set of features make it a highly flexible online store management platform. Its comprehensive interface also helps to enter and monitor products easily.
Pros:
Provides user-friendly eCommerce features suitable for all skill levels.
Offers a diverse selection of themes and modules for customisation.
Cons:
May lack scalability for larger eCommerce stores.
Relies on extensions and plugins, which can incur additional costs.
Best for:
An excellent choice for small to medium-sized eCommerce businesses.
Pricing:
PrestaShop software is free, but hosting and a domain name are required.
Hostinger offers hosting plans starting at $3.99/month for Business.
Key Features:
SEO management for optimising content.
Multiple payment options, including PayPal, Skrill, Stripe, WorldPay, and offline processing.
Multiple store management to streamline common features across stores.
Choosing the right CMS depends on your business needs, technical expertise, and budget. Each platform offers different pricing structures and customisation options. In fact, these CMS options cater to a variety of website needs, ensuring there's a suitable choice for every project. Keep in mind that the mentioned pricing is based on hosting plans and may vary depending on your specific hosting provider and package selection.
Types of Websites and Their Average Costs ##
The type of website you want to build will also play a significant role in the cost equation. As the saying goes, "Different strokes for different folks," various types of websites come with distinct requirements, functionalities, and complexities, all of which can significantly impact the overall development cost. Let's delve into some common types of websites and get a sense of their average costs:
Basic informational website: A basic informational website typically includes a few pages with information about the company, services, contact details, and maybe a blog section. This type of website is relatively simple and doesn't require advanced functionalities. The average cost for building a basic informational website can range from $500 to $2,000.
E-commerce website: An e-commerce website allows businesses to sell products or services online. It requires features like shopping carts, payment gateways, inventory management, and security measures. The cost of building an e-commerce website can vary depending on the number of products, the complexity of the functionalities, and the platform used. On average, an e-commerce website can cost anywhere from $2,000 to $10,000 or more.
Custom web applications: Custom web applications are more complex and require extensive development work. They can include features like user registration, user-generated content, integration with third-party services, and more. The cost of building custom web applications can range from $10,000 to $100,000 or even more, depending on the complexity and scope of the project.
3 Different Ways to Build a Website and Associated Costs ##
Once you understand the factors influencing website costs, you can explore different approaches to building a website. The method you choose will depend on your budget, technical skills, and desired level of customisation. Here are three common ways to build a website and their associated costs:
1. Do It Yourself (DIY) ###
The DIY approach is the most cost-effective option for building a website. By taking on the design yourself, you can save money on hiring professionals. The basic expenses involved in a DIY website include a domain name, hosting costs, an SSL certificate, a premium theme, and a drag-and-drop website builder like Squarespace, Weebly, or Wix. If you prefer a more traditional CMS, WordPress is a popular choice.
While the DIY approach can be suitable for simple websites, it may not be viable for complex projects. Designing a complex website without prior experience can be challenging and may result in a lower quality website. Consider the following pros and cons of the DIY approach:
Pros
Cost-effective option
Opportunity to learn website development
Ability to test different ideas and concepts
Cons
Steep learning curve for beginners
Time-consuming process
Potential lower quality website
The estimated cost for a small business brochure-style website built by yourself is around $200, considering expenses such as domain name registration, hosting, premium themes, plugins, and a website builder.
2. Hire an Independent Professional ###
If you want a professional-looking website without investing time and effort in learning web design, hiring an independent web developer or designer is a good option. Freelancers on platforms like Upwork or Freelancer.com can bring your ideas to life and ensure the success of your online venture.
When working with an independent professional, costs will depend on factors such as hourly rates, website functions, custom programming requirements, and the number of pages. Freelancers typically charge between $20 and $80 per hour. For a small business website, the estimated cost can range from $1,500 to $5,000.
Consider the following pros and cons of hiring an independent professional:
Pros
Guaranteed professional-looking website
No need to learn web design
Assistance with website launch
Cons
Higher financial investment, especially for complex projects
Potential difficulty finding a new freelancer for future changes
Communication challenges for non-technical individuals
3. Use a Software Development Company ###
Software development companies are ideal for businesses that require complex projects and a comprehensive range of services. In addition to web development, software development companies often provide maintenance, SEO services, and marketing strategy development. However, agencies typically have a higher price point and longer project timelines, making them less accessible for small businesses.
The cost of hiring a company can range from thousands to tens of thousands of dollars, depending on the agency size and project complexity.
Consider the following pros and cons of using a software development companies:
Pros
Resourceful for complex projects
All-in-one package for web design, maintenance, and marketing
Assistance with defining marketing strategy
Cons
Cost may be prohibitive for small businesses
Longer project timelines
Less personalised attention for small projects
Benefits of Hiring a Software Development Company ##
Now that we have a clear understanding of how much it costs to build a website, let's explore the numerous benefits of hiring a software development company to build one.
Customised website development ###
One of the significant advantages of hiring a software development company is the ability to have a customised website tailored to your specific business needs. When you choose to build a website on your own, you are often limited to pre-designed templates and themes that may not fully align with your brand identity or functionality requirements. A software development company, on the other hand, can create a website from scratch, taking into account your unique business goals and target audience.
With a customised website, you have complete control over the design, layout, and features. You can work closely with the development team to ensure that your website reflects your brand's values and effectively communicates your message to your audience. Whether you need an e-commerce website, a content management system, or a booking platform, a software development company can build a solution that meets your exact specifications.
Expertise in web design and development ###
Building a website involves much more than just writing code. It requires a deep understanding of user experience (UX) design principles, visual aesthetics, and front-end and back-end development. A software development company has a team of experts who specialise in these areas, ensuring that your website is not only visually appealing but also functional and user-friendly.
The web designers at a software development company are skilled in creating intuitive user interfaces that make it easy for visitors to navigate your website and find the information they need. They consider factors such as information hierarchy, colour schemes, typography, and visual elements to create a cohesive and engaging design. The developers, on the other hand, are responsible for bringing the design to life by writing clean and efficient code. They ensure that your website is responsive, accessible, and performs well across different devices and browsers.
By hiring a software development company, you can leverage their expertise in web design and development to create a website that stands out from the competition and provides an exceptional user experience.
Time and cost efficiency ###
Building a website from scratch can be a time-consuming and complex process, especially if you don't have the necessary technical skills. It involves planning, designing, coding, testing, and deploying, all of which require careful attention to detail. By hiring a software development company, you can save valuable time and focus on other aspects of your business.
A professional development team has the experience and knowledge to efficiently handle the entire website development process. They follow industry best practices and use modern development frameworks and tools to streamline the development process. This ensures that your website is delivered on time, without compromising on quality.
In addition to time efficiency, hiring a software development company can also save you money in the long run. While there may be an upfront cost associated with hiring professionals, the return on investment can be significant. A well-designed and optimised website can attract more customers and generate more revenue for your business. It also reduces the risk of costly errors and technical issues that can arise from attempting to build a website yourself.
Technical support and maintenance ###
Building a website is just the first step. Once your website is live, it requires ongoing support and maintenance to ensure that it continues to function smoothly. A software development company provides technical support and maintenance services, allowing you to focus on running your business while they take care of the technical aspects.
Whether you need to update content, add new features, or fix any issues that may arise, a software development company is there to assist you. They have a dedicated support team that can quickly address any concerns and provide timely solutions. This ensures that your website remains up-to-date, secure, and optimised for performance.
By outsourcing the technical support and maintenance of your website to professionals, you can save yourself the hassle of dealing with complex technical issues and focus on what you do best – growing your business.
Integration of third-party tools and services ###
In today's interconnected digital landscape, integrating third-party tools and services into your website is often necessary to enhance its functionality and provide a better user experience. Whether it's integrating payment gateways, social media platforms, analytics tools, or marketing automation software, a software development company can seamlessly integrate these tools into your website.
A software development company has experience working with various APIs (Application Programming Interfaces) and can ensure a smooth integration process. They understand the complexities involved in integrating different systems and can provide the necessary expertise to ensure that everything works seamlessly together.
By integrating third-party tools and services into your website, you can unlock a wide range of functionalities that can help streamline your business processes, improve customer experience, and drive growth.
Next Steps ##
Determining the exact cost of building a website can be challenging due to the unique nature of each business. Building a website is an investment that can pay off in the long run. By understanding the factors that impact website costs and exploring the different options available, you can make informed decisions and create a website that meets your business goals.
However, finding top talent for your website development needs is easier than ever. Platforms like Upwork or Freelancer.com connect businesses with skilled professionals who can guide you through the website creation process.
Whether you choose to build the website yourself, hire an independent professional, or work with a software development company, Smicolon provides a wide range of options to suit your budget and project requirements. Embarking on the journey of creating a website can undoubtedly pose challenges, yet it need not be an arduous endeavour when you partner with Smicolon.
Here, we advocate against settling for the mundane. Instead, we champion the creation of a website that is as exceptional and distinct as your brand itself, providing you with a custom-designed digital presence that can stand head and shoulders above the competition.
Contact us today to kickstart the journey towards your very own custom-designed website.
Disclaimer: The information provided in this article is for informational purposes only. The actual cost of building a website may vary depending on various factors, and it is recommended to consult with professionals and conduct thorough research before making any decisions.
---
# Logo Design Award Goes to Smicolon GmbH
Source: https://smicolon.com/blog/best-logo-award
Updated: 2026-07-31T12:15:39.520Z
Announcement
The Smicolon team is thrilled to announce that our company logo has earned a coveted spot among the Best Company App Logos, as nominated by Design Awards at DesignRush.
Celebrating the Fruits of Dedication
The creation of our logo was a labor of love, with meticulous attention to detail and creative flair. To commemorate this achievement, we've produced a captivating logo reveal video, which you can view here:
The wordplay embedded in "SMICOLON," derived from the word "Semicolon," showcases our commitment to standing out, fostering creativity, and going the extra mile for our clients. Our logo is not just an emblem; it's a reflection of the core values that underpin our company's foundation. We take pride in our willingness to be bold and innovative, qualities embodied by our logo itself.
---
# What Is SDaaS? The Smart Way to Deliver Custom Software Development Services
Source: https://smicolon.com/blog/software-development-as-a-service-sdaas-guide
Updated: 2026-08-17T12:55:44.272Z
A practical guide to Software Development as a Service: how the model works, where it fits, what a subscription should define, and what to ask before signing.
Software Development as a Service (SDaaS) is an ongoing way to buy product engineering capacity. Instead of recruiting every role yourself or defining one fixed project for an agency, you work with a managed team through a recurring agreement. The team can cover product, design, engineering, quality, and delivery while priorities change over time.
The name is not an industry standard with one universal contract. Providers use it differently. The useful question is therefore not whether a proposal carries the SDaaS label, but what team, capacity, ownership, quality controls, and exit terms are actually included.
How SDaaS differs from other delivery models
Delivery model | How work is bought | Best fit | Main trade-off
In-house hiring | Permanent roles employed by your company | Stable, long-term capability you want to own internally | Recruiting and onboarding take time; the company carries utilization and management overhead
Fixed-scope project | A defined output for an agreed scope, price, and timeline | Work that can be specified before delivery starts | Changes usually require a new estimate or change request
Staff augmentation | Individual specialists added to your existing team | A team that already has strong product and engineering leadership | You remain responsible for coordination, delivery process, and technical quality
SDaaS | Managed, recurring product-engineering capacity | Products whose priorities will evolve and need several disciplines | The agreement must make capacity, ownership, and cancellation terms explicit
SDaaS should not be presented as automatically faster, cheaper, or better than every alternative. Its advantage is operational: a company can start with an established delivery unit and adjust the work queue without reopening a fixed project contract for every change.
What a useful SDaaS agreement defines
A credible subscription should make the following points easy to inspect:
Included capacity: which roles are available, how much work can be active, and what happens when demand exceeds that capacity.
How priorities move: who owns the backlog, how urgent work is handled, and how unfinished work carries into the next cycle.
Quality controls: code review, automated tests, security checks, accessibility, release review, and production monitoring appropriate to the product.
Ownership and access: the customer should control the source repository, cloud accounts, product data, and delivery documentation.
Communication: regular planning, written progress, visible risks, and a named delivery owner.
Exit terms: notice period, final handover, access transfer, and what support is available after the subscription ends.
If these details are absent, a monthly invoice alone does not make the service predictable.
How the model works in practice
1. Establish the current state
The first step is to review the product, codebase, users, constraints, and delivery risks. For an existing application, this includes the repository, deployment path, environments, monitoring, and open defects. For a new product, it includes the problem, intended users, and the smallest outcome worth releasing.
2. Set one accountable work queue
Product work, defects, infrastructure, and design decisions need one ordered backlog. The customer owns business priority; the delivery team makes dependencies and technical risk visible. This prevents a subscription from becoming a collection of disconnected requests.
3. Deliver in reviewable increments
Work should move through small, testable changes with a clear definition of done. A completed item includes the code or design, review evidence, and the deployment or handoff needed for somebody to use it. Progress is measured by working product changes, not activity reports.
4. Operate what reaches production
Production readiness includes deployment, rollback, observability, security, and ownership. The exact controls depend on the risk of the product, but they should be decided before release rather than after an incident.
5. Revisit capacity and priorities
The recurring model is useful when priorities change. The team and customer review throughput, blocked work, upcoming decisions, and whether the current capacity still fits. Scaling should be an explicit agreement, not an assumption that unlimited parallel work is possible.
When SDaaS is a good fit
The model can work well when:
you have a product direction but do not yet need every discipline as a permanent hire;
an MVP or AI-generated prototype needs to become a maintained production system;
a live product has a continuing mix of feature, reliability, design, and infrastructure work;
your internal team needs a managed delivery unit rather than isolated contractors; or
priorities are expected to change, making a rigid fixed scope impractical.
It may be the wrong fit for a one-off task with a stable specification, a company that only needs one specialist under its own leadership, or a team that is not ready to assign a product owner and make timely decisions.
Questions to ask an SDaaS provider
Before signing, ask for direct answers to these questions:
Who will work on the account, and which roles are shared across customers?
What limits concurrent work or monthly capacity?
Where will source code, infrastructure, and product data live?
What evidence is required before work is considered complete?
How are incidents, urgent defects, and out-of-hours requests handled?
Can priorities change during the subscription, and what happens to work already in progress?
What is the cancellation period, and what does the final handover include?
The answers matter more than the label. They reveal whether the service is a transparent delivery model or ordinary outsourcing with a subscription price.
How Smicolon's SDaaS model is structured
Smicolon uses a recurring delivery model for product teams that need coordinated product, design, and engineering work. The current subscription plans define the commercial options; the delivery approach keeps work in the customer's repositories and infrastructure, with reviewable changes and an explicit route to production.
For a prototype that needs engineering hardening, see Prototype to Production. For examples of delivered product surfaces, review the case studies. If you are comparing delivery models, bring the current product, constraints, and desired outcome to a project conversation; the useful next step may be a subscription, a defined project, or neither.
---
# How to Build an MVP Without Cutting the Features That Actually Make It Work
Source: https://smicolon.com/blog/how-to-build-an-mvp-without-cutting-the-features-that-actually-make-it-work
Updated: 2026-08-26T15:31:42.260Z
Every founder feels the same pull in two directions. Ship now, before a competitor gets there first — but don't put something in front of users that makes you wince. Speed and pride rarely point the s
How to Build an MVP: The Definitive Startup MVP Development Guide
Every founder feels the same pull in two directions. Ship now, before a competitor gets there first — but don't put something in front of users that makes you wince. Speed and pride rarely point the same way.
If you want to know how to build an MVP, you first have to understand the risk you're actually managing. Here's intermediate data: 42% of startups fail because they build products with no real market need. They do not fail because they shipped too early. They fail because they spent months building something nobody wanted.
This core challenge is why we created this operational startup MVP development guide. Below, we break down how to identify the right features, manage technical execution, balance speed and craft, and secure early market validation.
What an MVP Actually Is
Let's get precise, because vague definitions cause expensive planning mistakes.Definition: A Minimum Viable Product (MVP) is a working product built with the absolute minimum set of core features required to solve one primary problem for a specific target audience. It is designed to gather validated, real-world learning with minimal effort.
An MVP is not a prototype. It is not a half-finished beta you apologize for. It is a fully executed product with deliberately limited scope.
Prototype vs. Proof of Concept vs. MVP
To keep your product scope focused, it helps to distinguish these three development phases:
| Stage | Primary Goal | Target Audience | Core Deliverable |
| :--- | :--- | :--- | :--- |
| Prototype | Demonstrate user flow & layout | Backers, stakeholders, early design testers | Non-functional, highly interactive mockups |
| Proof of Concept (PoC) | Determine if a technical concept is possible | Internal engineering and technical leads | Bare-bones code and core architecture tests |
| Minimum Viable Product (MVP) | Solve one real-world problem and validate demand | Selected early adopters and active users | Fully functional, high-quality core product |
The most damaging myth is that "minimum" means "barely functional." If your first users churn because the core experience frustrates them, you haven't validated anything.
Consider this benchmark: up to 80% of features developed in traditional product launches go entirely unused. When you focus on essential features, you aren't cutting corners. You're refusing to build the four out of five things that won't matter to your early customers.
How to Identify What to Include in an MVP
Start with one question: What is the single problem this product solves, and for whom? Keep your answer to one sentence. The sharper your focus, the easier every feature decision becomes.
Sorting Minimum Viable Product Features
To decide what to include in an MVP, sort every proposed feature idea into three columns:
Must-Have: Directly delivers core value. Strip this feature out and the product no longer solves the user's primary problem.
Should-Have: Enhances the core experience but can be safely delayed for launch.
Nice-to-Have: Defer entirely. These are features for a product that has already proven its value.
To make it to the minimum viable product features list, a feature must trace directly back to the primary user problem. If you cannot draw a straight line from the feature to the problem, it moves to the Should-Have or Nice-to-Have list. No exceptions.
Mapping the Critical Path to Value
Find your critical path to value — the shortest user journey from signing up to experiencing the primary benefit. Every feature on that path is sacred. Everything off it is a candidate for deferral.
For example, if you are building a collaborative project management tool:
The Critical Path requires: Task creation, task assignment, and status updates.
What to defer: Custom dashboard analytics, color themes, third-party slack integrations, manual time tracking, and interactive gantt charts.
Reduce the amount of features you build, but never reduce how well you build them. Quality of execution on that limited scope is non-negotiable.
The Psychology of Cutting Features: MVP Development Best Practices
Cutting features is harder than building them. The reason is psychological, not technical.
Founders are closer to their products than any user will ever be. This closeness breeds feature anxiety — the gut belief that launching without a specific capability will doom the entire build. Feature anxiety feels like responsibility, but it is often the silent killer of early-stage startups. Launching late does far more damage than launching focused.
Applying proper MVP development best practices protects against this trap. Use this strict test on every feature: if it cannot be justified by a specific, named user problem that exists right now, it gets deferred.
This discipline delivers massive benefits:
Cost savings: A tightly focused MVP build can cut initial development costs by 30% to 70% compared to a fully-featured launch.
Shorter runways: It preserves capital for post-launch iteration, which is where real product-market fit is found.
What Founders Over-Prioritize Too Early
Advanced Analytics: You do not have enough users to analyze. Use simple, direct tools instead.
Complete Admin Dashboards: You can manage early users manually in database tables.
Complex Third-Party Integrations: Every API integration adds risk. Avoid them until core demand is proven.
Custom Notification Engines: Email alerts are sufficient at launch.
MVP Speed vs Quality: A Tactical Development Framework
"Speed versus quality" is a false choice. It convinces founders that shipping quickly requires shipping bad code. To master MVP speed vs quality, control your scope strictly while executing what remains with precision.
The Four Phases of MVP Development
A professional MVP development cycle generally spans 8 to 16 weeks from concept to launch using this structure:
```
Phase 1: Discovery & Scoping ➔ Phase 2: Design & Architecture ➔ Phase 3: Iterative Development ➔ Phase 4: Launch & Validation Loop
```
Discovery & Scoping: Define the single problem, target persona, and Must-Have feature list.
Design & Architecture: Map the critical path to value and set technical foundations that prevent code scaling issues.
Iterative Development: Build incrementally. Ensure you have stable, working internal builds at each sprint.
Launch & Validation: Deploy the product to your target user base and monitor key user activity.
Why Architecture Choices Matter
Technical decisions made during Phase 2 dictate how fast you can iterate post-launch. "Production-ready" for an MVP means building a secure, reliable, and scalable structure that will not buckle under early growth. You do not need enterprise-grade redundancy, but you also cannot use brittle templates that snap under load.
This balance is where an experienced engineering team is vital. At Smicolon, we structured our practices to ensure startups build on clean architectures that allow rapid, cost-effective scaling once the product gains traction.
How to Validate Your MVP Without Wasting Months
Validation means real users completing the core user journey and returning. Praise from advisors or friends who want you to succeed is not data. You need signal from target users who have no personal reason to be kind.
Three Validation Methods
Closed Beta: Release the MVP to a small, highly targeted user segment.
Concierge MVP: Deliver the core value manually behind the scenes. If you are building a curated recruitment platform, match candidates by hand first to prove users value the matches.
Landing Page Test: Measure interest and acquisition costs by asking users to sign up for early access before the product is fully coded.
Track One Metric
Select a single core metric that proves value. Avoid vanity indicators like page views or social shares. Instead, track:
Activation Rate: Do users reach the "aha" moment in their first session?
Return Visit Rate: Do they come back weekly without outbound marketing prompts?
Task Completion Rate: Do they successfully complete the core loop?
This quantitative data is invaluable for growth. Startups that launch with a functional MVP and clear validation metrics are 3 to 4 times more likely to secure venture funding than those with an idea slide deck alone.
Common MVP Mistakes That Quietly Kill Good Ideas
Building Without Feedback Mechanisms: Failing to build simple usage tracking or feedback loops directly into the launch code leaves you with no insights on user behavior.
Skipping UX Design: If your target audience cannot navigate your product, you will not know if they rejected your product's core value or just got confused by the interface.
Building for the Average User: Trying to please everyone dilutes your product. Target a highly specific persona first, then expand outward.
Expanding Before Validating the Core: Piling on secondary features before verifying the core value loop multiplies architectural bugs and user confusion.
Choosing a Developer on Initial Price Alone: Selecting a team on the lowest bids often results in badly organized code that requires a costly, slow rewrite when users start showing up.
Frequently Asked Questions (FAQs) About MVP Development
What is the difference between an MVP and a prototype?
An MVP is a fully functional product with limited features designed for actual customers to solve real problems. A prototype is an interactive, often non-functional mockup used internally or with testers to visualize layout and user flows.
What features should be included in an MVP?
An MVP should include only the "Must-Have" features required to complete the critical path to value. This means mapping the shortest user flow to solve your core user's primary problem, leaving all optional integrations, analytics, or secondary tools for future releases.
How long should it take to build an MVP?
A professionally scoped MVP typically takes between 8 and 16 weeks to design, develop, and prepare for launch. Projects that exceed this timeframe are usually over-scoped or lack clean architectural planning.
From MVP to Scale: What Happens After You Launch
Launch is not the finish line. It is the beginning of an iterative loop: Launch ➔ Measure ➔ Listen ➔ Refine ➔ Repeat.
A clean, well-architected codebase allows you to iterate quickly without rewriting the technical foundation. Startups that systematically test value propositions via MVPs are roughly 50% more likely to achieve sustainable, long-term revenue growth.
An MVP is ultimately a smarter way to invest. By combining focused scope with strong technical craft, you reduce market risk and build a foundation ready for sustainable growth.
Ready to define and build your MVP with a engineering partner that treats scope and architecture with clean precision? Book a discovery call with the Smicolon team today. We will help you scope your target product, choose the right tech stack, and deliver an MVP your customers want to use.
---
# AI in 2026: What Growing Businesses Actually Need to Know (And Do)
Source: https://smicolon.com/blog/ai-in-2026-what-growing-businesses-actually-need-to-know-and-do
Updated: 2026-08-26T15:31:52.397Z
A year ago, the conversation in most boardrooms and Slack channels sounded like this: *should we try AI?* In 2026, that question has quietly disappeared. The new one is sharper: *how deep should we go
AI for Small Business 2026: What Growing Businesses Actually Need to Know
A year ago, the conversation in most boardrooms and Slack channels sounded like this: should we try AI? In 2026, that question has quietly disappeared. The new one is sharper: how deep should we go, and how fast?
When deploying AI for small business 2026, the priority is moving past standalone tools and building integrated platforms. The statistics explain why: a 2026 U.S. Chamber of Commerce survey found that 89% of small businesses now use AI in some capacity, contrasting details with just 36% in 2023. This is not an incremental shift; it is an entire rewrite of SME operations in under three years.
For most operators, reality lies somewhere in the middle. You have tested several applications. Some yielded productivity gains, while others felt like shiny distractions that left you with more tabs open and no actual time saved. This article is your direct guide to separating noise from high-leverage opportunity, providing a clear blueprint for practical AI adoption for SMEs.
Business Automation Trends 2026: Moving from 'Bolt-On' to AI-Native
The AI tools of the early 2020s were largely disconnected point solutions: isolated chatbots, generic writing prompt windows, and single-purpose utilities. To use them, you had to manually export your data, run the prompt, and copy-paste it back into your primary environment.
In 2026, the paradigm has shifted. Leading business automation trends 2026 point toward deep, process-level integration tied directly to the bottom line. Consider this finding from Salesforce research: 91% of small businesses using integrated AI tools report measurable revenue increases. When more than nine out of ten adopters observe direct top-line growth, AI transitions from an R&D experiment into fundamental operational infrastructure.
To thrive, growing teams must understand the difference between Bolt-On AI and AI-Native architecture:
| System Metric | Bolt-On AI (Static Integration) | AI-Native System (Dynamic Integration) |
| :--- | :--- | :--- |
| Architectural Purpose | Feature toggles added to older, legacy applications. | Workflows rebuilt from scratch to capitalize on AI capabilities. |
| Data Pipelines | Fragmented across disconnected, manual environments. | Fluid, automated cross-system sync without manual exports. |
| Speed & Accuracy | Minor efficiency gains; still heavily reliant on manual inputs. | Immediate processing; system logs trigger automated triage. |
| Moat & Defensibility | Low; easily copied or replicated by competitors. | High; proprietary internal knowledge bases secure a custom moat. |
Practical AI Adoption for SMEs: Three High-Impact Opportunities
Investing in every shiny utility guarantees high subscription costs and negligible returns. Strategic founders should focus their resources exclusively on the three highest-leverage workflows:
1. Automating Operational Overhead
This is the fastest and most highly quantifiable win. According to industry business automation reports, 73% of modern businesses utilize AI automation to run daily administrative operations.
For data-heavy processes like invoice entry, customer routing, and cross-platform reporting, AI-driven workflows decrease processing errors by up to 85%. Instead of spending five hours on administrative back-and-forth, your team can allocate energy directly to client execution.
2. Accelerating Product Development
For businesses growing via proprietary technology, apps, or digital systems, AI integration accelerates workflows profoundly. McKinsey's 2026 Technology Trends data reveals that software companies integrating AI into their core development pipelines experience productivity boosts of 35% to 45%, compressing total time-to-market by an average of 30%. A feature that once occupied a six-week sprint is completed in four, giving you a distinctive competitive edge.
3. Deploying AI Tools for Startups to Compete at Scale
Enterprise capabilities that once demanded six-figure budgets are now democratized. Modern, agentic AI tools for startups allow emerging brands to offer 24/7 hyper-personalized customer communication, execute precise predictive analysis, and support scalable operations with a lean squad.
How AI Is Changing Software Development
If your strategic plan includes custom software, you must understand how AI is changing software development from the ground up. AI models no longer just auto-complete text; they generate clean codebase scaffolding, optimize logical architecture, catch regression bugs, and run regression suites instantly.
For non-technical leaders, this means faster sprint cycles, fewer production defects, lower operational costs per feature, and maximum code quality. When mundane boilerplate engineering is offloaded, your highly experienced engineers spend their time on core business logic, visual user experience, and building proprietary value.
However, over-relying on generic SaaS is risky. Gartner research warns that by 2030, 35% of basic, point-solution SaaS tools will be obsolete, completely replaced by intelligent AI agents. Organizations with rigid, single-purpose software stacks will face disruptive, costly migrations. Building custom, AI-ready architecture prevents this lock-in.
Five Steps to a Clear AI Adoption Roadmap
Successful tool integration does not require complex theory. It demands a pragmatic, modular workflow:
Audit Before You Automate: Identify manual bottleneck processes first. Focus on the repetitive, error-threatened tasks that eat up your team's Friday afternoons.
Clarify Tools vs. Deep Core Infrastructure: Use basic software features (like CRM integrations) for low-stakes processes. However, your core product and proprietary data deserve custom engineering to protect your strategic moat.
Optimize for Direct Integration: Avoid piling up individual point solutions. True progress lies in connecting workflows so your support, customer CRM, and reporting tools communicate in real-time.
Partner Rather Than Purchase: Select technology partners who understand your business model and adapt with you, safeguarding your budget from dead-end software purchases.
Measure Direct ROI Metrics: Define performance indicators before implementation. Insist on real metrics like time saved, processing speed, or error reductions to prove the business case.
Common AI Mistakes Growing Businesses Must Avoid
Automating a Broken System: Automating an inefficient process only scale-engineers the failure. Clean, define, and optimize the step manually before you layer in automation.
Relying on Fragile Third-Party Wrappers: Stacking critical operations on top of generic, cheap wrapper APIs exposes your business to sudden pricing shocks, dropped features, or service shutdowns.
Viewing AI as a Static Acquisition: AI requires continuous iteration, database maintenance, and prompt updates as underlying technology matures.
Neglecting Team Support: The most sophisticated custom assistant fails if your actual human staff doesn't trust it. Focus heavily on team training, guidelines, and cultural adoption.
Building Your Competitive Moat with Smicolon
The AI landscape of 2026 demands strategic clarity. Simple errors compound into expensive re-engineering and lost market share. Choosing a partner who aligns technology with concrete business outcomes is critical.
At Smicolon, we focus on building robust, long-term technical solutions. We avoid buzzword transformation claims, choosing instead to engineer clean custom software, reliable automation frameworks, and high-performance databases suited to your specific organizational needs. We explain the core engineering options in clear, practical terms so that you remain in complete control of your tools.
The window to build a definitive competitive barrier is wide open, but as automation reaches industry saturation, the edge will quickly become the baseline. Secure your operational speed today.
If you are ready to explore how clean custom software and process automation can drive growth for your brand, book a discovery call with us. Let’s cut through the noise and construct a sustainable software plan together.
---
# Digital Transformation in 2026: What's Actually Working for Mid-Market Companies (And What Isn't)
Source: https://smicolon.com/blog/digital-transformation-in-2026-what-s-actually-working-for-mid-market-companies
Updated: 2026-08-26T15:32:00.372Z
An effective **digital transformation strategy 2026** must reckon with a strange, stark paradox. This year, [74% of C-suite leaders rank digital transformation as their #1 strategic imperative](https:
Digital Transformation Strategy 2026: What's Working for Mid-Market Companies (And What Isn't)
An effective digital transformation strategy 2026 must reckon with a strange, stark paradox. This year, 74% of C-suite leaders rank digital transformation as their #1 strategic imperative (PwC CEO Survey 2026). Yet, research from Bain & Company reveals that 88% of business transformations fail to achieve their original ambitions.
When we read those two numbers together, the core challenge becomes clear: nearly every business leader agrees this is the priority, yet nine out of ten projects fall short. The resulting budget waste is staggering because global digital transformation investment is projected to reach $3.9 trillion by 2027 (Fortune Business Insights via Market.us).
To help mid-market leaders beat these odds, we have analyzed the data behind successful business digitalization. The defining success factor in 2026 is precision. Narrow, highly-focused projects deliver immense value, while sweeping overhauls collapse under their own weight.
Quick Digest: What Works vs. What Fails in 2026
What Succeeds (High ROI) | What Fails (Stalls & High Waste)
Precision over scale: Fixing one process first | Over-broad scope: Multi-system overhauls
Time recovery: Target measurable work reduction | Vague objectives: Chasing "digital maturity"
Cloud-first foundations: Iterative, rental scale | On-premise dependency: Large, rigid upfront infrastructure
Partnered development: Solving skills gaps quickly | Hiring bottlenecks: Stalling while recruiting full-time teams
Digital Transformation for SMEs: The Structural Advantage
There is a major data point that completely flips the enterprise-led narrative: SMEs with fewer than 100 employees are 2.7 times more likely to succeed at digital transformation than enterprises with over 50,000 employees (Market.us, Mordor Intelligence).
This structural advantage explains why digital transformation for SMEs is exceptionally potent in 2026:
Shorter decision chains: A change requiring thirty approvals at an enterprise needs just three at a 40-person company. Less overhead equals rapid implementation.
Minimal legacy debt: Lacking twenty years of tangled software, smaller companies can adopt modern tools without multi-year migration projects.
Tighter feedback loops: When the builder sits near the user, tool usability improves in days rather than quarters.
However, agility alone is not enough. Around 54% of leaders still cite skills gaps as a primary blocker. Success belongs to mid-market companies that execute deliberately while deploying business digitalization best practices to close technical resource gaps.
What's Actually Working in 2026
Mid-market initiatives that achieve their goals follow a predictable pattern. They avoid trying to transform everything and instead choose to digitize individual processes exceptionally well.
Precision Over Scale
Targeted automated workflows yield faster and higher returns on investment than sweeping software suites. For example, a logistics company that automates manual invoice reconciliation across email and spreadsheets saves dozens of hours immediately, paying for the execution in weeks.
Measurable Work Reduction as the Core Metric
The primary indicator of success isn't theoretical digital maturity—it is tangible hours saved, error rate reduction, and revenue unlocked. If you are integrating AI capabilities to drive this efficiency, our AI in 2026 guide frames how to apply this start-small logic to artificial intelligence.
Cloud-First Foundations
Cloud deployments held 62.65% market share in 2025 and are growing at a 22.1% annual rate (Mordor Intelligence). Mid-market firms choose cloud environments because they convert massive capital expenses into scalable operating costs. It enables companies to validate a prototype cheaply, scale it up if it succeeds, and pivot without sunk hardware assets. If you want to de-risk this path, you should learn how to build an MVP strategically before committing to a full build.
Digital Transformation Mistakes to Avoid
Understanding the common digital transformation mistakes to avoid is essential to keeping projects on budget and on schedule.
Over-broad Scope: Multi-department rollouts generate immense administrative friction that mid-sized teams cannot absorb. Bain & Company notes that bloated scopes are the single largest reason transformations miss target outcomes.
Chasing AI Without a Business Case: In 2025, 42% of leaders abandoned most of their AI initiatives before production, up from 17% the prior year (S&P Global). The driver was unclear business cases paired with runaway cloud costs.
Copying Enterprise Playbooks: Strategies designed for 500-person IT crews fail when forced onto a 15-person team. They burden the business with needless governance and planning overhead.
Treating Transformation as a One-Time Fix: Digital evolution is a continuous operational capability. Taking shortcuts to just "get it done" leads to technical debt; see our article on the cost of bad software for an analysis of how developmental shortcuts erode bottom-line profits.
A Pragmatic Mid-Market Digital Transformation Roadmap
Use this cyclical mid-market digital transformation roadmap to establish momentum without relying on massive budgets.
1. Pinpoint One High-Friction Process
Identify the workflow your team struggles with most—whether it is copy-paste data entry or delayed client reporting. Crucially, confirm that the friction can be measured in terms of weekly lost hours, error rates, or cycle times.
2. Establish ROI and Kill-Switches Prior to Building
Determine exactly what quantitative success looks like. Additionally, define a hard spending threshold. Setting a clear boundary prevents speculative projects from turning into bottomless money pits.
3. Deploy on Scalable, Cloud-Native Infrastructure
Pick modern cloud-native architectures. This ensures your initial small project can scale to support full company adoption without requiring an expensive infrastructure rebuild later on.
4. Close the Skills Gap Deliberately
Assess whether to build the solution in-house or collaborate with an experienced product development company. Waiting months to recruit specialized programmers often stalls transformation momentum. Our comprehensive framework comparing in-house versus outsourced development breaks down how growing businesses should navigate this make-or-buy choice.
5. Ship, Measure, and Repeat
Deploy the solution to production, verify the returns against your initial baseline metrics, and communicate the time-saving results to your team. Use that momentum to fund and justify the next process optimization.
How to Start Digital Transformation in Your Business
If you want to know how to start digital transformation without risking operational disruption, use this quick preparedness checklist:
Do you have one clearly manual, high-friction workflow?
Can you measure its current impact and define quantitative goals?
Do you have leadership buy-in for a quick, 90-day pilot project?
Have you determined the most cost-effective development resource to build it?
If you checked the first three, your business is primed to begin. The fourth step is where most hesitation lies. Fearing the "skills gap" keeps 54% of leaders stuck in the planning phase, but waiting to build a permanent in-house technical team can cost you a full year of strategic market advantage.
Starting small means the downside of being wrong remains trivial. A targeted, 90-day pilot with a pre-defined budget is a highly calculated, low-risk operational bet.
Build Your Strategic Roadmap with Smicolon
In 2026, market winners are defined by precision rather than spend index. Smaller businesses are uniquely structured to capture tech efficiency faster than legacy enterprises.
At Smicolon, we work as an extension of your leadership team to co-create, develop, and launch high-ROI digital workflows. We provide the senior engineering capacity you need to build and ship software fast, avoiding the high cost and delay of building an internal development arm from scratch.
Let's cut through the abstract theory. Book a discovery call with us today to discuss your highest-friction operational workflow and map out a high-impact, measurable digital solution.
---
# How to Write a Product Brief That Gets You Accurate Quotes (And Stops Scope Creep Before It Starts)
Source: https://smicolon.com/blog/how-to-write-a-product-brief-that-gets-you-accurate-quotes-and-stops-scope-creep
Updated: 2026-08-26T15:32:10.617Z
You wrote two paragraphs about your idea, sent it to three development agencies, and got back three quotes that agreed on almost nothing. One said $40,000. One said $110,000. One wouldn't commit to a
How to Write a Product Brief That Gets You Accurate Quotes (And Stops Scope Creep Before It Starts)
You wrote two paragraphs about your idea, sent it to three development agencies, and got back three quotes that agreed on almost nothing. One said $40,000. One said $110,000. One wouldn't commit to a number without a call first. If you have lived this, you know the frustration. Learning how to write a product brief is the single best way to end this cycle of confusion and secure accurate, reliable pricing for your next build.
Why Vague Briefs Get You Vague Quotes (And How to Scope a Software Project Wisely)
Those wildly different quotes weren't a sign the agencies were dishonest. They were a sign your brief left too much room for interpretation. A development quote always mirrors your brief: ambiguity in, ambiguity out.
When a development team cannot tell what you actually need, they do one of two things:
Pad the quote to protect against the unknown.
Lowball the bid to win the design contract, planning to recover the difference through expensive change orders later.
Either way, you lose. Knowing how to scope a software project protects your budget from these unnecessary markups.
The Direct Cost of Scope Creep
Unclear requirements lead directly to project delays and blown budgets. Industry data highlights how common this issue is:
52% of all projects experience scope creep (unplanned, runaway project expansions), according to research by the Project Management Institute (PMI).
45% budget overruns are typical for large IT initiatives, which also deliver 56% less business value than originally anticipated, according to a joint study by McKinsey & Company.
Four times higher costs can result from uncontrolled scope creep, according to technical analysis published by the IEEE.
Most founders and product owners have never been shown what developers actually need to see to provide an accurate estimate. Your product brief is the highest-leverage document in the whole lifecycle. Get it right and everything downstream gets easier—the timeline holds, the quote is defensible, and the software ships on budget.
What a Product Brief Is (vs. Other Documents)Definition: A product brief is a brief, structured document that acts as the bridge between your business vision and the engineering team's execution. It defines what problem you are solving, who you are solving it for, and how you will measure project success.
It is not a legal contract, a massive wireframe deck, or a 40-page technical specification. To keep stakeholders aligned, it helps to understand how the brief differs from other software documentation:
Document Type | Primary Purpose | Who Writes It & When | Relevance for Startups
Product Brief | Establishes business intent, user targets, and priority boundaries. | Product Manager/Founder (Pre-development) | Critical. The foundation for accurate scoping.
PRD (Product Requirements Document) | Detailed feature specifications and functional behaviors. | Product Manager (Once scope is locked) | Secondary. Startups rarely need this level of detail upfront.
SOW (Scope of Work) | Legally binding delivery agreement (prices, timelines, terms). | Development Agency & Client (Before signing) | Informative. Your brief directly shapes the final SOW.
RFP (Request for Proposal) | Formal bid-gathering document for competitive procurement. | Large Enterprise Procurement Teams | Optional. A clear brief and a strategic conversation work better.
Writing a clear brief does not require custom database designs or complex technical jargon. Clarity beats complexity every time. If you can describe your business problem to a colleague over coffee, you can write a high-converting brief.
This is about aligning with a partner who can surface the strategic requirements you might not even know to ask about yet. Shifting your perspective from hiring a feature-factory to aligning with a strategic product development partner changes the trajectory of your product. This is why choosing the right engagement model is so critical when deciding between in-house vs outsourced development.
Additionally, the best briefs are living documents—a single source of truth that evolves as you learn. Modern development practices rely on this adaptive approach to balance technical feasibility with core business goals.
How to Write a Technical Brief for Developers: 7 Core Elements
You do not need a massive, sprawling document. To ensure your development team writes an accurate quote, make sure your brief answers these seven core areas:
1. The Business Problem Statement
Describe the business problem in one or two sentences. Focus on the business outcome you want to achieve rather than the technology you think you need.
Outcomes-based: "Our regional sales team wastes hours reconciling active stock counts by hand, leading to fulfillment delays."
Prescribed feature-list: "Build a custom inventory application with real-time barcode scanning." (This limits developer creativity and can lead to over-engineering).
2. Target Audience and User Journeys
Who exactly is using this product, and what job are they hiring it to do? Name core roles (e.g., "field service techs," "billing administrators") and sketch the precise moments they will interact with the application.
3. Clear Success Metrics
How will you measure if this software build was successful? Tie success to a measurable key performance indicator (KPI), such as:
30% reduction in customer onboarding times.
50% fewer inventory reconciliation manual errors.
Lower support ticket volumes via self-service password resets.
4. Core Feature Matrix (MoSCoW Prioritization)
List out what the product needs to do, framed explicitly as user capabilities. Group them clearly into "Must-Haves" (for launch) and "Nice-to-Haves" (for future phases). This structured focus is essential when prioritizing features to build a capital-efficient product without cutting corners on user experience, helping you succeed when building an MVP.
5. Existing Technical Context and Constraints
Identify what components currently exist. Are you integrating with an external CRM like Salesforce, handling payments via Stripe, or working with a legacy database? Do you have strict compliance rules to meet (such as HIPAA, GDPR, or PCI DSS)? These details are the single greatest drivers of technical estimation accuracy.
6. Desired Cost Parameters and Timeline
Sharing a realistic budget estimate does not lead to inflated bids; instead, it helps engineers design a solution that fits your economic reality. Giving a design group a budget scale of $75,000 to $100,000 allows them to propose architectural choices that deliver the target outcome within those boundaries.
7. Core Project Assumptions and External Dependencies
Outline everything your project team relies upon that is outside of the codebase. This includes third-party API access, branding files, content copy, or regulatory clearance sign-offs. Unspoken dependencies are where project timelines go to die.
Avoiding Scope Creep in Software Development: The "Out of Scope" List
Most briefs list what to build. Almost none list what not to build. This omission is the most expensive mistake you can make in your planning document.
Documenting what you are not building is your absolute best defense for avoiding scope creep in software development. It prevents feature creep—the slow, unapproved accumulation of minor requirements that silently inflates your budget and timeline.
According to studies on software project metrics, poor scope definition accounts for up to 92% of project failures. You can avoid this by including a dedicated exclusions section in your product brief.
For example:
"Phase 1 will exclude native iOS/Android applications—this is web-app only."
"Custom reporting tools and analytics dashboards are deferred to Phase 2."
"Automated multi-currency billing calculations are out of scope for this MVP."
Listing these boundaries clarifies expectations for everyone today, and serves as a powerful decision-making framework tomorrow. When a stakeholder proposes a brand-new feature mid-build, you can easily point to the brief, park the idea in the Phase 2 backlog, and keep Phase 1 moving forward dynamically. This simple discipline is crucial for avoiding the hidden, downstream cost of bad software.
Focus on Problems, Not Prescribed Solutions
Over-specifying your technical environment typically results in higher quotes and lower quality solutions. When you draft your brief, prioritize describing your problems rather than prescribing specific tech stacks. This gives professional software architects the freedom to find cleaner, more affordable paths to launch.
Focusing on outcomes does not mean losing control of your build. Instead, it transitions your relationship from hiring simple programmers to working with a strategic engineering partner.
How Engineering Partners Evaluate Your Brief
When an expert agency reads your document, they scan it for three indicators:
Complexity Drivers: Deep third-party integrations, strict custom security policies, or complex data manipulation engines.
Critical Unknowns: Areas in your requirements where assumptions must be made due to lack of detail.
Risk Buffers: How much pricing padding they must add to cover details left unsaid.
A collaborative software partner uses a dedicated discovery process to systematically uncover these hidden engineering elements. If an agency gives you a firm, guaranteed project price off a vague brief without asking structural questions, consider it a red flag. They are either padding the price heavily or bidding low to hook you before hitting you with inevitable change orders.
How a development company acts during discovery tells you if they are a simple vendor or a true product development partner. This distinction is vital when evaluating your long-term outsourced development costs.
Software Project Scope of Work Template: Your Copy-Ready Structure
Copy this template skeleton, paste it into your favorite editor, and fill out each prompt. Focus on clarity and honest context over formatting.
A Good Brief Deserves a Good Partner
Writing a highly structured product brief pays massive dividends in both initial budget management and team alignment. Grounding your project boundaries in a functional document translates directly into developmental transparency and realistic project timelines.
Your brief does not have to be perfect to start. A strategic development team works with you to refine your requirements, ask the right technical questions, and translate vague requirements into solid product strategies.
At Smicolon, we view project scoping as a collaborative software design process rather than simple order taking. We analyze your requirements to minimize complexity, identify potential pitfalls, and help you launch your platform with precision. If you are also aiming to understand wider market shifts like integrating AI for growing businesses, this strategic perspective is exactly what we bring to the table.
Ready to get an accurate quote on your software project? Bring your draft brief, no matter how simple or incomplete. Book a discovery call with Smicolon and let us design your build strategy today.
---
# What Are Agentic Workflows? A Plain-English Guide for Founders and Product Owners
Source: https://smicolon.com/blog/what-are-agentic-workflows-a-plain-english-guide-for-founders-and-product-owners
Updated: 2026-08-26T15:32:18.690Z
**What are agentic workflows?** An agentic workflow is an AI-driven process where the system plans, acts, and adjusts across multiple steps toward a goal instead of waiting for a human prompt at every
What Are Agentic Workflows? A Plain-English Guide for Founders and Product Owners
What are agentic workflows? An agentic workflow is an AI-driven process where the system plans, acts, and adjusts across multiple steps toward a goal instead of waiting for a human prompt at every turn. Strip away the vendor language and the agentic workflow meaning is simple: delegated responsibility. You set the goal, the boundaries, and the tools. The system works the task and comes back when it needs human input.
Every AI pitch deck now has "agentic" on slide three. Far fewer explain what changes for your team on Monday morning. This guide does, without code, mathematics, or inflated promises. By the end, you will understand what an agentic workflow is, recognize which of your business processes qualify, and ask sharper questions in your next vendor or board conversation.
What Is an Agentic Workflow in Plain English?
To understand what does agentic workflow mean in practice, compare it to traditional software:
Traditional automation is a vending machine. Known input, fixed mechanism, predictable output. Insert the wrong coin or jam the slot, and it stops.
An agentic workflow behaves like a capable new hire. You ask that person to investigate a customer complaint: check account history, consult company policy, propose a resolution, and escalate anything unusual. You define the objective and the limits; they decide the next reasonable step.
Moving to an agentic process means moving from fixed instructions to controlled autonomy across several steps.
An LLM (large language model) is an AI system that interprets and generates text. An LLM can power an agentic system, but a single LLM response is not a workflow. The defining features are planning, tool use, reflection, adjustment, and self-correction across an end-to-end process.
Andrew Ng frames agency as a spectrum rather than a binary label. As summarized in this overview of Andrew Ng's agentic AI course, systems range from single-response assistants to workflows that plan, use tools, review their own work, and coordinate several specialized agents.
That spectrum matters when you buy. A vendor does not need to promise full autonomy to deliver ROI. In most business settings, a moderately autonomous workflow with clear approval points gives you the best balance between speed, reliability, and control. Understanding how this fits into broader business strategy is essential—our insights on digital transformation in 2026 highlight how pragmatic AI adoption beats chasing overhyped tools.
How Do Agentic Workflows Compare With Traditional Automation?
The headline difference is fewer broken automations when conditions change. Traditional automation excels when every step follows a stable rule. Agentic systems earn their keep when the work requires judgment, investigation, or adaptation.
RPA (robotic process automation) uses software bots to repeat predefined actions, such as copying data between systems. RPA saves real time, but it runs on hard-coded rules. When a screen changes, data arrives in an unexpected format, or a system goes offline, the workflow stops.
Area | Traditional Automation or RPA | Agentic Workflow
Starting Point | Fixed trigger and predefined instructions | Goal, boundaries, and available tools
Decision-Making | Follows hard-coded rules | Chooses actions based on context
Handling Change | Fails when inputs or conditions differ | Reassesses and adjusts its next step
Failure Recovery | Stops, retries a fixed action, or alerts a human | Tries an approved alternative before escalating
Quality Control | Relies on preset validation rules | Reviews and critiques its own output
Human Role | Designs the entire sequence in advance | Sets goals, guardrails, approvals, and exceptions
Best Fit | Stable, predictable, repetitive tasks | Variable, multi-step work involving judgment
IBM's explanation of agentic workflows highlights one key operational difference: an agentic system can often recover from a dependency failure by switching to another approved tool without human intervention. In practice, that means fewer overnight pipeline failures, fewer tickets saying the bot broke, and less operational friction.
An agentic workflow is not a simple chatbot, nor is it RPA with an LLM bolted on top. It is a structured execution layer designed to sustain multi-step tasks. For growing organizations, Smicolon's analysis of growing business AI priorities provides broader strategic context for where these systems fit.
What Are the Four Building Blocks of an Agentic Workflow?
These four design patterns form the core structure of agentic systems. A credible solution provider should clearly explain which patterns your workflow uses and why.
1. Reflection: Checking Work Before Execution
Reflection cuts avoidable errors by having the AI review and critique its own output before finalizing it. Think of an employee proofreading an important client deliverable before hitting send. The workflow compares an answer against source material, identifies missing data, revises reasoning, or flags uncertainty.
2. Tool Use: Interacting With Business Systems
Tool use lets the workflow retrieve live data or execute approved actions instead of only generating text. A tool might be a database, search service, CRM, calendar, or payment gateway via an API (application programming interface). APIs grant agents controlled access to perform specific tasks without exposing underlying systems.
3. Planning: Deconstructing Goals Into Steps
Planning breaks a larger objective into smaller sub-tasks, determines their sequence, and adjusts the path as new information appears. For example, preparing a prospect brief requires identifying the target company, pulling CRM records, analyzing recent news, and formatting the summary.
4. Multi-Agent Collaboration: Specialized Role Delegation
A multi-agent system uses several specialized AI components cooperating like a project team. One agent gathers evidence, another drafts an answer, and a third audits the draft against compliance policies. While powerful, multi-agent setups add coordination overhead and cost, so simpler single-agent workflows should be evaluated first.
Practical Examples of Agentic Workflows in Growing Businesses
Here is how everyday business workflows change when moving to an agentic model:
Customer Support: Investigating Complex Tickets
Before: A rules-based bot labels a ticket by keyword. A human agent manually checks account history, order status, and refund policies.
After: The workflow categorizes the request, pulls system records, checks policy eligibility, proposes or executes an approved resolution, and escalates only edge cases.
Sales Research: Generating Prospect Briefs
Before: A sales rep opens a dozen browser tabs, searches internal records, and manually pastes notes into a document.
After: The workflow queries external sources, cross-references internal CRM data, cites sources, and delivers a structured brief prior to the call.
Operations: Dynamic Exception Handling
Before: Scheduled scripts copy data across finance and inventory systems. One formatting mismatch breaks the entire pipeline.
After: The workflow flags record discrepancies, attempts approved correction paths, logs actions taken, and routes unresolved exceptions to human operators.
Product Development: Context-Aware Handoffs
Before: Teams use disconnected AI tools to summarize user feedback, write spec drafts, and generate tests, manually moving context between tools.
After: A controlled workflow carries context through discovery, requirements, and testing. Product managers retain final approval while losing less context in handoffs.
Applying this discipline when building a focused MVP ensures you validate core value before over-engineering complex agentic layers.
According to a Pragmatic Coders research roundup, 51% of companies run AI agents in production, while 90% of surveyed non-tech firms plan deployments. Research on agentic AI adoption statistics shows 79% of organizations have adopted agentic AI to some degree, with 88% of executives increasing AI budgets as a result.
Furthermore, the GSDC Council's market overview notes that enterprises running agentic AI at scale report 20% to 30% operational cost reductions in repetitive workflows. Actual results depend heavily on process selection, data quality, and integration design.
Does Your Business Need an Agentic Workflow? Qualification Checklist
Not every process requires an AI agent. If a standard script or fixed API integration solves the problem, stick with the simpler tool. Run this four-question qualification checklist before investing in custom agentic development:Agentic Workflow Qualification Checklist >1. Does the process involve judgment calls? The next action depends on context rather than a rigid rule.2. Does it span multiple tools or systems? Team members currently gather data and take actions across several applications.3. Does it break when conditions change? Frequent edge cases justify dynamic decision-making and automated error recovery.4. Is the volume high enough to yield ROI? The frequency and business impact justify the initial development and monitoring costs.
Four Yes Answers: Prime candidate for an agentic workflow.
One Yes Answer: Standard automation or RPA is likely sufficient.
Two or Three Yes Answers: Requires process mapping and a focused cost-benefit analysis.
Market research from Market.us on agentic workflows projects the market to reach $199 billion by 2034. However, adoption should be driven by business ROI, not industry momentum. Avoiding rushed implementations helps prevent the real cost of bad software, where poorly planned AI adds tech debt rather than efficiency.
How to Evaluate an Agentic AI Vendor
Use these evaluation questions, red flags, and green flags during vendor demos to cut through marketing claims:
Key Evaluation Questions
How does the system handle failure and recovery? (Look for specific handling of API downtime or ambiguous data).
Where are the human-in-the-loop checkpoints? (Confirm who approves high-impact or sensitive actions).
Can we observe and audit decisions? (Verify that full execution logs and source citations are accessible).
What guardrails limit its actions? (Review spending limits, permission scopes, and fallback rules).
What happens to our business data? (Ensure data is not used to train external public models).
How will success be measured? (Track completion rate, exception rate, cost per task, and accuracy).
Who maintains the system? (Determine responsibility for updating integrations, prompts, and tools).
Red Flags vs. Green Flags
Red Flag: Vendor promises 100% full autonomy on day one without human oversight.
Red Flag: System actions cannot be audited or traced back to source data.
Green Flag: Partner proposes a phased rollout starting with restricted permissions.
Green Flag: Design includes explicit approval gates for sensitive or high-cost operations.
Getting Started With Agentic Workflows
Agentic workflows offer a scalable path toward automating complex, multi-step tasks. Their primary value lies in dynamic decision-making and failure recovery across real business tools.
To begin:
Select one high-friction process with frequent exceptions.
Run the process through the 4-question qualification checklist.
Baseline current metrics: execution time, error rates, and operational costs.
Define strict guardrails and human approval gates.
Launch a controlled pilot to validate performance before scaling.
Smicolon helps growth leaders and product teams map candidate processes, choose between standard automation and agentic architectures, and build production-ready pilots centered on measurable outcomes.
Have a specific workflow in mind? Book a discovery call with the Smicolon engineering team. In 30 minutes, we will map your process, pressure-test whether an agentic workflow fits, and define a practical scope—with no obligation.
---
# How to Run an AI Audit for Code Quality (Before Tech Debt Compounds)
Source: https://smicolon.com/blog/how-to-run-an-ai-audit-for-code-quality-before-tech-debt-compounds
Updated: 2026-09-27T01:18:03.488Z
Ask your engineering team what share of your codebase AI wrote. Whatever number comes back is probably too low.
How to Run an AI Audit for Code Quality (Before Tech Debt Compounds)
Ask your engineering team what share of your codebase AI wrote. Whatever number comes back is probably too low.
Most teams estimate about 20% of their merged code is generated by AI. The real share is often 60–80%, according to analysis cited by Sonar. An AI audit for code quality closes that gap: it tells you how much AI-assisted code you actually shipped, pinpoints hidden technical debt, and verifies whether your team can safely maintain and trust it.What is an AI audit for code quality? An AI audit for code quality is a structured review of code health, architecture, human ownership, and development governance across repositories containing AI-assisted or AI-generated code. It identifies security vulnerabilities, technical debt, and knowledge gaps before unvetted code compounds into systemic operational risks.
The gap between estimated and actual AI usage is where debt collects — in the parts of the system nobody scrutinises twice. The answer is not to stop using AI; it is to audit as fast as you build.
The Quality Gap Nobody Sees: Why AI-Heavy Codebases Need an AI Audit for Code Quality Now
AI-assisted development shortens delivery cycles, clears backlogs, and helps experienced engineers move faster. For growing businesses, that is a real advantage.
But speed changes the risk profile.
Sonar's research on AI and technical debt found that 88% of developers report at least one negative effect of AI on technical debt. A separate analysis reports that 53% of developers encounter AI-generated code that looks correct but is unreliable — a dangerous form of false confidence.
That is the unsettling part: clean formatting lowers suspicion. Reviewers spend less time on AI-generated pull requests because the code looks polished and familiar. Polish says nothing about whether the logic handles edge cases, respects system boundaries, or opens a security hole. Consequently, evaluating AI generated code quality requires specific processes beyond superficial syntax checks.
Meanwhile, most review and testing processes were designed for a slower release cadence. Static application security testing (SAST) examines source code for security weaknesses before it runs. Dynamic application security testing (DAST) tests a running application from the outside. Both still matter — but they have to keep pace with AI-assisted delivery.
So the practical response is mandatory human review, backed by automated quality and security gates.
The four-step framework below gives CTOs and product owners a concrete framework to conduct an AI code quality audit, set a baseline, find architectural drift, expose ownership gaps, and stop new debt from compounding. First, though, it helps to know what you are looking for.
The Three Hidden Debts AI Code Creates
AI-generated code creates three kinds of debt. Each needs its own audit lens.
1. Technical debt
Technical debt is the future work created when today's code is harder, riskier, or more expensive to change than it should be.
Forty percent of developers say AI increases technical debt by producing unnecessary or duplicative code. AI-generated code is also 10 times more likely to produce SAST findings, according to Cycode's analysis of AI and SAST.
Typical examples:
Duplicate validation functions with slightly different behaviour
Dependencies added for tasks the existing code already handles
Complex branches that satisfy one prompt but ignore the broader requirement
Security checks implemented inconsistently across similar features
Each issue looks small alone. Together they inflate testing time, incident risk, and the cost of every future change. That is how debt quietly accrues interest.
2. Comprehension debt
Comprehension debt appears when the code exists but nobody understands it well enough to change it safely. In plain terms: the system works today, and the team cannot explain why.
AI generates implementation without generating the context a developer normally builds while solving the problem. Unless the team records its assumptions and decisions, documentation falls behind. Addy Osmani calls this comprehension debt: the growing cost of understanding generated code after the fact.
The bill arrives during an incident, a handover, an audit, or an urgent product change.
It is the main reason AI-generated code is hard to maintain once it changes hands.
3. Architectural debt
Architectural debt builds when individual changes stop following the system's intended design.
AI tools optimise for the prompt in front of them. They do not protect the architecture of the whole product. One feature calls a shared service. The next reproduces the same logic in a controller. A third introduces a new pattern entirely.
All three can pass their tests while the system gets harder to maintain.
This is the false-confidence trap. Overall AI code quality cannot be judged by readability alone. Clean-looking code deserves more scrutiny, not less.
Step 1: Establish Your Baseline With Continuous Static Analysis
A point-in-time scan tells you what a tool found today. A continuous baseline tells you whether quality is improving or deteriorating sprint by sprint.
That distinction matters in AI-heavy repositories, where monthly SAST findings can climb from roughly 1,000 to more than 10,000, according to Cycode. A single scan gives you a long list. Trend data tells you where the list came from and whether the problem is accelerating.
Start by measuring four areas during your AI code quality audit:
Measure | Audit question | Initial output
Vulnerability density | How many security findings appear relative to the amount of code or number of changes? | Findings by severity, module, and release
Duplication rate | How much logic is repeated instead of reused? | Duplicate blocks ranked by maintenance risk
Complexity hotspots | Which functions carry too many branches, dependencies, or responsibilities? | Ten highest-risk files or functions
Dependency health | Are libraries outdated, unsupported, vulnerable, or unnecessary? | Dependencies to remove or upgrade
The security baseline deserves the most attention. A formal study summarised by Augment Code examined 3,500 code artifacts generated by seven major large language models and found a mean vulnerability rate of 55.8%. (A large language model, or LLM, is the type of AI system behind most coding assistants.)
Don't lean on traditional DAST alone. Conventional dynamic scans can take eight hours or more — longer than an AI-assisted team needs to build and deploy a change. Contrast Security explains why traditional DAST struggles with that release velocity.
Keep runtime testing, but add SAST in continuous integration, focused API tests, software composition analysis, and faster runtime security checks. Continuous integration (CI) means automatically testing each proposed change before it can be merged.
Your output should be a one-page baseline a product owner can read: the four measures, their trend over recent sprints, the highest-risk modules, and the three recommended next actions. Don't bury the decision in a 100-page scanner export.
Step 2: Check for Architectural Drift
Architectural drift happens one merged pull request at a time, as new code quietly stops following the intended design.
Run the audit with three direct questions:
Do modules respect their boundaries? Check whether user-interface code reaches straight into databases, whether business rules leak into controllers, and whether one service reads another's private data.
Are several implementations solving the same problem? Search for repeated validation, authorisation, formatting, retry, and error-handling logic.
Are conventions fragmenting? Compare naming, folder structures, API patterns, logging, and exception handling across recent features.
Three techniques give you the evidence:
Review the dependency graph — the map of which modules rely on one another. Look for circular dependencies and unexpected links between unrelated areas.
Analyse module coupling. Coupling measures how tightly one part of the system depends on another. High coupling means a small change in one module can break several others.
Compare recent pull requests with your architecture decision records. An architecture decision record, or ADR, is a short document explaining an important technical choice and the reasoning behind it.
Prioritise pull requests created or heavily revised with AI. Red flags: reinvented utilities, inconsistent error handling, near-identical functions across features, and new libraries that duplicate what you already have.
Record every drift finding with four fields — affected module, violated decision or convention, business impact, recommended owner. That turns an architectural concern into work the team can plan.
If the audit exposes deeper structural problems, treat remediation as part of product planning, not invisible engineering housekeeping. The same logic applies when evaluating the cost of bad software: postponing foundational work makes later delivery slower and less predictable.
Step 3: Map Ownership and Close the Comprehension Gap
For every critical module, name a human who can explain:
What the module does
Which business rules it protects
What depends on it
How it fails
How to test a change safely
If nobody can answer those questions, comprehension debt is already on your balance sheet.
Use an explain-it-back test. Pick a high-risk module and ask its owner to walk another engineer through it without opening the documentation. The point is not memorisation. It is to see whether the owner understands the data flow, key decisions, failure modes, and operational risks.
Score the result:
Green: The owner explains the module and answers change-impact questions confidently.
Yellow: The owner understands normal behaviour but not edge cases or dependencies.
Red: No owner exists, or the explanation depends on reading the code during the session.
This step matters most for outsourced codebases. A supplier can deliver working features while keeping most of the system knowledge inside its own team. When the relationship ends, you own the repository without owning the understanding needed to run it.
So when you weigh in-house vs outsourced development, put knowledge continuity next to cost and delivery capacity. Contracts and repository access are necessary, but they are not the same as explainable ownership.
Fix red areas with short documentation sprints, ADRs for the important decisions, and pairing sessions between knowledgeable contributors and permanent owners. Start with modules tied to revenue, sensitive data, authentication, payments, and core operations.
The output is an ownership map: every critical module, its primary owner, backup owner, documentation status, and latest explain-it-back result.
Step 4: Put AI-Specific Governance Gates in Place
Good governance keeps AI's speed advantage without accepting hidden risk.
Start with a disclosure rule. Contributors flag pull requests containing AI-assisted code — in-house engineers and external development partners alike. Disclosure is not an admission of poor quality. It helps reviewers spend their attention where it counts.
Then calibrate human review around risk:
Require a named human reviewer for every AI-assisted change.
Require a domain owner for changes touching critical business rules.
Ask reviewers to validate assumptions, edge cases, and failure paths — not formatting.
Block authors from approving their own changes.
Require tests that prove expected failure behaviour as well as success behaviour.
Add automated security gates to CI. Define which SAST findings block a merge, which need documented acceptance, and which can go to the backlog. A gate without an enforcement rule is just a report.
Where traditional DAST is too slow, run focused runtime tests on changed endpoints and critical workflows, and schedule broader dynamic scans separately rather than dropping them.
Hold outsourced teams to the same gates as internal developers. Write AI disclosure, review evidence, test expectations, dependency approval, and documentation duties into the delivery agreement. Governance should follow the code, not the employment arrangement.
Then set two rhythms:
Every sprint: Review new findings, AI-assisted changes, ownership changes, and architecture exceptions.
Every quarter: Recalculate the full quality baseline, rerun ownership tests, inspect drift trends, and update the remediation roadmap.
That cadence turns an AI audit for code quality into an ongoing management system instead of a one-time cleanup. It also supports a more disciplined approach to AI adoption for growing businesses: take the advantage, and put controls around the risk.
The AI Audit for Code Quality Scorecard
Use this scorecard in your next sprint review. Score each dimension green, yellow, or red on evidence — not instinct.
Dimension | Green | Yellow | Red | Required action
Quality baseline | Metrics run continuously and trends are visible | Metrics exist but scans are irregular | No baseline, or only isolated reports | Configure continuous scans and publish a one-page baseline
Security findings | Critical findings block merges and have owners | Findings are reviewed but enforcement varies | Findings pile up without triage | Define merge thresholds, owners, and remediation deadlines
Architectural drift | Recent changes follow documented boundaries | Exceptions exist but are known | Duplicate patterns and boundary violations are spreading | Review dependency graphs and prioritise high-impact drift
Ownership coverage | Every critical module has a primary and backup owner | Some modules depend on one person | Critical modules have no explainable owner | Run explain-it-back tests and assign accountable owners
Documentation | Critical flows and decisions are current | Documents exist but miss recent changes | The code is the only reliable source of knowledge | Schedule focused documentation and ADR work
AI disclosure | In-house and outsourced contributors flag AI-assisted work | Disclosure is informal or inconsistent | Reviewers cannot identify AI-heavy changes | Add disclosure to pull-request templates and delivery rules
Review governance | Risk-based human and automated gates are enforced | Policies exist but teams bypass them | Clean-looking code merges with minimal scrutiny | Introduce mandatory review and CI blocking rules
Treat any red score in security, ownership, or critical architecture as an immediate planning concern. Several yellows signal a compounding problem even when no single metric looks urgent.
Remediate in-house when your team has the architectural knowledge, the capacity, and the authority to change the delivery process. Bring in an outside engineering partner when ownership is unclear, the architecture spans unfamiliar technologies, findings cross several teams, or an independent assessment would raise confidence.
Neither choice is automatically better. The real question is whether the people doing the work can diagnose the problem, explain the trade-offs, and leave you with stronger ownership than you started with.
Repeat the scorecard quarterly, and compare direction as well as colour. A yellow moving toward green is healthier than a green propped up by stale evidence.
Don't Wait for the Debt to Compound
AI velocity is a genuine advantage — for teams that audit as fast as they ship.
Technical, comprehension, and architectural debt compound differently, so each needs its own instrument. Static analysis exposes implementation and security problems. Architecture reviews reveal drift. Ownership mapping finds knowledge gaps. Governance gates stop next sprint from recreating this sprint's issues.
If you believe AI generated 20% of your merged code, audit as though the real number is 60–80%. Not knowing exactly what is in your codebase is not a reason to panic. It is a reason to gather evidence.
Teams that repeat this cycle keep the speed and shed the hidden cost. They also give CTOs and product owners a defensible answer when customers, executives, or regulators ask how software quality is controlled.
Smicolon helps growing teams assess AI-heavy and outsourced codebases, prioritise what matters, and turn findings into a practical remediation roadmap. If a second set of expert eyes would help, book a discovery call — one conversation, no larger engagement required, and you leave with a clearer view of your own code.
---
# The Verification Gap: Why AI Writes Code Faster Than Your Team Can Safely Own It
Source: https://smicolon.com/blog/the-verification-gap-why-ai-writes-code-faster-than-your-team-can-safely-own-it
Updated: 2026-08-26T15:32:35.250Z
Your team is shipping more code than ever. Almost nobody fully trusts it.
The Verification Gap: Why AI Writes Code Faster Than Your Team Can Safely Own It
Your team is shipping more code than ever. Almost nobody fully trusts it.
AI now writes or assists roughly 42% of committed code, according to Sonar's 2026 State of Code survey of more than 1,100 enterprise developers. The same respondents expect that share to reach about 65% within two years — and 96% of them say they do not fully trust AI-generated code to be functionally correct without manual verification.
That pairing, not the adoption rate, is the core issue. What is the impact of AI-generated code on long-term maintainability when generation outruns human judgment? As software teams embrace automated output, maintaining high AI code quality and ensuring long term maintainability requires closing the gap between code creation and human verification.
Velocity Went Up. Safe Ownership Capacity Did Not
More than a third of the developers Sonar surveyed say reviewing AI-generated code takes more effort than reviewing human-written code. So the industry is accelerating production with a tool whose output nearly everyone agrees must be checked twice.
That is the verification gap: the distance between how fast code can be written and how fast a team can verify its intent, architectural fit, operational safety, and long term maintainability.
Generating code is not the same as safely shipping a product. A feature can look complete while carrying assumptions that conflict with the wider system. It can pass an initial test while making the next change harder. It can work in normal conditions and fail on the edge case nobody thought to describe to the AI. Ignoring these risks increases the real cost of bad software over time.
For business leaders, this is not a debate about developer tools. It is an org design, delivery planning, and vendor selection problem. When code output rises without matching verification capacity, the velocity chart improves but delivery does not. You are borrowing against maintainability, and the business repays that debt through slower features, riskier releases, and a rising cost per change.
The Bottleneck Moved From Writing Code to Verifying Intent
Before AI, writing the first version of code consumed a large share of development time. Faster generation genuinely sped up the whole system. That logic breaks once generation stops being the constraint.
Sonar found that developers now spend roughly 24% of their workweek checking, fixing, and validating AI output. Effective AI code maintenance and verification is no longer incidental cleanup — it is a measurable cost that belongs in staffing models, delivery estimates, and vendor pricing. In the broader landscape of AI strategy for growing businesses, managing output verification is the primary driver of sustained engineering velocity.
Engineering roles are shifting with it. A CIO Dive analysis of changing engineering work describes three responsibilities: delegate, review, own.
Delegate: Give AI bounded tasks and enough context to produce useful work.
Review: Check correctness, security, intent, consistency, and architectural fit.
Own: Accept responsibility for how the software behaves in production.
Think of AI as a fast, highly confident junior writer. It never tires, rarely pauses to express doubt, and can produce ten pages while a human is still outlining the first. Speed does not remove the need for an editor-in-chief. It increases the volume that editor must assess.
Once review becomes the slowest stage, faster generation does not improve safe throughput. It builds a larger queue of unverified work. Sometimes that queue is visible as pull requests waiting for approval. More often it hides inside rushed reviews, shallow tests, unresolved architectural questions, and code that technically works but nobody fully understands.
Leaders who still measure productivity mainly by output volume are measuring the stage that has already become cheap.
What Is the Impact of AI-Generated Code on Long-Term Maintainability?
The impact of AI-generated code on long-term maintainability stems from what happens when thousands of individually plausible suggestions pile up inside one product over time. The long-term maintainability of AI-generated code degrades when speed is prioritized over structural cohesion.
GitClear's research into AI-assisted development points to deteriorating maintainability signals as adoption scales. Code written and then rewritten or deleted within two weeks — commonly called code churn — has risen from about one-third to nearly two-fifths of new code. The research also finds rising duplication and less refactoring.
Each signal has a direct business consequence:
High churn means teams keep revisiting work they just finished.
Duplication means the same business rule lives in several places, so every future change must be made repeatedly and consistently.
Less refactoring means fewer hours spent improving the structure that keeps future changes affordable.
AI is very good at producing a locally plausible answer. It does not protect the global coherence of a system.
Imagine expanding a city by approving each building separately. Every building can be structurally sound while the city becomes impossible to navigate, because nobody is protecting the road network, utilities, zoning, and shared design rules. Architecture plays that role in software. Local correctness is necessary and nowhere near sufficient.
Weak AI code maintenance shows up in business metrics long before anyone reads a code report:
Feature estimates stretch because each change touches more dependencies.
Releases get riskier because teams cannot predict every side effect.
New engineers take longer to become productive because patterns are inconsistent.
Incidents take longer to resolve because ownership and intent are unclear.
Cost per change rises even as the cost of producing code falls.
This is the familiar technical-debt curve, accelerated by higher output. Cheap implementation becomes expensive ownership whenever quality controls are postponed. Evaluate AI code quality across the entire lifecycle of the product, not merely by whether a generated feature passes today's test suite.
How AI helps with code reliability when verification is strong
AI is not inherently bad for reliability. When paired with strict verification processes, how AI helps with code reliability becomes clear: it can surface missing unit tests, compare repetitive patterns, flag likely edge cases, and allow engineering teams to examine multiple implementation options before committing to one.
Those gains depend entirely on human direction. AI enhances code reliability when it expands a team's ability to inspect and test software — not when its output is treated as self-validating.
The Org Design Problem Nobody Priced In
The first-order effect of AI is faster production. The second-order effect is a widening gap between output volume and the human judgment available to own it. For leaders comparing in-house vs. outsourced development, that gap fundamentally alters team staffing and vendor selection models.
Senior engineers become the verification constraint
AI increases the amount of code reaching senior reviewers without adding hours to their week. Those engineers still have to evaluate architectural consistency, security implications, test quality, operational behavior, and whether the change solves the right problem.
Under sustained volume, review quality degrades. Fast approvals feel productive because work keeps moving, but the deferred cost stays in the product. Senior engineers also lose the capacity for architecture, mentoring, and hard product calls.
Verification capacity costs money and slows raw output. That is an honest trade-off. The alternative is not free speed — it is rework on an unpredictable schedule with a bigger business impact.
Production still needs a human owner
At 2 a.m., when a failure stops customer payments, "the AI wrote it" is not an incident response plan.
Someone has to understand the affected area, assess the blast radius, make a safe repair, and stand behind the decision. If a team merges more code than it understands, the on-call engineer inherits a system without the reasoning behind it.
Assign ownership when AI-assisted code enters the product, not when it fails.
Junior engineers still need paths to judgment
Junior developers build judgment through first-pass implementation, feedback, debugging, and review. When AI absorbs most of that first-pass work, growing teams have to protect the learning loop deliberately.
A CIO discussion of AI and code review highlights the risk to knowledge sharing when review practices weaken. Today's juniors are tomorrow's senior reviewers. If they learn to accept output without learning to challenge it, verification capacity gets scarcer every year.
That means structured mentoring, design discussions, incident participation, and reviews that explain why a decision is safe — not just whether it was approved.
The leaders ahead of this curve are not rejecting AI. They are redesigning the human system around it.
A Verification Capacity Model for Long Term Maintainability
Generation speed is a weak predictor of safe delivery. A better model starts with the scarce resource: qualified human review.Safe throughput = senior review hours available ÷ verification cost per unit of AI-assisted code
A "unit" can be a pull request, feature, integration, or any consistent change package. Consistency matters more than the definition. The point is to compare how much AI-assisted work enters the system with how much your team can responsibly verify and own.
The five inputs to estimate
Input | What to measure | Business question it answers
Senior review bandwidth | Hours experienced engineers can realistically spend on review after architecture, support, and leadership duties | How much qualified verification capacity actually exists?
AI verification multiplier | Review effort for an AI-assisted change versus a comparable human-written change | Does AI reduce total effort, or move effort from writing into checking?
On-call ownership coverage | People able to diagnose and repair each production area | Who owns this code when normal assumptions fail?
Architectural review cadence | Frequency and depth of cross-system design checks | Who protects global coherence as local changes accumulate?
Rework and churn rate | Recently completed work that is rewritten, removed, or repeatedly reopened | Is apparent velocity turning into future work?
Skip the company-wide average. Verification cost varies by risk.
A low-impact internal change can follow a lighter process. A payment workflow, permissions system, regulated-data pipeline, or core integration deserves deeper review and named ownership. Build that difference into the model.
How to use the model in planning
Estimate how many AI-assisted change units your team produces in a typical week. Then estimate the senior review time each unit requires, including validation, architectural assessment, and follow-up corrections.
Multiply output by verification cost, then compare the result with the senior review hours you genuinely have — not the hours implied by an org chart.
If AI doubles first-pass output, do not assume delivery capacity doubled. Ask whether review bandwidth, test infrastructure, architectural oversight, and production ownership can absorb the extra work. If they cannot, the surplus either sits in a verification queue or reaches production with weaker scrutiny.
Use the model in three places:
Hiring plans: Add senior verification and mentoring capacity alongside output-generating roles.
Release planning: Cap work in progress when verified throughput falls behind generated output.
Vendor evaluation: Ask partners to show how their staffing model supports the volume of AI-assisted work they produce.
The model is deliberately simple. Its job is to expose the planning error that velocity metrics hide: when generation capacity exceeds verification capacity, you are not shipping faster. You are accumulating unowned code.
Questions to Ask Any Development Partner Who "Uses AI"
Almost every development partner uses AI now. The useful question is how they control, verify, and own what it produces. Take this checklist into your next vendor conversation.
Verification staffing
How do you staff senior verification relative to AI-assisted output?
Which work requires senior review, and which can follow a lighter process?
How do you account for checking and correcting AI output in estimates?
What happens when generated output exceeds available review capacity?
Architecture and code health
What is your architectural review process for AI-assisted contributions?
Who checks whether a change follows existing system patterns rather than merely working in isolation?
How do you track churn, duplication, rework, and refactoring health?
How do you stop repeated AI suggestions from creating several versions of the same logic?
Production ownership
Who owns AI-generated code after deployment?
Who responds if it causes a production incident?
How is implementation intent documented for future maintainers?
Can another engineer safely change the feature if its original author is unavailable?
Team development
How do junior engineers build judgment when AI does first-pass implementation?
Are reviews used for knowledge sharing, or only for approval?
How do senior engineers coach people to challenge plausible but incorrect output?
Commercial transparency
Is verification capacity included in the quoted price and delivery plan?
Are estimates based on generated output, or on reviewed, tested, production-ready work?
Who pays for rework when weak verification causes problems later?
Treat a steep AI discount with no matching verification staffing as a red flag. That partner is reducing the visible cost of generation and transferring maintainability risk to you.
The right partner will not pretend verification is free. They will show you where AI reduces effort, where human judgment stays essential, and how both appear in the delivery model.
How Smicolon Closes the Verification Gap
Smicolon pairs AI-accelerated delivery with senior engineering judgment, structured review, and named ownership.
The goal is not maximum code volume. It is software your business can safely change, operate, and scale — which means treating verification capacity as part of delivery, not a quality layer bolted on near release.
Smicolon staffs and prices that capacity openly. AI supports faster research, implementation, testing, and analysis. Experienced engineers stay responsible for product intent, architecture, code quality, and production behavior.
That makes long term maintainability a deliverable: consistent system-wide patterns, clear ownership, and less chance that this quarter's speed becomes next year's rewrite. Smicolon stays invested in the health of the product your team will operate years from now, not the number of tickets closed this month. For a deeper look at the approach, read Smicolon's guide to AI-generated code quality and maintenance.
Own What You Ship: The Takeaway and Next Step
AI moved the bottleneck from writing code to verifying it. Long term maintainability now depends on whether human review, architectural oversight, and production ownership can keep pace with generated output. Leaders who plan for that constraint compound AI's benefits. Those who ignore it inherit code their teams cannot safely own.
Run the verification capacity model against your team this week. Count actual senior review hours, compare them with AI-assisted output, inspect recent rework, and confirm who owns each critical production area.
If you work with an external partner, ask them to run the same exercise. Their answer should cover staffing, review depth, architectural controls, on-call responsibility, and how verification shows up in the price.
The result may tell you that you need more review capacity or tighter limits on work in progress. That feels slower than celebrating a rising output chart. It is far cheaper than finding the gap through a delayed release, a repeated rewrite, or a 2 a.m. incident.
Book a discovery call to pressure-test your verification capacity — 30 minutes with Smicolon's senior engineers, no pitch deck, and you leave with a clear read on where your generation and verification capacity diverge.
AI is a genuine multiplier, for teams structured to verify, understand, and own what it produces.
---
# Automated Code Maintenance vs. Manual Maintenance: Which Model Holds Up When AI Writes the Code?
Source: https://smicolon.com/blog/automated-code-maintenance-vs-manual-maintenance-which-model-holds-up-when-ai-wr
Updated: 2026-08-26T15:32:43.452Z
**Automated code maintenance vs manual maintenance** is no longer a theoretical debate—it is a core budget line for modern engineering teams. **Automated code maintenance** relies on software tools an
Automated Code Maintenance vs. Manual Maintenance: Which Model Holds Up When AI Writes the Code?
The Maintenance Bill Nobody Budgeted For
Automated code maintenance vs manual maintenance is no longer a theoretical debate—it is a core budget line for modern engineering teams. Automated code maintenance relies on software tools and AI agents to continuously scan, test, and refactor code, while manual maintenance depends entirely on human engineers to review, test, and repair software changes. When organizations adopt AI coding assistants, code output scales exponentially, but human review capacity remains fixed.
Disney has reportedly asked its engineers to limit AI-generated code in final products—not to reject AI, but to protect quality, reliability, architectural oversight, and human control.
When an organization that size starts drawing lines around where AI code can land, the question of maintaining long term maintainability stops being an academic discussion. It becomes an urgent strategic decision.
Here is the mismatch: AI-assisted development multiplies how fast a team produces code. It does not multiply the team's capacity to review, test, repair, and improve that code after launch.
Most leaders notice the gap indirectly:
Releases generate more follow-up work and emergency hotfixes.
Engineers spend their weeks firefighting code shipped last month instead of building roadmap features.
Overall delivery slows down even though the team is writing more code than ever.
That is rarely an engineering failure. It is a structural one: an operating model built for human-paced development cannot absorb AI-accelerated output.
So post-launch maintenance becomes a funding decision. Do you keep relying on manual review and add headcount as output grows? Do you automate as much as you can? Or do you split the work between machines and people?
This article provides a practical framework for choosing a model that protects delivery capacity, budget predictability, and long term maintainability.
What the Data Says About AI Code and Long-Term Maintainability
The problem is not that AI sometimes writes poor code—humans do that too. The problem is what happens to a codebase when producing new code becomes far easier than consolidating and governing what already exists.
GitClear's research on AI code quality shows maintainability declining as AI-assisted coding has spread. For the first time in its data, copy-and-pasted code surpassed moved code. Moved code signals refactoring—reorganizing existing code so it is cleaner and easier to maintain, without changing what the software does for users.
The shift is steep. Refactoring fell from roughly 25% of code changes in 2021 to under 10% in recent data. Teams are adding code faster while spending less of their effort improving the structures underneath it.
The research also found rising code churn—code rewritten or deleted shortly after it was written. Lines revised within two weeks rose from 5.5% to 7.9%. In business terms: a growing share of your development capacity is going into fixing fresh work instead of moving the product forward.
Duplicated code blocks increased eight-fold. Duplication hides well because the application still functions. The bill arrives later when engineers must update the same logic in five places, defects get harder to trace, and small changes need days of testing.
These patterns compound into technical debt—the future cost of choosing a quick implementation over a maintainable one. Like financial debt, the interest accrues, often revealing the real cost of bad software as maintenance spending accelerates.
The conclusion is uncomfortable: AI-generated code can create a maintenance workload that grows faster than development output. When production rises while refactoring falls, churn climbs, and duplication multiplies, a manual-only maintenance function is absorbing far more than extra volume.
If you want to know your current exposure, start with an AI code quality audit rather than waiting for a missed deadline to reveal it.
The Manual Maintenance Model: Strengths and Breaking Points
Manual maintenance puts engineers at the center of code review, testing, repairs, upgrades, and architectural improvement. For complex systems, that human involvement is irreplaceable.
An experienced engineer can spot that technically valid code contradicts a business rule. They can judge whether a shortcut will box the system in next year, notice a subtle security risk, and ask whether a feature belongs in the architecture at all.
People also hold context that automated checks lack. A test can confirm an invoice calculation matches a defined rule. Only a person can decide whether the rule itself reflects your contracts, edge cases, and commercial obligations.
Where Manual Maintenance Breaks Down
The limit is capacity. Review hours are fixed; AI-assisted output is not. When developers ship more changes without a matching increase in review capacity, queues form and reviews get rushed.
Then comes the headcount trap. Keeping pace manually means hiring more engineers or pulling existing ones off roadmap work. Both hit the budget trajectory: one raises payroll, the other shrinks the capacity available for features and customer commitments.
Pressure also creates a loop:
Reviewers approve more with less scrutiny to protect release dates.
Those unvetted changes produce more defects and cleanup work.
Engineers have even less time for careful review in the next cycle.
Manual maintenance does not break because human judgment lacks value. It breaks because that judgment is expensive, scarce, and easily consumed by repetitive work.
Architecture, complex logic, and security decisions still need people. The funding question is narrower: should your engineers spend their limited attention on those decisions, or on checking formatting, duplication, dependencies, and routine test results?
The Automated Maintenance Model: What It Actually Covers
Automated maintenance uses software tools and AI agents to inspect, test, and update parts of a codebase continuously or on a schedule. It is strongest wherever the work is repetitive and rule-governed.
Key areas covered by ai code maintenance include:
Dependency hygiene: Keeping third-party software packages current, compatible, and free of known vulnerabilities.
Duplication detection: Identifying copied code blocks across repositories before technical debt compounds.
Continuous integration testing: Executing regression and unit tests on every pull request automatically.
Static code analysis: Enforcing formatting, style standards, and structural guidelines.
Automation wins here because it is consistent and tireless. It runs the same checks on every change without losing focus during a hectic release week, catching routine problems before they reach production or an engineer's review queue.
This proactive inspection illustrates how AI helps with code reliability. Effective ai code maintenance scans large volumes of pull requests, spots recurring code smells, proposes routine fixes, and routes complex edge cases directly to human developers.
Limits of Automated Code Maintenance
The limits are real. A tool may flag duplicate functions without knowing which version holds the correct business rule. It may propose a package upgrade without seeing that a rarely used customer workflow depends on legacy behavior.
Automation also cannot own architectural accountability. It supplies evidence, flags risk, and suggests options. A qualified person still decides whether a design supports your expected scale, security requirements, and long-term product vision.
The strongest objection to automation is fair: teams can start using it as a substitute for engineering judgment. That risk is real if leadership treats a green build as proof the code is safe.
The better goal is protecting engineers' time. Automation should absorb predictable inspection work so people can concentrate on architecture, ambiguous requirements, security reasoning, and complex failure scenarios.
Automated Code Maintenance vs Manual Maintenance: A Funding Framework
The right model depends on three factors: code velocity, risk profile, and root cause patterns. The framework below breaks down automated code maintenance vs manual maintenance across parameters that impact team capacity and budget predictability.
Decision factor | Manual maintenance | Automated maintenance | Hybrid maintenance
Cost structure | Tied to engineering hours and headcount | Tooling setup and governance, but checks do not consume human hours | Funds automation for volume, humans for high-value judgment
Scalability with growth | Scales only by adding or reallocating engineers | Repetitive coverage expands across all incoming changes automatically | Automation absorbs volume; human review targets high-risk code
Coverage consistency | Varies with reviewer workload, experience, and fatigue | Applies defined rules identically on every build | Consistent automated baseline plus targeted human context
Response time | Subject to engineer availability and queue bottlenecks | Inspects code changes instantly on push/commit | Instant feedback on hygiene; escalation for critical logic
Risk profile | High contextual nuance, but vulnerable to review fatigue | Catches known patterns, but lacks strategic business context | Structural coverage paired with human architectural oversight
Early-stage products with small codebases
A small product with low change volume does not need an elaborate maintenance platform. Manual review works while engineers still understand most of the system and the review queue stays manageable.
Even so, fund basic automated tests and structural checks early. They set habits before growth arrives and stop the team from normalizing avoidable cleanup work. That matters most when building an MVP, where speed rules but foundational shortcuts shape every later release.
Recommendation: A light hybrid model. Keep human ownership close to the code, but automate repeatable checks from day one.
Growth-stage products with AI-accelerated output
This is where manual-only maintenance breaks first. The codebase is expanding, customer expectations are rising, and AI-assisted developers generate more changes than a fixed review team can assess properly.
Adding reviewers buys temporary relief, but it ties maintenance capacity directly to headcount. If churn and duplication are climbing too, you end up hiring people merely to manage the consequences of your own output volume.
Recommendation: Fund a structured hybrid model. Automate routine testing, dependency checks, duplication detection, and standards enforcement. Reserve engineers for high-risk reviews, architecture, security decisions, and recurring root causes.
Legacy systems undergoing modernization
Legacy software hides dependencies, documentation gaps, and business rules layered in over years. Automation can map patterns, run regression tests, and surface structural issues—but automated changes carry more risk when nobody fully understands every hidden connection.
So modernization needs broad automated visibility paired with careful human sequencing and approval. It is also why successful mid-market digital transformation turns on operating-model choices, not new technology alone.
Recommendation: A human-led hybrid model. Expand automated analysis and regression testing, but require experienced engineers to approve architectural updates and migration steps.
Three Questions That Reveal Which Model You Need
How fast is the codebase growing? Compare incoming pull request volume against your capacity to review, test, and maintain it.
What is your review-to-output ratio? If code production rises while review time stays flat, unvetted technical debt accumulates even if release schedules look fine.
Where do your worst bugs come from? Repetitive structural mistakes favor automation. Ambiguous business rules, architecture flaws, and security gaps require people.
The model you fund today sets your technical debt trajectory for years. A weak model rarely fails loudly. It quietly eats capacity until engineers spend more time stabilizing last month's work than building what customers need next.
Why Hybrid Wins: Automation for Hygiene, Humans for Judgment
Neither pure model holds up across the full range of post-launch engineering work.
A manual-only model wastes expensive human attention on thousands of predictable checks. An automation-only model risks approving code that passes technical tests while violating business intent, security standards, or architectural strategy.
The hybrid model splits maintenance according to the cognitive load required:
Automation handles structural hygiene: Routine unit tests, dependency monitoring, duplication scans, and standard enforcement.
Engineers handle architectural strategy: Security boundaries, complex business rules, and multi-system integration decisions.
Industry research across software engineering literature confirms this alignment: automation excels at repetitive, rule-based inspection, while humans excel at contextual reasoning and design judgment. Each covers a critical blind spot the other cannot reach alone.
The reported Disney decision underlines this principle. A company can invest heavily in AI while establishing clear parameters for where AI-generated code reaches production. That is not resistance to progress—it is pattern recognition: faster code generation creates business value only when the underlying software remains dependable and governable.
What Hybrid Maintenance Looks Like in Practice
Automated gatekeeping on every pull request: Code formatting, unit tests, security scans, and duplication checks execute automatically.
Self-service feedback for developers: Low-risk findings return immediately to the author to fix before requesting peer review.
Targeted human review for high-risk changes: Senior engineers review authentication logic, payment workflows, data privacy boundaries, and core architecture.
Systemic feedback loops: If reviewers repeatedly flag the same pattern, leadership converts it into an automated check or reusable component.
Metric-driven governance: Leaders track maintainability trends (churn, refactoring ratios, review queue depth) and adjust tooling and staffing proactively.
The payoff is not just reduced review overhead. It is maximizing the value of your existing engineering team. Skilled developers stop re-checking routine formatting and start preventing architectural failures.
It also stops maintenance from being treated as an individual performance issue. If AI-assisted output has overwhelmed your review pipeline, asking engineers to work harder will not fix the ratio. Only an operating model designed for AI-era code output will.
Teams that adopt a structured hybrid model early secure a durable advantage. While competitors lose roadmap capacity to code churn and duplicated logic, hybrid teams maintain their velocity, code quality, and market responsiveness.
Building a Maintenance Model That Scales With You
Choosing between automated code maintenance vs manual maintenance is not an all-or-nothing decision. Manual maintenance alone cannot economically scale with AI-assisted output, while automation alone cannot enforce business logic or own architectural integrity. A hybrid model funds each where it delivers the highest return.
Start by assessing your current codebase: evaluate review queue bottlenecks, code churn rates, recurring defects, dependency debt, and the percentage of engineering time spent fixing recent releases. These metrics indicate whether your operating model protects engineering capacity or drains it.
Next, define clear boundaries: specify which checks run automatically, which changes require human sign-off, and which high-risk areas receive scheduled engineering review. Do not leave maintenance governance to chance.
Smicolon helps startups, SMEs, and mid-market enterprises design and run sustainable post-launch operating models—evaluating codebase health, establishing the right mix of automated and manual controls, and providing dedicated engineering capacity to maintain software quality as you scale.
We do not build products and walk away. We engineer maintenance frameworks that safeguard code quality, protect margins, and preserve long-term delivery velocity.
Ready to audit your maintenance strategy and identify the optimal model for your growth goals? Book a discovery call with Smicolon. In a 30-minute strategic consultation, we will analyze your risk profile and outline an actionable operating model tailored to your team.
---
# Aligning AI-Generated Code With Engineering Standards: A Checklist Product Owners Can Actually Use
Source: https://smicolon.com/blog/aligning-ai-generated-code-with-engineering-standards-a-checklist-product-owners
Updated: 2026-08-26T15:32:51.664Z
Your team ships a feature in half the usual time. Two sprints later, engineers are still untangling it.
AI-Generated Code Engineering Standards Alignment: The Checklist Product Owners Can Actually Use
Your team ships a feature in half the usual time. Two sprints later, engineers are still untangling it.
That is the trade most teams miss. Without AI-generated code engineering standards alignment, speed does not disappear — it moves. It moves into review queues, bug reports, and the sprint you had reserved for the next release. Maintaining high AI code quality is essential to prevent rapid creation from degrading into technical debt.
For Product Owners, the question is not how the code got written. It is whether today's speed costs you next quarter's roadmap. Understanding what growing businesses need to know about AI helps frame these delivery trade-offs effectively.
This guide turns that risk into five actionable questions you can ask in sprint planning, acceptance reviews, and vendor calls — no coding background required.
The Bottleneck Has Moved From Writing Code to Reviewing It
AI-assisted development changes the shape of delivery. Engineers produce a first draft faster. Every draft still has to be understood, tested, reviewed, and maintained.
So Product Owners see an uncomfortable pattern: development looks faster while pull requests, review queues, and bug reports pile up beside it. The constraint is no longer writing code. It is proving the code is safe to own.
The quality data backs that up. A 2026 compilation of AI-generated code quality metrics reports that AI-generated code is associated with:
1.7 times more total issues than human-written code
1.64 times more maintainability errors
1.57 times more security findings
Duplication adds another layer. GitClear's code quality research documents an eightfold increase in duplicated code blocks. Duplicate logic can work perfectly today and still make every future change slower. One business rule ends up living in three places, each behaving slightly differently.
The answer is not to stop using AI. The answer is to review earlier and more deliberately. Teams handling this well rely on centralized rules files, AI-specific review checklists, automated boundary checks, and mandatory senior review on security-critical changes. The principle is simple: catch quality problems before code reaches final testing, not after a customer finds them.
The five areas below are where AI-generated code most often drifts from your standards. Each one ends with a plain-language question you can ask without reading a single line of code.
What Is the Impact of AI-Generated Code on Long-Term Maintainability?
AI-generated code can reduce long term maintainability when adoption outpaces engineering controls. The immediate result is faster code production. The later result is duplicated logic, inconsistent structures, more security findings, slower changes, and heavier dependence on senior developers to explain or repair the system.
AI accelerates creation. It does not reduce ownership.
The second-order effects cost the most. An AI tool solves the task in front of it without seeing the product's wider architecture. It writes a new version of logic that already exists, places code in the wrong part of the system, or follows a pattern that contradicts an earlier decision. Each issue looks small alone. Together they build technical debt that compounds quietly until it blocks a release or turns a simple-looking feature into a two-sprint project.
The delivery numbers show why this belongs on your agenda, not just engineering's. The research summarized by Second Talent associates unmonitored AI adoption with:
A projected 7.2% decrease in delivery stability for every 25% increase in AI adoption
9% longer cycle times
30% higher change failure rates
These findings do not mean AI automatically damages delivery. They show what happens when generation speed rises while review capacity, standards enforcement, and human ownership stay flat.
Maintenance also stays human work. AI does not remove it — it shifts it downstream, into the sprint after the demo.
For a Product Owner, long term maintainability is a budget line, not an engineering abstraction. It decides how many features fit into a quarter, whether urgent fixes interrupt the roadmap, and how confidently you can commit to a launch date. Poor alignment today becomes budget bleed and slipped dates next quarter. Smicolon's guide to the real cost of bad software walks through that compounding effect.
Why Product Owners Need Their Own Checklist
"Isn't code quality the tech lead's job?"
Technical leaders own engineering decisions. But you own acceptance, prioritization, risk trade-offs, and the definition of done. Those decisions determine whether engineers have the time and the authority to apply quality controls at all.
Standards alignment usually fails for one reason: the standards live only in one senior developer's head. A new hire does not know the correct pattern. An external partner does not either. An AI tool has even less context unless the rules exist somewhere it can read.
So standards need to appear in:
Acceptance criteria
Sprint planning
The team's definition of done
Pull request templates
Release reviews
Vendor and agency conversations
This does not turn you into a technical lead. It gives both roles a shared language. You can ask whether architectural boundaries were checked without deciding how those boundaries should be coded. You can require a named test owner without writing the tests.
Think guardrails, not gatekeeping. You get real leverage over delivery quality while technical judgment stays with the people qualified to exercise it.
If your team already reviews AI output slower than it arrives, that is the verification gap in practice. The five checks below help close it.
AI-Generated Code Engineering Standards Alignment: The Five Checks
1. Enforce naming conventions
Names in software are labels for concepts, actions, and data. Consistent names let engineers read a system. Inconsistent names force them to stop and investigate.
AI tools produce plausible names. Plausible is not the same as consistent with your product. One feature calls a customer an "account," the next says "client," a third says "user." Six months later, nobody is certain whether those three words mean the same thing.
Your team should document its naming conventions and product vocabulary, then let tooling enforce the mechanical rules. A linter is an automated checker that flags code breaking agreed formatting or naming rules. A centralized rules file gives developers, reviewers, and AI tools one shared reference point.Checklist takeaway — naming conventions >Question to ask engineering: Do we have a centralized rules file that AI tools and reviewers both reference? >Evidence to request: Naming conventions and product terminology are documented, available to AI tools, and enforced by automated checks where possible.
2. Protect architecture boundaries
Software architecture defines how the parts of a system fit together. Boundaries set which components may talk to each other and where each responsibility belongs.
AI can write code that works and still put it in the wrong layer, or wire together two components meant to stay separate. The feature passes. The architectural bill arrives later, when a change in one area breaks something nobody connected to it.
Define boundaries in plain terms: what talks to what, where business rules live, which shared components must be reused. Automated tools catch some violations. Reviewers catch the rest.
Boundary checks also protect the DRY principle — short for "Don't Repeat Yourself." DRY does not mean deleting every repeated line. It means keeping important business logic in one reliable place instead of scattering copies across the codebase.
Without that discipline, AI regenerates similar logic for every new task. A pricing rule lands in checkout, invoicing, and account management. When the rule changes, engineers must find and update all three. Miss one, and customers get inconsistent prices.Checklist takeaway — architecture boundaries >Question to ask engineering: Have we defined what each part of the system can communicate with, and do reviewers check those boundaries? >Evidence to request: Architecture boundaries are documented, automated checks cover the enforceable rules, and reviewers confirm reuse before accepting new logic.
3. Require senior review on security-critical paths
Some code carries far more business risk than the rest. Anything touching authentication, authorization, payments, sensitive data, or compliance controls deserves extra scrutiny.
Authentication confirms who someone is. Authorization decides what that person can see or change. Both determine whether user and company data stay protected.
Anything involving personally identifiable information (PII) belongs in this group too. PII is data that can identify a person: a name, an email address, an account number, or similar details.
AI-generated code is associated with more security findings than human-written code. More importantly, this risk is asymmetric. Saving an hour in implementation never offsets exposing customer data, charging a card incorrectly, or granting one user access to another user's account.
Every AI-generated change on a security-critical path needs a named senior reviewer. "The team reviewed it" is not ownership. Put the name in the pull request — the formal request to review and merge a code change.Checklist takeaway — security-critical paths >Question to ask engineering: Which parts of this feature touch authentication, permissions, payments, or sensitive data, and who is the named senior reviewer? >Evidence to request: Security-critical paths are listed, AI-generated changes cannot bypass review, and a senior engineer records approval before the code merges.
4. Give humans ownership of tests and edge cases
AI drafts tests quickly. It also writes tests that confirm the code does what the code already does, rather than what the business needs.
That difference matters. Take a discount feature that calculates the right amount for a typical order. The obvious test passes. Now what happens when two discounts overlap, a refund is partial, the currency changes, or eligibility expires mid-checkout?
Those are edge cases: the less common situations where systems actually fail. Finding them takes product knowledge, risk awareness, and a feel for how real users behave.
So a human should own the test strategy for every feature. AI can generate routine tests, but a named person decides what "covered" means and confirms the main business scenarios, the failure conditions, and the edge cases.
This matters even more for an early product. An MVP that protects essential behavior beats a broader release whose core workflows break under real conditions.Checklist takeaway — test ownership >Question to ask engineering: Who is the named owner for tests on this feature, and which edge cases did a human write? >Evidence to request: A human owns the test plan, business-risk scenarios are listed, and human-authored edge cases sit alongside any AI-drafted tests.
5. Define your No-AI zones
Not every part of a codebase should be open to AI generation. Some areas depend too heavily on history, specialist knowledge, or strict controls.
Common No-AI zones:
Core business rules that define how the company makes decisions
Authentication and authorization infrastructure
Compliance-sensitive processing
Payment and financial calculations
Legacy integration points with incomplete documentation
Safety-critical or irreversible operations
The logic is simple. In these areas, one subtle error costs far more than the time saved writing the code. An AI tool reads the code in front of it. It does not know why a strange-looking exception exists, which regulation shaped a decision three years ago, or which partner system breaks when a field changes.
Build the list together — Product Owner and technical lead — then add it to contributor guidelines and pull request templates. Keep exceptions explicit, rare, and approved by a senior engineer.
No-AI zones should cover a small fraction of the codebase. Everywhere else, AI still helps with routine implementation, documentation, prototypes, test drafts, and lower-risk components. This is targeted risk management, not AI rejection.Checklist takeaway — No-AI zones >Question to ask engineering: Have we agreed which parts of the codebase are off-limits to AI-generated changes? >Evidence to request: No-AI zones are documented, agreed with engineering leadership, visible during review, and backed by a clear exception process.
The Full Checklist: Copy It Into Your Next Sprint Planning
Use this in planning, acceptance criteria, release discussions, or partner reviews.
Three habits make the checklist stick:
Review it quarterly. AI tools, product risks, and team structures change. Your guardrails should change with them.
Put it in the definition of done. Standards alignment is not an audit after implementation. It is part of finishing the work.
Use it with vendors and agencies. Ask prospective partners how they enforce each item. Their answers show whether they treat AI as a shortcut or as a tool that still demands accountable engineering.
The checklist reduces risk. It does not remove it. Automated checks enforce known rules; they cannot replace senior judgment about unfamiliar threats, architectural trade-offs, or business-specific edge cases. If AI use has grown faster than your controls, a focused AI code quality audit will show you where to start.
Get Senior Eyes on Your AI-Assisted Codebase
Teams that use AI well never choose between speed and quality. They let AI accelerate the work while experienced engineers enforce standards, own the difficult tests, protect security-critical paths, and challenge code that shines in a demo and buckles in production.
Growth-stage companies rarely have spare senior capacity to build those guardrails. Your technical lead is already balancing architecture, hiring, delivery, incidents, and stakeholder requests. A growing AI review queue stretches that person thinner.
Smicolon closes that gap as a senior-guided technology partner. We help teams use AI without giving up scalability, security, or code quality: turning standards into working controls, pinpointing where human review matters most, and making ownership clear before hidden technical debt reaches your roadmap.
Bring your current review process. We will walk through the five checks with you and show you where the gaps are — no preparation needed, no obligation.
Book a discovery call to pressure-test your AI code standards
AI velocity and engineering discipline are not competing goals. With clear boundaries, accountable reviews, and experienced judgment, your team keeps the speed of AI and still ships software it can change, secure, and trust years from now.
---
# Before Agents Ship Your Features: The Human Checkpoints Every Product Owner Should Demand in an Agentic Workflow
Source: https://smicolon.com/blog/before-agents-ship-your-features-the-human-checkpoints-every-product-owner-shoul
Updated: 2026-08-26T15:32:59.924Z
An AI agent could open a code change against your product this quarter: reading the ticket, writing the implementation, generating the tests, and reporting the work as done. One question decides wheth
Before Agents Ship Your Features: The Human Checkpoints Every Product Owner Should Demand in Agentic Workflows
The Question Isn't Whether AI Joins Your Delivery Team. It's Who Stays in Charge
An AI agent could open a code change against your product this quarter: reading the ticket, writing the implementation, generating the tests, and reporting the work as done. One question decides whether you bought speed or liability — who approved the plan it worked from?
Agentic workflows are moving into mainstream software delivery, and your development partner may already be pitching "agentic delivery" as a faster way to plan features, write code, expand tests, update documentation, and prepare releases. Your job as a product owner is not to judge whether the technology works. It is to decide what you approve, and which decisions stay human.
What Are Agentic Workflows?
So what are agentic workflows? An agentic workflow is an intent-driven process where AI uses natural-language instructions and autonomous reasoning to execute a sequence of software engineering tasks. Instead of following fixed, predetermined steps, an agent interprets a goal, chooses actions, evaluates results, and keeps working toward the outcome. That is the agentic workflow meaning buyers need: you give the system a destination, and it helps pick the route. For a deeper breakdown of foundational concepts, explore our plain-English guide to agentic workflows.
Understanding agentic workflows in AI requires recognizing how they operate within modern continuous integration and continuous deployment (CI/CD) pipelines. GitHub Agentic Workflows describes agents handling repository tasks such as issue triage, documentation updates, test improvements, and reporting. The same approach has been described as "continuous AI" inside software delivery.
The speed is real. So is the need for control.
A large language model (LLM) is the core AI engine powering ai agentic workflows. When an LLM makes a wrong assumption early in a multi-step workflow, later agents build on it. The result looks consistent while being consistently wrong.
Implementing strict human checkpoints in agentic workflows is what separates useful acceleration from avoidable technical debt and product damage. Below are the exact requirements to write into a statement of work (SOW) — the legal agreement defining what a development partner will deliver and under what conditions. Bring them to vendor meetings before you sign, and you will ask the questions that matter without being talked past.
Why "Fully Autonomous" Should Be a Red Flag, Not a Selling Point
Picture an agent misreading a feature requirement. It writes the wrong implementation plan. A second agent codes from that plan. A third generates tests that confirm the same mistaken interpretation. Every automated check passes, and the change reaches your customers.
One wrong assumption is now wrong code, reassuring test results, and a shipped defect. If nobody can trace the chain of decisions, fixing it takes more than reverting one change. Your team may need to repair affected data, integrations, documentation, and customer workflows.
That does not make agentic ai workflows unsafe. It means autonomy should match consequence.
Adding a label to an issue, drafting a comment, or preparing a draft pull request is reversible. A pull request is a proposed code change presented for review before it joins the primary version of the product. Work like this can run with light supervision.
Deploying to production, changing a database schema, or migrating customer data deserves a different standard. A database schema is the structural definition of how data is organized and related. Mistakes here reach live customers or alter information in ways that are hard to undo.
Even the platform builders design around that distinction. GitHub's model emphasizes narrow permissions, safe outputs, and sandboxed execution. Sandboxing means running the agent inside an isolated environment where it cannot touch live systems or unrelated resources. An independent review of GitHub's approach reaches the same conclusion: the guardrails are the point.
The workable model is hybrid. Automate routine, reversible work. Pause for human judgment when an action is ambiguous, consequential, or difficult to reverse. Published industry guidance on human-in-the-loop agentic workflows reflects this exact principle.
If platform builders demand guardrails, so should you. Here is what that looks like in your contract.
Checkpoint 1: Architecture and Scope Sign-Off Before Any Agent Writes Code
Before an agent implements a feature, a named human engineer or architect must approve the delivery plan, technical approach, system architecture, and scope boundaries.
Architecture is the high-level design of the product: how components, data, services, and integrations interact. You do not need to choose every technical detail. You do need assurance that a qualified person checked whether the approach fits your product, budget, security needs, and scaling roadmap.
Require agents to work from an approved planning artifact rather than an open-ended prompt — a technical design, implementation plan, acceptance-criteria document, or annotated feature brief. It should explicitly detail:
What the feature must accomplish
Which systems and code areas may change
Which areas are strictly out of scope
What technical assumptions the team is making
How the result will be validated
Which decisions require further human approval
Scope boundaries matter because a small feature can tempt an agent into rewriting adjacent components in pursuit of a cleaner solution. The result may be technically defensible but commercially wrong: longer reviews, elevated regression risk, and unauthorized work outside your approved roadmap.
That is why creating a clear product brief that prevents scope creep remains essential when agents join delivery. Better automation cannot fix ambiguous human intent.
Buyer language for SOW: "No agent-generated implementation begins until the delivery plan is reviewed and signed off by [role]. The approved plan must identify the systems the agent may modify, excluded areas, assumptions, acceptance criteria, and required human approvals."
Red flag — Invisible planning: The partner cannot produce the document, ticket, or approved plan the agent uses as input. If the agent receives only a broad prompt, nobody has drawn a line between your product request and the agent's interpretation.
Checkpoint 2: A Forbidden-Actions List for Every Agent
Every AI agent must operate under an explicit list of actions it can never perform autonomously. Policy rules alone are insufficient; access control settings must enforce these boundaries.
At minimum, forbid autonomous:
Production deployments
Database schema migrations
Access to secrets, credentials, API keys, or private certificates
Deletion of code branches
Modifications to CI/CD pipelines
External communication sent in your brand's name
Alteration or deletion of customer records
Approval of its own pull requests
Your development partner must apply the principle of least privilege, restricting permission scope to the bare minimum required for the task. A documentation agent may need write access to markdown files; it never needs access to production database credentials.
Safe outputs limit potential blast radius. Instead of mutating live environments, the agent creates a comment, attaches a label, generates a summary, or submits a draft pull request for human evaluation. You retain execution velocity while capping downside risk.
Ask to verify two assets: the exclusions clause in the SOW and the actual technical permissions assigned in the repository. They must align perfectly. "Our policy forbids agent deployments" is meaningless if the agent's API token grants deployment rights.
Buyer language for SOW: "Each agent must operate under a documented forbidden-actions list enforced through technical permissions. Agents may receive only the minimum access required for their assigned role. Production deployment, data migration, secrets access, customer-data deletion, CI/CD modification, and external communication require named human approval."
Red flag — Developer-equivalent access: "The agent has the same access rights as our human engineers." Human developers carry broad access alongside personal accountability and context. Single-purpose agents should never inherit broad administrative privileges by default.
Checkpoint 3: Human Review at Test Expansion and Merge
Agent-written unit and integration tests are useful, but they do not serve as independent verification that agent-written code is correct.
When the same model misinterprets a business requirement, it writes both code and tests matching that misunderstanding. All automated test suites turn green, yet the feature fails the business objective. This issue represents the verification gap in AI-generated code: generating code faster does not create the organizational capacity to inspect and maintain it. Before scaling agent deployment, teams should periodically run an AI code quality audit to catch subtle structural issues.
Require a qualified software engineer to inspect both code and tests prior to merging. A merge integrates approved code changes into the main branch, the authoritative codebase used for production releases. Agents can explain logic, respond to review feedback, and update code proposals, but they must never approve their own work.
Human review must go beyond surface-level checks. Establish clear evaluation criteria for reviewers:
Alignment with documented acceptance criteria
Comprehensive test coverage for edge cases and invalid inputs
Absence of regression risks in adjacent modules
Adherence to security, privacy, and performance standards
Maintainability and code complexity bounds
Complete documentation and rollback instructions
For high-impact architectural changes, mandate a secondary engineering review or product owner sign-off. Establish thresholds based on business impact rather than lines of code.
Buyer language for SOW: "All agent-generated changes enter the main branch only through human-approved pull requests. A qualified engineer must review the implementation and tests against documented acceptance, security, regression, maintainability, and rollback criteria."
Red flag — Unattended merge: Code produced by agents flows directly into production branches whenever automated tests pass, without mandatory human sign-off. This configuration allows the agent to author the logic, generate the test evidence, and approve the release.
Checkpoint 4: Audit Trails, Rollback Ownership, and Multi-Agent Handoff Rules
Governance requires complete operational traceability. Following any incident, your technical leaders must be able to answer four questions: Which agent acted? What action was taken? When was it executed? What prompt or approved plan authorized it?
Demand full audit logging covering prompts, intermediate outputs, tool executions, permission requests, human approvals, and system events. Logs must be human-readable, immutable, and retained for an agreed duration. SOW provisions should also specify data access and transfer rights upon contract termination.
Traceability must be paired with clear rollback accountability.
A rollback restores a software system or database configuration to a prior stable state. SOW terms should designate the role authorized to trigger a rollback, the engineering team responsible for execution, and target recovery time objectives (RTO). Rollback procedures must be tested ahead of production releases.
Multi-agent workflows introduce additional risk points. When one agent creates a plan, a second writes code, and a third generates test suites, errors propagate across handoffs. A valid output from the final agent does not validate the initial premise.
Require mandatory human checkpoint validation at critical agent handoffs. A qualified human must approve the architectural plan before coding agents execute, and inspect the code-test output before merging. Low-risk background tasks can utilize sampled audits, but thresholds must be defined in your contract.
Leading enterprise providers emphasize human governance in complex workflows. AWS details human-in-the-loop constructs for agentic workflows, while Microsoft outlines architecture patterns that pause execution for human input or approval. Both treat human oversight as an architectural requirement.
Buyer language for SOW: "The partner must provide reviewable audit logs for agent instructions, actions, outputs, approvals, and permission changes. A named human role must own rollback decisions and execution under an agreed response time. Multi-agent handoffs must include documented verification criteria and human approval at defined high-impact stages."
Red flag — Shared accountability: The vendor claims "the system manages safety" but cannot identify who reviews operational logs, who holds kill-switch authority, or who executes emergency recovery.
The Non-Negotiable SOW Checklist for Agentic Workflows
These governance rules maintain software quality, security, and strategic alignment while taking advantage of AI execution speed. Credible software engineering partners welcome these standards because they reflect mature engineering practice.
Checkpoint | Human Decision Required | Artifact to Demand | Named Red Flag
Architecture & Scope Sign-Off | Approve technical design, boundaries, and acceptance criteria before coding | Signed delivery plan or technical design document | Invisible planning: Implementation starts from raw user prompts
Forbidden-Actions Enforcement | Define prohibited autonomous actions and restrict API credentials | SOW exclusions clause & IAM permission audit report | Developer-equivalent access: Agents receive full administrative credentials
Test & Merge Verification | Review and validate code, test suites, and edge cases prior to main branch integration | Pull request review log with named human approver | Unattended merge: Passing automated builds triggers autonomous merging
Audit Logging & Rollback Ownership | Identify designated response leads and maintain system activity logs | Complete audit logs & tested rollback playbook | Shared accountability: Ambiguous ownership during production incidents
Multi-Agent Handoff Validation | Verify output accuracy at critical boundaries between multi-agent steps | Handoff verification protocol & escalation matrix | Blind chaining: Unvalidated outputs passed directly between agents
Critical Questions to Ask Vendors Offering Agentic Delivery
Ask these questions during vendor selection meetings:
"Can you show us the permission scope configured for each agent across read, write, approve, delete, and deployment operations?"
"Who approves agent-generated plans, code, test suites, and pull request merges, and where are those sign-offs logged?"
"Which system actions are technically impossible for an agent to execute without manual human intervention?"
"How recently was your team's emergency rollback procedure tested, and who holds recovery authorization?"
"Where are human review gates enforced during multi-agent handoffs between planning, coding, testing, and release stages?"
Require vendors to demonstrate where human approvals occur within their toolchain and confirm that workflows halt when approvals are missing. A checkpoint that can be bypassed is not a safeguard.
Consider how these governance requirements align with your strategy for in-house and outsourced development. Regardless of your delivery model, your organization must maintain clear visibility into architectural decisions and software quality.
Demanding these controls is not an argument against agentic workflows in ai. It is the proper strategy for deploying them responsibly: bounded authority, isolated execution, traceable logs, and human oversight at critical control points.
Speed and Safety Align in Well-Designed Workflows
Well-structured agentic workflows reduce manual effort, shorten feedback loops, and help software teams move efficiently from approved design to reviewed code. Human checkpoints ensure that acceleration remains sustainable.
Without governance, a single flawed assumption propagates from architecture to implementation, test generation, and production release undetected. With proper checkpoints, AI agents handle repetitive technical tasks while accountable human leads retain authority over architecture, permissions, code quality, releases, and recovery.
Require these five contract standards in your next software engagement:
Formal architectural sign-off prior to code generation
Explicit forbidden-actions lists enforced by technical access controls
Mandatory human engineering review of code and test suites before merge
Immutable audit logging and explicit rollback ownership
Verified human review at critical multi-agent handoffs
Smicolon delivers agentic software engineering with embedded client governance: architectural sign-offs, scoped technical permissions, human-approved merges, complete audit logging, and explicit rollback procedures. We help engineering teams achieve delivery speed while maintaining architectural control and product quality.
Preparing a statement of work or evaluating software development partners? Review your delivery requirements with Smicolon and establish the specific control gates your software project requires. Book a Discovery Call.
Product owners who succeed with agentic workflows will establish clear boundaries, enforce human oversight, and maintain ownership of product architecture.
---
# Agentic Workflow Tools: How to Evaluate Them Before Your Team Builds on Top of One
Source: https://smicolon.com/blog/agentic-workflow-tools-how-to-evaluate-them-before-your-team-builds-on-top-of-on
Updated: 2026-08-26T15:33:08.421Z
The demo always works. An agent takes a goal, calls a handful of tools, and returns a finished result in minutes. Nobody in the room asks what happens on run number fifty, when the API times out and t
Agentic Workflow Tools: How to Evaluate Them Before Your Team Builds on Top of One
The demo always works. An agent takes a goal, calls a handful of tools, and returns a finished result in minutes. Nobody in the room asks what happens on run number fifty, when the API times out and two agents edit the same file.
That is the question worth answering before you commit. Most agentic workflow tools look similar in a sales call and behave very differently inside your product, your infrastructure, and your security boundaries.
The wrong choice costs you twice: first in failed runs and validation overhead, then in the rework of ripping out integrations your team already built.
An agentic workflow is a process where AI agents plan, act, evaluate the result, and iterate across multiple tools. It goes further than an assistant that answers prompts and further than robotic process automation that follows fixed rules. If you want the fundamentals first, start with this plain-English guide to agentic workflows.
Why Evaluating Agentic Workflow Tools Got Harder in 2026
The market has shifted from isolated assistants to systems that coordinate real work. Teams no longer compare answer quality alone. They compare how an agentic AI workflow manages Model Context Protocol (MCP) connections, concurrent tasks, execution interfaces, state, and verification. Understanding these shifting technical demands is critical for leaders evaluating AI in 2026 business strategy.
The New Stack's analysis of agentic development trends points to parallel task runners, MCP management, terminal-based agents, and verification as defining parts of that shift. These capabilities matter because agents are now modifying software, calling APIs, inspecting databases, and running tasks in the background.
That raises the stakes on the decision itself. Competitors may already be operationalizing agents, but choosing fast without criteria is the more expensive mistake. A rushed pick can lock your team into weak controls, inconsistent outputs, and integrations that are painful to unwind.
The alternative is to evaluate agentic workflow tools against five production-readiness criteria:
Parallel execution
MCP support and governance
Verification and multi-run consistency
CLI and desktop interface fit
Enterprise controls
The framework is built for teams shipping custom software. It gives CTOs and engineering leads enough depth to run a meaningful pilot, and gives founders and product owners a clear line between architecture decisions and risk, cost, and delivery speed.
Criterion 1: Parallel Execution — Can the Tool Actually Run Work Concurrently?
Parallel execution means running multiple tasks or agent sessions at the same time instead of processing every step in sequence. It matters because production work rarely arrives as one clean prompt.
A development team might have one agent inspect a service, a second draft tests, and a third review documentation. A product operation might process separate customer cases at once while a background agent prepares a report. Done well, this cuts waiting time and uses available compute properly.
That is not the same as opening several chat windows. An engine built for agentic workflows must manage concurrent sessions, queues, shared resources, failures, and dependencies between tasks.
What to test
Pick a workflow with both independent and dependent tasks. Ask the tool to analyze three services concurrently, then combine the findings only after all three finish.
Then break something. Stall one task, fail another, and watch the result. A production-ready tool should never leave the workflow in an ambiguous state.
Ask these questions during the pilot:
Can the tool run several isolated agent sessions without mixing their context?
How does it queue work once concurrency limits are reached?
Can tasks continue in the background after a user closes the interface?
What happens when two agents try to modify the same file or record?
Can the system retry one failed task without rerunning the whole workflow?
Can engineers set limits on runtime, model usage, and resource consumption?
Check how the tool represents dependencies too. If Task C depends on Tasks A and B, your team should see that control flow, not infer it from a sequence of prompts.
Parallelism raises throughput and it also raises the number of things that can go wrong at once. An unreliable agent running one task is a contained problem. The same agent running twenty tasks produces twenty outputs someone has to inspect, reconcile, or repair. Treat parallel execution and verification as a pair.
Criterion 2: MCP Support and Governance — The Standardization Layer You Cannot Skip
Model Context Protocol, or MCP, is a standard way for agents to connect with data sources, APIs, and software tools. In plain terms, it gives an agent one consistent method for discovering and using approved capabilities instead of a custom integration per connection.
That standardization simplifies an agentic AI workflow. Your team exposes a controlled set of operations through MCP servers: read a project record, search documentation, call an internal API.
Support alone does not make those connections safe. Every accessible tool widens what an agent can see and do. An MCP server that queries customer data, edits production records, or triggers deployments deserves the same scrutiny as any other privileged integration.
The security risks around MCP and agentic workflows put permissions and trust boundaries at the center of the evaluation. Do not stop at whether a platform supports MCP. Ask how it governs MCP.
What to evaluate
A credible platform lets your team control which servers each workflow can reach, separates read operations from write operations, and keeps permissions at the smallest practical scope.
Use these questions:
Can administrators approve or block individual MCP servers?
Can permissions differ by user, agent, environment, and workflow?
Can an agent get read access without write access?
Does the platform show which tools an agent called and what data came back?
Can credentials live in a managed secrets system instead of prompts or config files?
Can your team test a server in a sandbox before exposing production systems?
How fast can administrators revoke access during an incident?
For custom software, look closely at how easily you can expose your own APIs without opening them too wide. A convenient connector with unrestricted access carries more risk than a narrow integration that takes an afternoon to configure. Reviewing the lessons learned from MCP in real agentic workflows helps clarify these architectural choices.
Criterion 3: Verification and Multi-Run Consistency — The Difference Between a Demo and a System
Verification is the process of checking whether an agent's output and actions meet defined requirements. It turns "the agent finished" into "the system confirmed the result is acceptable."
This matters because AI output varies between runs. A workflow that succeeds once in a demo can behave differently when the context shifts, an API returns something unusual, or the model takes another path.
Scaling autonomy without verification does not remove work. It relocates work into failure handling, manual validation, and rework. The speed gain evaporates the moment engineers start reconciling inconsistent outputs or repairing broken backend logic.Core Rule: Would you ship code from a developer whose work you never reviewed? Then why ship it from an agent you never verify?
Run the same task more than once
Do not judge ai agentic workflows by their best runs. Give the tool the same realistic task five times under identical conditions, then compare the outputs.
Ask:
How much do the outputs vary across repeated runs?
Does every run satisfy the same acceptance criteria?
Does the agent preserve business rules when its implementation approach changes?
Can the team explain why one run failed and another passed?
Does the workflow degrade safely when a dependency is unavailable?
Multi-run consistency does not mean identical wording or identical code. It means stable outcomes, preserved constraints, and predictable failure handling.
What good verification looks like
Reliable agentic workflows combine several controls:
Output validation: Automated checks confirm required structure, values, tests, or policy conditions.
Explicit control flow: The workflow defines which step follows which condition instead of leaving every decision open-ended.
State management: The system records completed work, current context, pending actions, and recovery points.
Human-in-the-loop checkpoints: People approve sensitive or ambiguous actions before execution continues.
Failure handling: The workflow can retry, escalate, roll back, or stop without hiding the error.
Tools such as Claude Code and Cline can anchor a validation pilot, but name recognition is not evidence. Apply the same consistency, logic, and governance tests to every option. The maturity bar is not whether an agent can write code. It is whether your team can safely understand, test, review, and own what it writes.
When AI increases output faster than your review capacity, the bottleneck has moved rather than disappeared. We examine how teams bridge this operational gap in our guide to the verification gap framework.
Criterion 4: CLI vs. Desktop — Match the Interface to the Work, Not the Hype
A command-line interface, or CLI, lets users drive a tool through terminal commands and scripts. A desktop interface gives them a visual environment for interactive use, review, and supervision.
Neither wins outright. They serve different work modes.
Where CLI tools fit
CLI tools suit headless execution, meaning they run without a graphical interface or constant user attention. Engineers can call them from scripts, schedule them, wire them into CI/CD pipelines, and run several sessions in parallel.
A CLI usually offers finer control over files, commands, environments, and parameters. It also makes repeatable workflows easier to version alongside application code.
Evaluate the CLI with questions like these:
Can it run reliably in containers and CI environments?
Can scripts receive structured output instead of screen text?
Can your team set permissions and resource limits per run?
Can several sessions execute without sharing unintended context?
Does automation follow the same governance rules as interactive sessions?
Where desktop tools fit
Desktop tools suit supervised, judgment-heavy work. A visual interface makes long outputs easier to read, supports interactive corrections, and lets users inspect what an agent plans to do before approving it.
The comparison between desktop and terminal-based agentic work shows why the interface should follow the task. Exploratory analysis and review reward visibility. Repeatable background automation rewards scriptability.
A simple heuristic:
Use CLI-based execution for automated, repeatable, high-volume work.
Use desktop interfaces for supervised, exploratory, or review-heavy work.
Most mature teams need both, which makes the real question: Can your team move between CLI and desktop modes without losing context, permissions, run history, or governance?
Criterion 5: Enterprise Controls — Explicit Control Flow, State, and Human Checkpoints
Enterprise controls define what an agent may do, when it must stop, and how your team reconstructs its actions afterward. They turn open-ended autonomy into a managed operating system for work.
Production adoption depends on far more than model quality. Teams need explicit control flow, durable state, output validation, and configurable human checkpoints.
Start by testing whether the platform can represent your actual approval process. An agent that drafts a database migration can run the tests, but a qualified person should approve the production change. A support agent can prepare a refund, though unusual or high-value cases still need escalation.
Ask vendors and pilot teams:
Can we define exactly where an agent must stop and request approval?
Can approval rules depend on risk, value, environment, or data sensitivity?
Can a reviewer change or reject an action without restarting the workflow?
Does the system preserve state while it waits for a decision?
Can failed runs resume from a safe checkpoint?
Can administrators disable a workflow immediately?
Auditability and observability
Auditability means keeping enough evidence to review what happened. Observability means seeing the workflow's condition and behavior while it runs. Look for complete run histories, tool-call records, approval events, errors, model inputs and outputs, and state changes.
These controls matter most when agents touch production databases, customer information, payment operations, source repositories, and deployment pipelines. Retrofitting permissions and checkpoints later costs far more than evaluating them upfront.
A Practical Agentic Workflow Tools Evaluation Scorecard
Use this scorecard during a time-boxed pilot. Score each category against a real workflow, not a prepared vendor demo.
Criterion | Questions to test in the pilot | Disqualifying red flags
Parallel execution | Can sessions run concurrently without context leakage? How are queues, dependencies, and retries handled? What happens during resource contention? | Shared context appears in the wrong run; one failure corrupts the full workflow; concurrent modifications have no conflict handling.
MCP governance | Can administrators approve servers and scope permissions? Are read and write access separate? Can every tool call be audited? | Unrestricted server access; credentials in prompts; no fast revocation; MCP calls missing from run history.
Verification & consistency | Does the same task pass acceptance criteria across repeated runs? Can outputs be validated automatically? Can your team explain divergent results? | Success depends on manual inspection; failed validation does not stop execution; the tool favors completion speed over correctness.
Interface fit | Can CLI and desktop users follow the same policies? Can context and run history move between modes? Does the CLI support structured output and headless execution? | Automation bypasses desktop controls; governance differs by interface; reviewers cannot inspect terminal-initiated work.
Enterprise controls | Can you configure approvals, escalation paths, checkpoints, and recovery? Can investigators reconstruct each action? | No durable state; incomplete logs; no emergency stop; sensitive actions execute without configurable approval.
Running a focused pilot
Choose one workflow that resembles production work: real constraints, isolated data, non-production permissions. Run the same task several times and measure whether the outcomes meet the same acceptance criteria. Then introduce a failed API call, an unavailable MCP server, a conflicting file change, and a rejected approval.
Review the results with engineering, security, product, and operations together. If agent-generated code is already in your product, running an AI code quality audit will show whether verification and ownership gaps are compounding under the surface.
Choosing Well Is Half the Battle — Implementing Well Is the Other Half
Adopting agentic workflow tools well is an architecture and governance decision, not a purchase. The platform has to fit your systems, permissions, delivery process, and tolerance for operational risk.
Test production readiness across all five criteria. Confirm that parallel execution does not outrun verification. Treat MCP as a governed integration layer. Prove multi-run consistency before rewarding speed. Match CLI and desktop interfaces to the work. Require explicit control flow, durable state, validation, and human checkpoints wherever consequences justify them.
Smicolon helps teams architect, integrate, and govern agentic workflows inside scalable custom software: workflow architecture, verification pipelines, secure MCP integration, human approval paths, and connections to your core infrastructure.
If you are comparing tools or deciding how agents fit into a custom software roadmap, bring us the shortlist. Book a discovery call to talk through your agent tooling evaluation and leave with a clearer view of what to pilot first.
---
# UX Design for Small Business: A Conversion-First Playbook (Not a Redesign Wishlist)
Source: https://smicolon.com/blog/ux-design-for-small-business-a-conversion-first-playbook-not-a-redesign-wishlist
Updated: 2026-08-26T15:33:16.562Z
**Meta description:** UX design for small business should boost conversions, reduce wasted ad spend, and build user trust. Use this playbook to fix mobile and checkout friction.
UX Design for Small Business: A Conversion-First Playbook (Not a Redesign Wishlist)
Meta description: UX design for small business should boost conversions, reduce wasted ad spend, and build user trust. Use this playbook to fix mobile and checkout friction.Key Takeaway for SMB Leaders: UX design for small business (or UX design for SMB) is the practice of identifying and eliminating digital friction points that prevent visitors from converting. Rather than launching expensive site redesigns, small business UX design focuses on incremental, high-impact improvements to mobile journeys, forms, trust signals, and checkout processes.
Why UX Design for Small Business Is a Revenue Problem, Not a Design Problem
When did you last try to buy from your own site on your phone, as a stranger, on slow data? That two-minute test — not a brand-new homepage — is where UX design for small business starts paying for itself. Better user experience turns more of the visitors you already pay for into paying customers, without raising your ad budget.
UX stands for user experience: what happens when someone tries to find information, compare options, contact you, or purchase a product. The core question is not whether your site looks modern. It is whether visitors hesitate, get confused, or leave before taking the next step.
The ROI of UX Design for SMB Growth
The financial impact of effective small business UX design is measurable:
UX Metric / Factor | Impact / Finding | Source
ROI per $1 Spent | Every $1 invested in UX returns up to $100 (10,000% ROI) | Forrester Research
Conversion Lift | Eliminating user friction can increase conversion rates by up to 400% | Research compiled by Maze
Cart Abandonment Rate | Users are 38% more likely to abandon a site they find difficult | Nielsen Norman Group
Checkout Optimization | Checkout usability fixes raise conversion rates by 35.26% | Baymard Institute
Revenue Retention | Continuous UX testing improves retention by up to 10.8% over 3 years | UXCam
These numbers show why removing genuine user obstacles belongs on the same priority list as advertising, sales, and product development. Friction directly taxes your marketing performance. Every dollar spent sending visitors to a confusing page is partially wasted. You paid for the visit; the experience leaked the revenue.
This playbook provides a practical framework for growth-phase companies without an in-house design team. It is not a speculative redesign wishlist. It executes in five actionable steps:
Audit friction in your core conversion journeys.
Make mobile-first decisions for small screens.
Add trust signals at each decision point.
Create a lean design system for UI consistency.
Measure, test, and iterate based on real user behavior.
Results must come before aesthetics. Always start with the user interactions closest to revenue.
The Redesign Trap: Why "Start Over" Is Usually the Wrong Answer
Fixing specific conversion bottlenecks usually lifts revenue faster, and with far less risk, than replacing your entire website.
Full site redesigns are expensive, time-consuming, and risky. They take months, involve dozens of subjective opinions, and often swap known user problems for unfamiliar ones. Crucially, full redesigns can erase what you have already learned about which pages, value propositions, and messages resonate with your market.
Think of a full redesign as moving house because the kitchen faucet leaks. Fix the faucet first. Move only when the underlying structure no longer supports your business operations.
Redesign only if technical debt blocks growth
A full rebuild is justified only when:
Your underlying platform cannot support essential integrations or features.
Severe technical debt creates slow load speeds across the core architecture.
The information architecture — how content and pages are structured — is beyond repair.
Mobile usability is broken across every page, rather than isolated templates.
Non-technical team members cannot update essential content without developer intervention.
Your business model or target audience has shifted so drastically that existing user flows are obsolete.
If none of these critical blockers apply, optimize your existing setup. Continuous iteration protects search rankings and user familiarity. UX research compiled by UXCam demonstrates that ongoing UX testing improves three-year revenue retention by up to 10.8% because every test yields actionable data.
The hidden costs of a redesign are equally substantial. Replacing live pages can disrupt organic search visibility, break established paths for returning clients, and pause your growth campaigns for months. None of these hidden risks appear in a standard agency proposal.
When technical limits do force a comprehensive build, clearly specify business objectives before requesting vendor quotes. Utilizing a structured product brief that prevents scope creep helps development partners price exact business problems rather than open-ended wishlists.
Step 1: Run a Friction Audit — the 90-Minute Version
Ninety minutes of disciplined evaluation can surface major conversion leaks you can fix immediately, without hiring an external design team.
Friction is any element that increases cognitive effort, delays user action, or lowers trust. A vague button label, slow page loading, excessive form fields, hidden pricing, or forced account creation all create user friction.
Set aside 90 minutes. Use a smartphone on cellular data rather than your office Wi-Fi, and navigate your site as an unfamiliar first-time visitor.
Minutes 0–15: Choose your three money journeys
Identify the three digital paths most critical to immediate business revenue:
Service Evaluation: Find a service page, review capabilities, and submit a inquiry.
E-Commerce Purchase: Find a product, add to cart, and complete checkout.
Lead Generation: Land on a campaign landing page, evaluate the offer, and request a quote.
Do not attempt to audit every minor page. Focus exclusively on user flows that generate revenue.
Minutes 15–60: Complete each journey on a mobile device
Test without saved passwords or autofill shortcuts. For every step in the user flow, ask:
Does the initial view immediately clarify what the business offers?
Can visitors locate target services or products without guessing navigation terms?
Do pages load quickly without jarring layout shifts?
Is there a single, prominent call-to-action (CTA) on each page?
Do button labels clearly communicate what happens upon clicking?
Is pricing, or a clear explanation of custom quoting, readily visible?
Does the conversion form request only information essential for the next step?
Are validation errors highlighted in plain language?
Does checkout display all taxes and shipping costs prior to the final payment step?
Can visitors check out without mandatory account registration?
Is post-submission confirmation clear regarding next steps?
Record every point of resistance with simple screenshots. You do not need complex software to identify a frustrating form or confusing navigation menu.
Minutes 60–75: Reduce cognitive load
Cognitive load refers to the mental effort required to process information and make a decision. Every competing visual element, redundant form field, modal pop-up, or unclear label consumes visitor attention.
Eliminate unnecessary mental effort by applying these rules:
Remove competing secondary buttons near primary CTAs.
Replace vague button text like "Submit" or "Continue" with clear action verbs like "Get Your Free Quote" or "Complete Purchase".
Group related form fields and content logically.
Break long multi-step forms into manageable stages.
Delete form fields that are not immediately operational.
Display all fees and requirements before the final conversion step.
Make primary conversion paths visually distinct.
Minutes 75–90: Rank fixes by distance from revenue
For transactional and e-commerce websites, checkout optimization yields the fastest financial return. Baymard Institute's research shows that checkout usability improvements alone can raise conversion rates by 35.26%.
Prioritize friction fixes in this exact sequence:
Checkout & Payment Flows (Direct payment blockers)
Contact, Quote & Booking Forms (Lead capture leaks)
Product & Service Evaluation Pages (Value communication)
Site Search & Navigation Architecture (Findability obstacles)
Homepage & Top-of-Funnel Content (Initial awareness)
Fixing issues closest to conversion yields immediate revenue impact. If ten users reach checkout and four drop out due to form errors, redesigning the homepage headline will not stop the revenue leak.
Step 2: Make Mobile-First Decisions, Not Mobile Afterthoughts
A mobile-first UX allows potential clients to act instantly rather than deferring action until they return to a desktop computer — where they frequently forget.
Many small business websites are designed on wide desktop displays and superficially checked on mobile screens afterward. Effective ux design for smb flips this approach: optimize user decisions for mobile devices first, then scale the interface up for desktop displays.
Core Mobile Usability Checklist
Touch Target Sizing: Ensure all buttons and interactive links are easily clickable with a thumb without accidental taps.
Sticky Call-To-Action: Keep primary conversion buttons accessible during scrolling on long-form content.
Streamlined Navigation: Ensure hamburger menus cleanly present main service categories, pricing, and contact options.
Click-to-Call Functionality: Enable single-tap phone dialing for local and direct inquiries.
Readable Typography: Maintain comfortable line spacing and font sizes to eliminate pinch-to-zoom requirements.
Minimal Visual Interruption: Prevent aggressive pop-ups, cookie banners, and chat widgets from obscuring primary conversion actions.
Optimize Mobile Forms for High Conversion
Forms represent high-friction steps on mobile devices. Streamline form completion with these standard patterns:
Enable auto-complete attributes across contact fields.
Trigger appropriate virtual keypads automatically (e.g., numeric keypads for phone numbers, email keypads for @ symbols).
Display clear inline validation errors as fields are completed rather than upon form submission.
Maintain strong color contrast, explicit field labels, and visible focus states for full web accessibility.
The Mobile UX Benchmark: Can a first-time mobile visitor complete your primary conversion action in under 60 seconds?
Time your mobile conversion flow today. If it takes longer than 60 seconds, identify where time is lost and streamline those steps.
Step 3: Build Trust Signals into Every Decision Point
Explicit social proof and transparent business policies lower perceived risk, especially for prospective clients who are unfamiliar with your brand.
Enterprise brands rely on built-in market recognition. Small businesses must establish credibility step by step throughout the user journey. Trust is a core structural element of effective small business ux design, not a decorative badge placed in the website footer.
A trust signal is any contextual element that verifies your business legitimacy, offer quality, or transaction safety: authentic customer reviews, clear pricing models, published policies, recognized payment processors, and direct contact details.
Map Trust Signals to Specific User Doubts
Buyer Journey Stage | Prospective Client Concern | High-Impact Trust Signal
Initial Impression | "Is this a legitimate business?" | Verified address, team photos, recognized client logos
Evaluation | "Can this solution solve my exact issue?" | Detailed case studies, industry-specific testimonials
Pricing Review | "Are there hidden charges or unexpected fees?" | Clear pricing breakdowns, explicit custom quote explanations
Lead Form Entry | "Will my information be spammed?" | Clear privacy notice, explicit description of follow-up steps
Checkout | "What if the product fails to meet expectations?" | Plain-language return, exchange, and refund policies
Payment Entry | "Is my credit card data secure?" | Recognized payment gateway badges, SSL security verification
Avoid generic or unverified trust elements. A vague quote from an anonymous source alongside a stock photo reduces user trust. Always use authentic client outcomes and verified customer statements.
Actionable Trust Checklist
Feature genuine client names, job titles, and photos (with client approval).
Place specific customer testimonials alongside the relevant service or product option.
Position security and policy assurances adjacent to form submission and payment buttons.
Ensure return, warranty, or cancellation terms are visible prior to transaction completion.
Provide direct access to customer support options across high-intent pages.
Trust is established by proactively eliminating unanswered user questions at every conversion step.
Step 4: Use a Lean Design System for Small Business UX Design
A lean design system drastically reduces the time and expense of developing future web pages while providing users with a consistent interface.
A design system is a centralized set of standardized UI rules governing how a website looks and functions. For small businesses, this system fits onto a single reference guide. You do not require complex enterprise documentation or hundreds of component variants.
Core Components of a Lean Design System
Typography: Maximum of two typefaces — one for structural headings and one for body copy.
Color Palette: 3 to 5 defined colors assigned specific jobs (e.g., Primary Action, Secondary Accent, Neutral Background, Text, Error Red).
Button Hierarchy: Two distinct button designs (Primary Call-to-Action vs. Secondary Action) with firm rules on placement.
Form Layouts: Uniform input spacing, field heights, error indicators, and submission states.
Content Modules: Standardized containers for service features, pricing cards, and customer reviews.
Design consistency reduces visitor cognitive load. When primary action buttons utilize consistent styling across every page, visitors do not need to re-learn site navigation.
A lean system also controls ongoing development costs. Without standardized rules, every new marketing landing page becomes an expensive custom project. Standardizing interface components allows team members to build high-converting landing pages rapidly.
When interface updates require underlying custom engineering, ensure technical execution avoids technical debt. Understanding the real cost of bad software highlights how short-sighted design and development shortcuts increase ongoing maintenance costs over time.
Step 5: Measure, Test, Repeat — UX Design for SMB Growth
Regular, data-informed UX refinements lower customer acquisition costs (CAC) by maximizing the revenue generated from existing website traffic.
You do not require expensive analytics tools to begin optimization. A streamlined analytics setup must track three fundamental metrics:
Conversion Rate: What percentage of total visitors complete target actions (form submissions, calls, or purchases)?
Drop-Off Points: At which exact step in the conversion funnel do users leave?
Usability Bottlenecks: What technical errors, form fields, or messaging gaps cause user drop-off?
Analytics metrics indicate where users leave; qualitative feedback explains why. Use recorded user sessions, customer support queries, form error tracking, and direct feedback to identify specific usability defects.
Establish a Sustainable UX Refinement Cadence
Executing one high-impact UX test each month yields better long-term performance than launching erratic site revamps every few years.
Prioritize optimizations using a simple formula:
$$\text{Priority} = \text{High Traffic Volume} \times \text{Proximity to Revenue} \times \text{Ease of Implementation}$$
Streamlining a high-traffic lead form delivers significantly higher financial returns than rewriting copy on an obscure company history page. Maintain a simple optimization log recording identified usability issues, proposed changes, target conversion metrics, and actual results.
Test single variables sequentially to accurately measure performance impact. Small monthly improvements compound over time, providing a scalable foundation for business growth.
Where a Technology Partner Fits — and Your Next Step
This 5-step framework gives SMB leaders total control over UX investments: audit friction, optimize for mobile, build visible trust, institute a lean design system, and measure results. Always focus on measurable conversion bottlenecks rather than subjective aesthetic preferences.
Most initial optimizations can be performed internally: auditing primary user flows, removing redundant form fields, clarifying button copy, publishing policies, and timing mobile conversions.
However, advanced optimizations often require software adjustments, custom checkout integrations, analytics event tracking, accessibility compliance, or custom component development. When implementation exceeds internal team bandwidth or technical capabilities, an experienced technology partner prevents temporary fixes from creating permanent technical debt.
Choosing the right execution model depends on your growth stage and technical needs. Reviewing an in-house versus outsourced framework can help clarify whether external engineering support matches your current operations.
Smicolon operates as a dedicated technology partner for growing companies requiring expert software engineering and UX support. Our focus is not selling complete site redesigns, but systematically identifying and fixing friction points that waste marketing spend, erode user trust, or limit digital conversions.
Book a discovery call with Smicolon. We will analyze your core mobile conversion flow, highlight existing user friction points, and provide clear recommendations on which issues you can fix internally and where expert technical support can accelerate results.
---
# The Real Cost of Poor Software Quality: What Bad Code Costs Your Business
Source: https://smicolon.com/blog/cost-of-poor-software-quality
Updated: 2026-08-26T15:33:24.594Z
The Real Cost of Poor Software Quality: The Invoice Your Vendor Never Sent You
The cost of poor software quality is quietly one of the most destructive forces in modern business — and most companies only discover it after they've already paid. CISQ estimated the total cost of poor software quality in the U.S. at $2.41 trillion in 2022, up from $1.56 trillion just four years earlier. That number is not an abstraction. It is the aggregate of situations exactly like yours.
The Moment a New Developer Opened Your Codebase
You remember the exact conversation. A new developer — someone you brought in to extend what your last vendor built — spent two days reading the code before coming back with that look. Not panic. Worse than panic. The measured, almost apologetic expression of someone about to deliver news they know will cost you money.
This is unmaintainable. Or some version of it: We'd be faster starting over. There are no tests. The database logic is scattered everywhere. I can't tell what's intentional and what's held together with string.
What followed was a specific kind of financial hemorrhage that never shows up cleanly in a post-mortem. Sprint velocity collapsed because your new team was reverse-engineering instead of building. The feature that was supposed to hit market in Q2 slipped to Q4 — and by then, a competitor had moved in. You sat across from your board, or your investors, or your co-founder, and tried to explain why work you had already paid for needed to be paid for again. That conversation has a cost that appears on no invoice.
That original contract — the milestones your vendor hit, the final payment you made — was not the price of the engagement. It was the down payment.
What happened to you was not a vendor selection mistake. It was not a project management failure or a communication breakdown. It was the predictable output of a business model designed to optimize for delivery at the expense of everything that comes after delivery. That model has a mechanism. That mechanism has a name. And once you can see it clearly, you will never evaluate a software vendor the same way again.
Why the Delivery Model Itself Is the Problem
Most software agencies are not in the business of building you a software asset. They are in the business of reaching the end of a contract. Those two things sound similar. They are economically opposed.
Under a fixed-bid contract, every hour spent on documentation, test coverage, and code review is an hour that reduces margin. The rational incentive is to ship code that looks complete at handoff — that passes the functional acceptance criteria in the SOW — not code that performs under load, transfers cleanly to a new team, or remains comprehensible six months after the developers who wrote it have moved on. Your long-term carrying costs were never in their model. They were always in yours.
Time-and-materials contracts solve the margin problem and create a different one. When the incentive is hours, the incentive is hours. Longer timelines, more complex architectures than the problem requires, dependency structures that guarantee your return as a client — these are not conspiracy-level behaviors. They are rational responses to the economic structure of the engagement.
Both models share one feature: the moment the vendor offboards, their accountability ends. Everything that accumulates after that — the technical debt, the undocumented decisions, the security vulnerabilities introduced by a junior developer who shipped without review — lands entirely on you.
This is where the bus factor stops being an engineering metric and becomes a business one. When your vendor owns the architecture decisions, holds the undocumented logic of how your system actually works, and carries the tribal knowledge of why things were built the way they were — your codebase has a bus factor of one. One team. One relationship. One point of catastrophic failure. That dependency is not an oversight. For a vendor whose revenue model ends at delivery, it is a feature. A client who cannot function without them is a client who calls back.
Ask yourself honestly: Did your last vendor deliver a system architecture document alongside the code? Did they provide test coverage reports at each sprint review? Did they conduct a formal knowledge transfer session before offboarding — one with defined completion criteria and sign-off?
Every 'no' is a line item on the hidden invoice. The reason you couldn't evaluate these risks before signing is not that you failed to ask the right questions. It's that the industry has spent decades making sure you didn't know which questions those were.
What 'Unmaintainable Code' Actually Costs — in Dollar Terms
Let's be specific, because 'technical debt' sounds like an engineering complaint until you run the numbers.
Cyclomatic complexity measures how many independent execution paths run through a piece of code. High complexity doesn't just make code harder to read — it makes every modification exponentially more expensive. Each new developer who touches a high-complexity codebase spends more time understanding it, more time testing their changes safely, and more time diagnosing the failures when they get it wrong. That time is billed to you. It compounds with every sprint. And it never surfaces on a single line item — it hides inside velocity numbers that keep declining without an obvious cause.
IBM's research on defect cost amplification is unambiguous: fixing a bug in production costs up to 100x more than catching it during requirements, and 15x more than catching it during design. If your last vendor shipped without a defined test coverage threshold — without a code review cadence that caught defects before they merged — then every bug currently living in your production system carries that multiplier. You have already paid some of it. You are paying the rest right now.
Here is the calculation you should run. A 2023 Stripe and Harris Poll study found that developers spend 33% of their time dealing with bad code, technical debt, and legacy systems — averaging 17.3 hours per week per developer. If you have hired a senior engineer at $180,000 annually to inherit a codebase your last vendor left unmaintained, you are paying approximately $59,400 per year for that engineer to fight someone else's shortcuts before they can build anything new. That is not salary. It is a maintenance tax your vendor never disclosed.
McKinsey's research found that the average enterprise carries technical debt costs equivalent to 20–40% of the total value of its technology estate. Run that through your own numbers: estimate what a competent team would charge to rebuild your current system from scratch. Multiply that number by 0.20 to 0.40. That range is a conservative floor for the liability you are currently carrying — one that has no line item anywhere in your financials.
The number that matters: How many developer hours last quarter went toward rework, patching, or debugging code your last vendor delivered? Pull the actual figure. Multiply it by your fully-loaded engineering cost. Whatever that number is, it represents a partial payment on the hidden invoice — and it will keep accruing, at compound interest, until the underlying debt is resolved.
The Six Structural Failures Your Last Vendor Probably Committed
These are not edge cases. They are the industry standard for agencies operating under the delivery incentive model. Read each one and ask whether it matches what you received.
1. No Meaningful Test Coverage
Shipping code without defined test coverage thresholds is not a junior oversight — it is a deliberate speed optimization that transfers all future defect costs to you. The production standard for quality software development is 80%+ unit test coverage, with documented coverage reports delivered at each sprint. Ask your last vendor what percentage they delivered. If they cannot produce the report, that is your answer.
2. No CI/CD Pipeline Integrity
A codebase without a documented, automated continuous integration and deployment pipeline means every future deployment is a manual, high-risk event. The Knight Capital Group collapse in 2012 is the defining case study: a single deployment error caused the firm to lose $440 million in 45 minutes, ultimately forcing its acquisition. The root cause was legacy code reactivated unintentionally during a manual deployment — a direct consequence of poor code management and the absence of automated quality gates. Knight Capital was not a naive startup. They were a sophisticated trading firm undone by the same category of failure your last vendor left in your system.
3. No Code Review Cadence
Code written and merged without structured peer review accumulates architectural drift. Components that work in isolation begin degrading system coherence over time, making future changes progressively more expensive and more likely to introduce new failures. The absence of code review is not just a quality issue — it is a compounding cost that grows as the codebase scales.
4. No Documentation Standard
Undocumented code is a time-locked liability. The moment the developers who wrote it disengage, the institutional knowledge evaporates. What remains is a system your next team must reverse-engineer at your expense — a hidden onboarding tax that was never disclosed in the original proposal. Architecture decision records, dependency maps, environment configuration guides: these are not optional deliverables. They are the difference between owning a software asset and renting access to your vendor's memory.
5. No Defined Ownership Transfer
If your engagement ended without a formal handoff that included architecture rationale, deployment runbooks, and environment configurations — with explicit sign-off criteria on both sides — you did not receive a software asset. You received a black box with a dependency on the team that built it. That dependency is the vendor's leverage, not your resource.
6. No Performance Benchmarking Before Handoff
Functional tests confirm that code does what it's supposed to do under controlled conditions. They do not confirm that it holds under real user load. If your vendor never ran load testing against defined throughput requirements before delivery, they shipped you a product untested for the conditions that actually matter. You discovered the failure in production, in front of your customers — because that was the first time the system encountered the environment it was built for.
If four or more of those match your last engagement, you are not reading a worst-case scenario. You are reading a description of standard practice in an industry where delivery incentives consistently override quality incentives.
How to Evaluate Your Next Vendor Before They Cost You the Same
The evaluation conversation is where the hidden invoice gets written or gets blocked. Most founders treat it as a capability assessment — can they build what we need? The more useful frame is a risk audit: what will this cost me after they leave?
Reframe vendor evaluation as capital protection, not vendor selection. You are not asking who can build this. You are asking who will hand you a software asset with a documented, transferable, measurable quality standard — and who will put that standard in the contract before the first sprint begins. This is how you protect your custom software ROI from the first conversation, not after the damage is done.
The following questions create immediate signal in a vendor sales conversation. A quality vendor will answer with specificity. A vendor optimizing for delivery will answer with reassurances.
Questions That Separate Quality Vendors from Liability Generators
What is your minimum acceptable unit test coverage threshold for production code, and how do you report it to clients during a sprint?
How do you define 'done' at the sprint level — specifically, what artifacts does a completed sprint produce beyond the feature itself?
Walk me through your knowledge transfer process at engagement end. What does the handoff package include, and how do you define completion?
Can you share an example of the architecture documentation and deployment runbooks you've delivered to a prior client?
What automated quality gates do you use in your CI/CD pipeline, and what happens to a deployment that fails them?
That last question is particularly diagnostic. A vendor with real pipeline integrity will describe a deployment that gets blocked. A vendor without it will describe a process that alerts someone.
On documentation: ask every prospective vendor to provide a redacted example of the architecture documentation, sprint review reports, and deployment runbooks they have delivered to a prior engagement. Quality software development practices produce these artifacts systematically. Vendors who build liabilities do not have them because their process never required them.
Use DORA benchmarks as a buyer's tool, not just an internal engineering metric. High-performing engineering teams deploy 973x more frequently and achieve 3x lower change failure rates than low performers. Ask your next vendor where their delivery practices place them against DORA's four key metrics: deployment frequency, lead time for changes, change failure rate, and time to restore service. The specificity of their answer tells you more than their portfolio ever will.
Red Flags to Watch for in Every Vendor Conversation
Vague answers about testing methodology ('we take quality seriously' with no numbers)
No fixed documentation deliverables specified in the contract
Knowledge transfer described as 'ongoing' with no defined endpoint or sign-off criteria
Code review described as 'informal' or 'collaborative' without a named cadence
No quality metrics in the statement of work — no coverage thresholds, no complexity limits, no performance benchmarks
You now recognize these patterns because you have earned that pattern recognition. The question is whether you use it.
What a Software Asset Actually Looks Like
A codebase is an asset when a competent engineer who has never seen it can understand its structure, run its test suite, deploy it safely, and extend it — within a defined and reasonable onboarding window. That is the functional definition. Everything else is a liability masquerading as an asset on your balance sheet.
Asset-grade code — the kind that delivers real custom software ROI — has measurable indicators, not subjective ones:
Test coverage above 80% with documented coverage reports at each sprint milestone
A CI/CD pipeline with defined quality gates that block deployment on failure — not flag it, block it
Cyclomatic complexity scores within defined thresholds per module, reviewed as part of the code review cadence
An architecture decision record that captures not just what was built but why — the tradeoffs considered, the alternatives rejected
A bus factor above one for every critical system component — meaning at least two people on your side can understand and modify each part of your system safely
These are not engineering preferences. They are business performance variables. The practices that define quality software development — automated testing, continuous deployment, structured peer review — are precisely the practices that DORA research correlates with 973x higher deployment frequency and 3x lower change failure rates. Your software quality standard is a direct determinant of how fast you can move when the market opens — or when a competitor moves first.
Gartner's research found that 17% of large-scale IT projects fail severely enough to threaten the organization's existence. The differentiating factor in those failures is almost never a bad idea or a bad market. It is unmeasured, undocumented, untested code that cracked at the moment of maximum business pressure — at scale, during a critical launch, at the worst possible time to discover that what you were sold as an asset was a liability from the start.
The diagnostic question that matters most: If your lead engineer left tomorrow, how long would it take a replacement to understand your system architecture, run a successful deployment, and safely ship a new feature? If the honest answer is months rather than days, that gap is your current technical liability — expressed in time, and compounding every week that nothing changes.
How Semicolon Builds Assets, Not Liabilities
Every process commitment Semicolon makes exists because a specific hidden invoice line item has a named, structural cause. This is not a service package. It is the contractual elimination of the risks this article has been naming.
Here is the direct correspondence between the six structural failures and how we address each one:
Against no test coverage: Minimum test coverage thresholds are written into the SOW before the first sprint begins, with coverage reports delivered at every sprint milestone — not on request, as a standard artifact.
Against no CI/CD integrity: Automated deployment pipeline with documented quality gates. Deployments that fail quality checks do not proceed. That is a contractual rule, not a recommendation.
Against no code review cadence: Mandatory peer review with named reviewers before any merge to main. Architectural changes require a second review. This is scheduled, not informal.
Against no documentation standard: Architecture documentation updated at each sprint milestone. Dependency maps, environment configurations, and deployment runbooks delivered as standard sprint artifacts.
Against no ownership transfer: Formal knowledge transfer with defined completion criteria and sign-off from your team before the engagement closes. Not 'ongoing support.' A discrete, documented event.
Against no performance benchmarking: Load testing against agreed throughput requirements before handoff. Benchmarks are set at the start of the engagement, not discovered at the end.
Every sprint Semicolon delivers produces artifacts: coverage reports, review logs, architecture updates. These are not internal documents. They are your evidence — real-time visibility into what you are building, and documentation you can present to your board, your investors, or the next engineering hire who needs to understand what they are inheriting.
The reason you could not see the prior failures coming was not a lack of judgment. It was a lack of a standard against which to measure what you were being sold. Semicolon's process is that standard, made explicit and contractual — so the next engagement does not require you to trust a vendor's reputation when you can verify their practice.
What your last vendor took from you was not just money and time. It was the confidence that comes from knowing exactly what you own. The structural purpose of this process is to hand that back — in the form of a codebase you can read about, transfer, scale, and defend to anyone who asks.
What to Do in the Next 30 Days — Before the Compounding Gets Worse
Technical debt does not pause while you evaluate options. Every sprint your current team runs on an unmaintained foundation adds new complexity on top of existing fragility. McKinsey's finding that unresolved technical debt consumes 10–20% of a development team's capacity means every month of delay carries a calculable cost: take your fully-loaded engineering spend, apply 15% as a conservative debt tax, and multiply by the months you expect to wait. That number is not theoretical.
Here is a concrete 30-day sequence:
Weeks 1–2: Commission a third-party codebase audit. Not an internal assessment — an external one, from a team with no stake in the outcome, against documented quality benchmarks. The goal is a written baseline: current test coverage, cyclomatic complexity scores, documentation gaps, CI/CD pipeline status, and a conservative technical debt estimate in dollar terms. You cannot manage a liability you have not measured.
Weeks 2–3: Apply the evaluation framework to every active vendor conversation. Use the questions from this article. Ask for process documentation examples. Run the red flag checklist. The difference between vendors who answer with specifics and vendors who answer with reassurances will be immediate and unmistakable.
Weeks 3–4: Request a formal architecture review before committing to any new development engagement. This is a technical conversation, not a sales one — and the quality of that conversation is itself a data point about the partner you are evaluating.
One additional risk deserves direct mention: IBM's Cost of a Data Breach Report 2023 found the average breach now costs $4.45 million, with insecure coding practices among the leading root causes. A codebase inherited from a vendor who skipped security review is not just a performance liability. It is a potential regulatory and reputational event — the kind that generates a very different board conversation than the one you have already had.
If the analysis in this article matched your experience closely enough to be uncomfortable, that is not coincidence. It is pattern recognition — the specific, transferable kind that comes from having lived through the failure once and now having the vocabulary to name what actually happened.
You did not make a naive mistake. You operated in a market structurally designed to obscure the real cost of poor software quality — one that buried the hidden invoice in the gap between delivery and the moment things broke. You now have the benchmarks, the red flags, the evaluation tools, and the financial framework to make the next decision differently.
The next contract you sign should reflect exactly that. Make sure it does.
Frequently Asked Questions
How much does technical debt actually cost a business?
McKinsey research estimates the average enterprise carries technical debt costs equal to 20–40% of the total value of its entire technology estate. A 2023 Stripe and Harris Poll study found developers spend 33% of their time — roughly 17.3 hours per week — dealing with bad code and legacy systems. For a single senior engineer earning $180,000 annually, that translates to approximately $59,400 per year in lost productive capacity before they write a single line of new code.
What is the cost of poor software quality in the U.S.?
CISQ (the Consortium for Information and Software Quality) estimated the total cost of poor software quality in the U.S. at $2.41 trillion in 2022, up from $1.56 trillion in 2018. This figure encompasses developer hours lost to rework, customer churn from outages, missed market windows, and the compounding cost of inherited technical debt across organizations of all sizes.
How do I evaluate a software vendor before signing a contract?
Treat vendor evaluation as a risk audit rather than a capability assessment. Ask for specific test coverage thresholds, documented CI/CD pipeline quality gates, examples of architecture documentation from prior clients, and a defined knowledge transfer process with explicit sign-off criteria. Request DORA metric benchmarks — deployment frequency, change failure rate, lead time, and mean time to restore. Vendors who answer these questions with specifics are practicing quality software development. Vendors who respond with reassurances are not.
What is a healthy test coverage threshold for production code?
The production standard for maintainable, asset-grade code is 80% or higher unit test coverage, with coverage reports delivered as a standard artifact at each sprint milestone — not on request. Coverage below this threshold significantly increases the cost of future modifications and the likelihood of production defects that carry IBM's documented 100x cost multiplier to fix versus catching them at the requirements stage.
What should a proper software handoff include?
A complete ownership transfer should include: architecture decision records explaining what was built and why, dependency maps, environment configuration guides, deployment runbooks, CI/CD pipeline documentation, load testing results against agreed throughput benchmarks, and test coverage reports. The handoff should be a discrete, documented event with explicit sign-off criteria from both parties — not described as 'ongoing support' with no defined endpoint.
How do I know if my current codebase is a liability?
The fastest diagnostic: ask how long it would take a replacement engineer who has never seen your system to understand the architecture, complete a successful deployment, and safely ship a new feature. If the honest answer is months rather than days, your codebase is a liability. A third-party codebase audit — assessing test coverage, cyclomatic complexity, documentation completeness, and CI/CD pipeline status — will give you a written baseline and a dollar-denominated estimate of your current technical debt.
---
# MVP to Scale-Up: How to Build Scalable Tech Infrastructure That Grows With Your Startup
Source: https://smicolon.com/blog/mvp-to-scale-up-scalable-tech-infrastructure-for-startups
Updated: 2026-08-26T15:33:32.136Z
Building scalable tech infrastructure is one of the most critical — and most overlooked — challenges when transitioning from MVP to scale-up. If your startup has found product-market fit but your architecture was built to launch rather than to last, this guide maps the specific risks you are carrying, what they cost at Series A, and how to close the gap before your growth window does.
The Thing Nobody Tells You After You Find Product-Market Fit
You have users. Real ones, paying ones — people who complain when something breaks because they actually depend on it. Investors are circling. Your metrics are moving in the right direction.
And underneath all of it, there is something quiet and persistent. A dread you have not quite been able to name.
Here is what it actually is: the codebase your first development team shipped in a sprint to hit a launch deadline is now the infrastructure your Series A story runs on.
That is not an accusation. The speed was necessary. Proving demand before investing in scalable software architecture was the only rational call — and it worked, which is why you are here. But what got you here has a shelf life, and you are approaching it. Decisions made twelve to twenty-four months ago under entirely different constraints are now being asked to carry weight they were never designed for.
What is at risk is not some abstract notion of scalability. It is the funding round you are twelve months from entering. It is the growth window that opened when you hit product-market fit — and will not stay open indefinitely. It is the customer trust you have spent months building, which can be destroyed in an afternoon if your core feature goes down at exactly the wrong moment.
This is not a technical brief. Think of it as a diagnostic — a way to translate the vague anxiety you are already carrying into a specific, named inventory of decisions. By the end, you will know whether your infrastructure is a silent passenger or a ticking liability. Those are two very different problems. Only one of them can be solved by ignoring it.
Your MVP Was Optimized for the Right Thing — Just Not for Scalable Growth
Shipping fast, keeping costs low, proving the concept before over-engineering it — that was not a mistake. It was exactly right for the stage you were in. Anyone who tells you otherwise has not actually built anything under real pressure with real constraints.
But there is a specific trap that catches founders at this stage, and it is worth naming directly: the closer your team was to building it, the harder it is to see it clearly. When you have watched something take shape over months, when you have made tradeoffs and solved problems and shipped through crises, the result feels like evidence of sound engineering. Effort and quality are not the same thing — but they feel the same to the people who did the work.
The phase shift that is now underway changes the governing variables entirely. Speed, simplicity, and minimal overhead got you here. What matters now is reliability under load, cost predictability at scale, and the ability to survive a technical review conducted by someone whose entire job is to find what breaks. In short: what matters now is scalable software architecture.
Here is what that looks like in practice. A SaaS founder at 35,000 users, a monolithic backend built by a two-person contractor team in eight weeks. The same architecture that got them to Series A conversations was generating intermittent errors during peak traffic — not consistently, not catastrophically, just enough to be unsettling. Their engineering lead called it a 'known issue they were monitoring.' The investors' technical advisor called it a single point of failure with no remediation plan.
Same codebase. Entirely different interpretations — because they were asking different questions about it.
The question is not 'was this built well.' The question is 'was this built for where you are going.' Conflating those two is exactly why infrastructure risk stays invisible until it surfaces at the worst possible moment.
The 4 Ways Startup Infrastructure Breaks Before Your Investors Ask About It
Before a technical due diligence process finds these problems, your users will. These are the four failure modes that surface most consistently at your exact stage — and what they cost when they arrive.
1. Your Database Is Probably the First Thing That Breaks Under Startup Scaling
Database read/write contention on a single relational instance is the most common first infrastructure crisis for companies between 10,000 and 150,000 users. The post-mortems from Airbnb, Pinterest, and Instagram all document it as the first major failure they encountered during rapid growth. That is not a coincidence — it is a structural property of single-database architectures under increasing concurrent load. It is also the most predictable challenge in startup scaling technology, and the one most consistently left unaddressed until it causes a visible incident.
The user-facing symptom is your checkout flow, or your core feature, becoming intermittently unavailable during your highest-traffic moments. Not slow. Not degraded. Unavailable — for some users, on some requests, unpredictably. The failure is indistinguishable from a product bug until you are deep enough in the logs to see what is actually happening, and by then the moment has already passed. At approximately 50,000 concurrent sessions, a single-database architecture without read replicas or connection pooling will begin dropping requests — not consistently enough to trigger an alert, but consistently enough to matter.
Has your team mapped what breaks first if your load doubles next month?
2. Your Cloud Bill Has a Surprise Waiting for You
Andreessen Horowitz has documented that cloud infrastructure costs represent 50 to 80 percent of COGS for SaaS companies. That number alone should recalibrate how you think about infrastructure as a line item. But the more immediate risk is what happens to that number during a growth inflection — a problem that sits at the heart of cloud scalability for startups.
Startups without autoscaling policies, cost tagging, and budget alert infrastructure routinely see 300 to 500 percent cost overruns relative to projections in the month they hit a significant user growth event. Not a gradual increase — a cliff. You are telling investors a unit economics story with specific assumptions baked in, and a single month of infrastructure costs that does not match the model destroys the credibility of the entire projection. That is not an engineering problem. That is a fundraising problem.
Cloud scalability for startups is not just about keeping the product online — it is about keeping your financial model credible under the scrutiny of a Series A process.
Do you know your infrastructure cost per active user last month — and how it changes if your user base doubles?
3. If You Cannot See What Is Breaking, You Are Flying Blind
Observability — the combination of logs, metrics, and distributed tracing that tells you what your system is doing in real time — is now a first-class requirement of any scalable software architecture, not a nice-to-have. A 2023 Honeycomb survey found that teams with mature observability practices resolve production incidents 30 percent faster than those without. At your stage, that gap is the difference between a contained incident and a customer-visible failure that lands in your app store reviews.
If your team cannot tell you within minutes what broke, where it broke, and how many users were affected, you do not have an engineering problem. You have a business intelligence problem. And it will surface at the moment you can least afford it — during a high-traffic campaign, a product launch, or the week an investor's advisor is quietly watching your system perform.
4. Your Deployment Process Is Already a Competitive Liability
If shipping a new feature requires a manual process, a specific person, and a period of collective breath-holding across the engineering team, your release cadence is a liability. The DORA State of DevOps Report found that elite engineering teams — those deploying multiple times per day with low change failure rates — are four times more likely to have adopted Infrastructure-as-Code practices from early in their lifecycle.
At your current stage, slow deployment cycles mean slower response to customer feedback, slower competitive iteration, and a fragility that compounds as your team grows. The companies that outpace you in the next eighteen months will not do it by working harder. They will do it by shipping faster without breaking things — and that is a startup scaling technology property, not a talent one.
When did you last ask how long it takes to go from a merged pull request to a feature in production?
What Series A Technical Due Diligence Actually Looks For
Founders consistently underestimate what happens during a technical due diligence process. It is not a tour of what you have built. It is a structured search — conducted by experienced engineering advisors whose job is to find the architectural decisions that will constrain your velocity at the next stage, price the cost of addressing them, and give the investor a clearer picture of the risk they are actually buying.
The three findings that appear most consistently in these reviews translate into business language as follows.
Single points of failure are concentration risk. If your database goes down, your entire product goes down. If the engineer who provisioned your infrastructure leaves, reproducing it requires weeks of archaeology. These are not engineering concerns — they are the same category of risk as customer concentration, supplier dependency, and key-person risk in any other part of the business.
The absence of Infrastructure-as-Code signals that the system cannot be reliably reproduced or audited. When your infrastructure is assembled manually rather than defined in code, it exists primarily in the heads of the people who built it. It cannot be handed to a new engineering leader, cannot be reviewed by an investor's technical advisor, and cannot be reproduced consistently in a new environment. From a due diligence perspective, it is the technical equivalent of keeping your financial records in a spreadsheet on someone's personal laptop.
No observability stack means the team is flying blind during incidents — and the investor knows it. A system without logs, metrics, and tracing is a system the team cannot explain. A team that cannot explain its system cannot credibly describe how it will manage that system at five times the current scale.
Here is what those findings cost in practice. A B2B SaaS founder at 60,000 users entered a Series A process with strong revenue metrics and a compelling growth story. The technical review surfaced a manually provisioned infrastructure with no IaC, a monolithic database with no replication strategy, and no production monitoring beyond basic uptime alerts. The term sheet arrived with a condition: a documented remediation plan, reviewed and approved before close. The round took three months longer than projected, and the valuation conversation shifted from growth multiple to risk discount.
Infrastructure readiness is a fundraising asset. Investors pricing your round are also pricing the infrastructure work they know will need to happen eventually. If you have already built scalable tech infrastructure, your valuation reflects that. If you have not, the cost gets subtracted from what they are willing to pay now.
The question is not whether you need to address this before your raise. The question is whether you have defined — in advance — the specific thresholds at which particular architectural changes get made. Investors want to see that you manage technical risk with the same intentionality you apply to commercial risk. A roadmap with scaling triggers is evidence of that intentionality. An absence of one is evidence of the opposite.
The Architectural Decisions That Foreclose Options vs. the Ones That Preserve Them
Every architectural decision is actually a business optionality decision. The question is never whether microservices are technically superior to a monolith. The question is: what does each path cost to maintain, what does it cost to change, and what does it make possible or impossible in the next eighteen months?
On the monolith versus microservices question: Engineering leaders at Shopify, Stack Overflow, and Basecamp have publicly documented that a well-structured monolith can support tens of millions of users. Premature decomposition into microservices is one of the most frequently cited causes of operational complexity for sub-50-engineer teams. When you break a single deployable application into a constellation of independently deployed services before you have the team topology, tooling, or operational maturity to manage them, you trade one set of problems for a far harder set. For a team your size, that trade is almost never worth it. A clean monolith keeps more options open, at lower operational cost, than a premature microservices architecture that requires three engineers to understand and nobody to fully own.
On Infrastructure-as-Code: When your infrastructure is defined in version-controlled code rather than assembled through a series of manual clicks and undocumented decisions, it becomes a company asset rather than institutional knowledge. It survives employee departure. It survives technical due diligence. It can be handed to a new engineering leader without a month of knowledge transfer. AWS data shows that startups using serverless or containerized architectures from early in their lifecycle reduce infrastructure cost-per-user by 40 to 60 percent compared to teams that migrate later under production load. Getting this right early — making it part of your scalable software architecture from the start — is substantially cheaper than getting it right under pressure.
On build versus buy: Managed services for authentication, queuing, database management, and monitoring cost more per unit than self-managed equivalents. Before Series B, they are almost always the correct answer. The engineering hours you do not spend maintaining infrastructure are the engineering hours you spend on the product your customers pay for. That calculus changes after Series B, when you have the team and scale to justify ownership. It does not make sense before.
Here is the direct challenge: if you cannot answer 'which architectural decision made in the last eighteen months would be hardest to reverse, and what would it cost to reverse it' — that gap is the difference between a strategy and a backlog. One of those is manageable. The other tends to surface during due diligence.
A Diagnostic You Can Run This Week
You do not need to be an architect to have this conversation. You need five questions to bring to your engineering lead or development partner — framed not as technical interrogation, but as business risk calibration.
On load: 'What is the first component that breaks if our user load doubles next month? Not degrades — breaks. And how long would it take us to fix it under pressure?'
On reproducibility: 'Can you reproduce our entire infrastructure from scratch in under a day, with no manual steps? If you left tomorrow, could someone else do it without asking you anything?'
On incident response: 'How long did it take us to identify and resolve the last production incident — and how did we know it was actually resolved, not just assumed resolved?'
On cost: 'What does our infrastructure cost per active user today, and what does that number look like if we add 50,000 users in the next six months?'
On deployment: 'How many people need to be involved in shipping a feature to production, and what is the last thing that went wrong when we did it?'
Then two investor-readiness questions:
'If a technical advisor from our lead investor spent a day reviewing our codebase and our cloud console, what would they flag — and do we have a documented response to each of those things?'
'Do we have a written set of thresholds — specific user volumes, transaction loads, or data sizes — at which we have committed to making specific infrastructure changes?'
The goal is not to uncover a crisis. It is to convert vague anxiety into a named inventory of specific decisions. Named decisions are manageable. Unnamed dread is not.
What you are building toward is a technical risk register — a living document that maps architectural decisions to business consequences, maintained with the same discipline you apply to your financial model. Not an engineering artifact. A business tool. The founders who enter their Series A process with one are not better engineers than the ones who do not. They are better prepared.
If you run through these questions and find more uncertainty than answers, that is useful information. It tells you exactly where the judgment gap is — and where to go close it.
Frequently Asked Questions: Scalable Tech Infrastructure for Startups
What is scalable software architecture?
Scalable software architecture is a system design approach that allows your application to handle increasing users, data, and transaction volume without requiring a full rebuild. For startups, this typically means implementing read replicas for database load distribution, Infrastructure-as-Code for reproducible and auditable deployments, autoscaling cloud policies to manage cost during growth events, and an observability stack (logs, metrics, and distributed tracing) so your team can characterize and respond to incidents in real time. The goal is not to over-engineer at the MVP stage — it is to make architectural decisions that preserve your options rather than foreclose them as you scale.
What is Infrastructure-as-Code (IaC)?
Infrastructure-as-Code means your cloud environment — servers, databases, networking rules, permissions — is defined and managed through version-controlled configuration files rather than manual setup through a web console. Tools like Terraform, Pulumi, and AWS CloudFormation are common implementations. From a business perspective, IaC means your infrastructure is auditable, reproducible, and not locked inside the head of the engineer who built it. During Series A technical due diligence, the absence of IaC is one of the most commonly flagged risks.
What is an observability stack?
An observability stack is the combination of logging, metrics collection, and distributed tracing that gives your engineering team real-time visibility into what your system is doing. Mature observability means that when something breaks, your team can answer within minutes: what broke, where it broke, how many users were affected, and what the root cause was. Without it, incident response becomes guesswork — a significant liability during a Series A process when investors are evaluating your operational maturity.
What do investors look for in technical due diligence?
Investors conducting technical due diligence are looking for architectural decisions that will constrain your velocity at the next stage of growth, and pricing the cost of addressing them. The three most consistently flagged findings are: single points of failure (especially a monolithic database with no replication), absence of Infrastructure-as-Code (infrastructure that exists in someone's memory rather than in auditable code), and no observability stack (a team that cannot explain its own system's behavior under load). Each of these findings can delay a term sheet, add remediation conditions to a close, or shift the valuation conversation from growth multiple to risk discount.
How do I know if my startup infrastructure is ready to scale?
Run the diagnostic in the section above. The key questions are: what breaks first if your load doubles, can your infrastructure be reproduced without the person who built it, how long does incident resolution take, and what does your infrastructure cost per active user at 2x your current scale? If you cannot answer these questions with confidence, you have a named gap — and a named gap is manageable in a way that undefined dread is not.
The Judgment Gap — and How Founders at Your Stage Close It
Here is the structural problem stated plainly. Hiring a full-time CTO with the architectural judgment this moment requires costs between $250,000 and $400,000 annually in most markets. It takes three to six months to do well. And if you make the hire before you know precisely what problem you are solving, you will spend the first quarter of the engagement figuring that out — at executive cost.
What you actually need is not more engineering hours. It is architectural judgment applied specifically to your current inflection point. Someone who has seen this exact failure mode before — the 40,000-user monolith with no replication strategy, the manually provisioned infrastructure that unravels during due diligence — and who can translate what they see in your system into a prioritized picture of business risk. That is a different capability than execution capacity, and it requires a different kind of engagement.
The fractional or advisory architecture model is not a compromise. At this stage, it is the structurally correct answer. Senior pattern recognition, applied at the moment it is most needed, without the fixed cost of a full-time executive whose role will evolve significantly after your Series A closes anyway. The judgment this moment requires does not need to sit on your payroll permanently. It needs to be available now, focused on the decisions that matter in the next twelve months.
Here is what that looks like in practice. A marketplace founder at 80,000 users brought in architectural advisory support six months before entering a Series A process. The engagement identified three specific remediation priorities: database replication to eliminate single-instance risk, Infrastructure-as-Code adoption to make the system auditable, and basic observability tooling so the team could characterize incidents rather than guess at them. Two of the three were addressed before the investor technical review began. The third was documented with a clear remediation timeline. The term sheet reflected infrastructure confidence rather than infrastructure risk — and the valuation conversation stayed focused on growth trajectory rather than technical liability.
The question this piece has been building toward is one you have probably already asked yourself: how do I get this kind of judgment, applied to my specific situation, without making a hire that does not fit the stage I am in?
That is the question Semicolon is built to answer.
What the Next Step Actually Looks Like
The window between your current traction and your Series A process is when decisions about scalable tech infrastructure are cheapest to make — not because the work is easier, but because the pressure is lower, the options are wider, and you are not making changes to a system that investors are actively reviewing.
An initial engagement with Semicolon produces three specific outputs:
A technical risk register that maps your current architectural decisions to their business consequences — not a list of things that might theoretically go wrong, but a bounded, prioritized inventory of the specific risks at your current scale.
A remediation roadmap sequenced for your stage — which decisions need to be made before your Series A process begins, which can wait, and what each one costs in time, money, and engineering focus.
A clear picture of your investor-readiness posture — what a technical advisor would find today, what you want them to find instead, and the specific gap between those two things.
If that sounds like the clarity you have been looking for, the starting point is a single conversation. Not a sales process. Not a lengthy assessment. A direct discussion about what you are looking at and what it would take to see it clearly.
The dread does not go away on its own. But it becomes manageable the moment it has a name.
---
# How to Choose the Right Tech Stack for Your Startup in 2026 (It's No Longer Just a Technical Decision)
Source: https://smicolon.com/blog/how-to-choose-tech-stack-for-startup-2026
Updated: 2026-08-26T15:33:39.291Z
How to Choose the Right Tech Stack for Your Startup in 2026
The Decision You Made at Pre-Seed Is Now a Series A Variable
If you are trying to figure out how to choose a tech stack for your startup in 2026, the most important thing to understand upfront is this: it is no longer a purely technical question. Something is working. Users are in the product, revenue is moving, the pitch is sharper than it was six months ago. But underneath the momentum there is a feeling you have not quite named — the codebase seems heavier than it should, that last engineering hire took longer than expected, and your CTO has mentioned more than once that certain things will need to be 'revisited when you scale.' You nodded and kept pushing.
That feeling is data.
What it usually points to: the stack choices that felt like reasonable defaults at pre-seed have quietly become load-bearing walls. And the cost of changing them does not stay flat — it scales with your success. More customers, more engineers hired around a particular architecture, more integrations stacked on top of a particular infrastructure choice — the more expensive it becomes to touch the foundation. That is not a flaw. That is compounding.
The frame most founders are missing is simpler than it sounds: every stack decision is a capital allocation decision. The framework your team chose, the infrastructure your first engineer set up, the database your agency recommended — each one carries a downstream cost in burn rate, hiring velocity, or diligence risk. Those costs do not show up on your first AWS bill. They show up on a Series A diligence call when a technical advisor asks questions you cannot answer cleanly, or in the post-raise sprint when your job descriptions are not landing the candidates you need.
This is not a technical teardown. What follows is a business-layer translation of the five decisions that show up most reliably in pre-Series-A audits and post-raise hiring crunches — and a practical framework for assessing where you actually stand before someone else does it for you.
The choices you made to get here were the right ones for the stage you were in. The question now is whether they are still the right ones for the stage you are heading into.
Why Stack Choices Feel Reversible Until They Aren't
At pre-seed, the assumption that you could always change the stack later felt true — because it was. Two hundred users, three engineers, a codebase four months old: almost anything can be reworked in a sprint or two. Early-stage teams are right to prioritize speed over architectural perfection.
The problem is that the feeling of reversibility persists well past the point where it is accurate.
By Series A, your codebase is 18 months older. Your team has built muscle memory around specific patterns. Your infrastructure has undocumented dependencies your original engineer understood but never wrote down. Your product has features that interact with architectural choices in ways nobody fully mapped. Changing the foundation at that point is not a sprint — it is a project. And that project has a real cost that belongs in your financial model.
A mid-stage architectural rewrite typically consumes 6 to 18 months of engineering bandwidth. At a fully-loaded engineer cost of $15,000 to $25,000 per month, a four-person team spending half its capacity on a rewrite burns $360,000 to $900,000 before a single new feature ships. In worse cases — a full framework migration, a database change, a move from custom to managed infrastructure — that number climbs past $1.5 million. And the timing is almost always the worst possible: right after a raise, at the exact moment your growth plan requires your team to be shipping product, not re-plumbing the foundation.
Here is a question worth sitting with: if a VC asked you tomorrow — not a hostile question, just a curious one — why your team chose this architecture over a more standard alternative, how would you answer? If they followed up with 'what would it cost to migrate if you needed to,' would that answer hold?
Most of the dangerous choices are not exotic. They are not obviously wrong. They are reasonable defaults that solved a pre-seed problem efficiently while quietly creating a Series A problem. That is precisely what makes them worth examining now, when the examination is still relatively cheap.
Framework and Language: When 'Everyone Uses It' Becomes a Hiring Constraint
Choosing a familiar framework at pre-seed is rational. Your CTO knew it, your first contractor was productive in it on day one, and you shipped your MVP in weeks instead of months. Speed to first build is a real advantage. There is nothing wrong with the instinct.
But the same logic that makes a framework a good pre-seed choice can make it a quiet liability by Series A. The mechanism is straightforward: your framework determines the size of the talent pool you can hire from.
What the Data Says About Language Adoption in 2026
GitHub's 2025 Octoverse report shows Python and TypeScript together now account for over 60% of new repository activity. TypeScript surpassed JavaScript as the most-used language among professional developers for the first time in the 2025 Stack Overflow Developer Survey. On the other end of the spectrum, Ruby on Rails job postings have declined 34% since 2022. Rails is still a capable framework — productive teams are running on it — but declining adoption has a specific business consequence: you are recruiting from a shrinking pool at the exact moment you need to hire fast.
Hiring speed in the six months after a Series A closes is not a soft metric. It is the primary determinant of whether your growth plan executes on schedule. Investors model headcount ramp when they write the check. If job descriptions are taking three months to close instead of six weeks because your framework filters out 80% of available candidates, that delay compounds against every milestone in your operating plan.
The TypeScript/Next.js/Node.js combination has become the default for a reason beyond fashion: roughly 42% of new web-based ventures start here, it represents the widest available hiring pool, and it is the most due-diligence-legible choice at this stage. That does not make it the only right answer. But if your stack sits outside it, you need a specific and defensible explanation — for your next engineering hire who will ask 'why are we using this,' and for the technical advisor who will ask the same question with a term sheet on the table.
AI Integration Readiness: No Longer Optional
There is a second dimension that is harder to ignore by the quarter: AI integration readiness. A 2025 a16z survey found that 78% of early-stage founders now consider native LLM/AI API compatibility a top-three infrastructure factor — up from under 20% in 2023. Frameworks without mature AI SDK support create a secondary tax: custom bridging code your engineers write and maintain instead of shipping product. If your competitors are deploying AI-native features in days using existing SDK primitives and your team is spending weeks building the plumbing to connect those same tools to your stack, that gap is not a future problem.
The honest tradeoff: an unconventional stack is not automatically wrong. Some teams have genuinely good reasons — specific performance requirements, deep team expertise, a niche ecosystem that serves their domain. But 'we chose it because our first engineer knew it' is not a defensible answer at Series A. Know which side of that line you are on.
Infrastructure: Optimizing for Today's Bill Instead of Tomorrow's Audit
When runway is tight and you have a few hundred monthly active users, paying for enterprise-grade infrastructure feels like what it is: wasteful. Keeping the infrastructure bill low at pre-seed is not naive — it is financially rational. Founders who resist over-engineering at early stage are often the ones who stay solvent long enough to find PMF.
But there are two infrastructure traps, and founders tend to worry about only the first.
The first trap — over-investing before you have the traffic to justify it — is less common than it used to be. Serverless and edge-first platforms like Vercel, Cloudflare Workers, and AWS Lambda have fundamentally changed the cost economics at low scale. Below 100,000 monthly active users, you can operate at near-zero cost on managed platforms that would have required a dedicated DevOps engineer five years ago. The startup that builds custom server infrastructure at pre-seed to 'save money' often burns $20,000 to $40,000 in engineering time managing something a $50/month service would have handled — and gets nothing but operational complexity in return.
The second trap is more expensive and less discussed: choosing infrastructure that cannot explain itself in a diligence conversation. Bespoke server configurations. Unmanaged databases with no automated backups. Deployment pipelines that only one person understands, and that require a dedicated DevOps hire to maintain the moment that person leaves. This feels fine when the team is small and everyone knows where everything is. At Series A headcount — four new engineers who have never seen the system — it becomes a fragility risk that technical reviewers will flag.
The compliance dimension compounds this further. If your target customers include enterprise accounts, healthcare, fintech, or edtech, SOC 2 Type II is not a nice-to-have. It is increasingly a literal gate between a signed contract and a prospect who goes quiet. Managed infrastructure providers — Supabase, Neon, AWS RDS with built-in audit logging — offer SOC 2 Type II compliance as a platform feature. Choosing them at pre-seed reduces the engineering cost of achieving certification from scratch by an estimated 60 to 70%.
The alternative is a retrofit. A SOC 2 compliance retrofit on a custom infrastructure stack — third-party tooling like Vanta or Drata, audit logging implementation, evidence collection, policy documentation, penetration testing — typically costs $75,000 to $200,000 and takes 6 to 12 months. If your sales pipeline includes any enterprise prospect, that cost belongs in your financial model as a near-term line item, not a vague future problem.
Here is what that looks like concretely: a single enterprise deal worth $150,000 ARR that stalls six months because SOC 2 is not ready does not just cost you $75,000 in delayed revenue. It costs you the compounding valuation credibility that closed deal would have provided in your Series A narrative. The infrastructure choice made at pre-seed becomes a direct variable in that negotiation — one most founders did not realize they were making at the time.
Architectural Complexity: The Microservices Credibility Trap
Microservices architecture carries a credibility signal. It is how Netflix, Uber, and Amazon are built. A technically ambitious CTO often defaults to it because it is the architecture they respect and can defend in a room full of engineers. If your agency or technical lead proposed it early, they were not wrong about the architecture's merits at scale — they were solving a problem you do not have yet.
The business cost is specific. A microservices system is not one codebase — it is a distributed system of interdependent services, each with its own deployment pipeline, its own failure modes, and its own mental model that a new engineer must build before contributing meaningfully. Onboarding time on a well-structured monolith runs roughly 2 to 4 weeks. On a complex microservices architecture with inadequate documentation — which describes most pre-seed systems that were never designed for team growth — that climbs to 6 to 12 weeks.
At a post-Series-A hiring pace of 4 to 6 engineers in the first six months, the difference compounds fast. If each hire takes 6 additional weeks to reach full productivity, you are looking at 24 to 36 engineer-weeks of delayed output in the first half-year. At $15,000 to $25,000 per engineer-month, that overhead costs $90,000 to $225,000 in salary for productivity you have not received — before accounting for the management attention extended onboardings require.
Y Combinator's 2024–2025 cohort guidance is unambiguous on this: they explicitly advise founders to choose proven, well-documented technologies over cutting-edge alternatives, and directly correlate stack novelty and premature architectural complexity with lower 18-month survival rates. This is not contrarian advice. It is pattern recognition from the largest concentration of early-stage company data in the world. Debugging a distributed system during a critical go-to-market phase drains exactly the founder and engineering attention that should be pointed at one thing: finding PMF.
The due diligence signal is equally clear. Bessemer's 2025 engineering due diligence framework explicitly flags microservices complexity as a scalability red flag when it is not matched by team size and traffic volume. An architecture that implies a 15-person platform team when you have four engineers is not a credibility signal to a technical reviewer. It is a question about judgment.
The honest path forward: a well-structured monolith with clean internal boundaries is not technically immature. It is architecturally appropriate for the stage. A monolith where services are logically separated — even if not physically deployed separately — is genuinely easier to decompose at Series B when you have the team size and traffic to justify it. That decomposition becomes significantly harder when the starting point is a prematurely distributed system that was never fully documented.
Vendor Lock-In: When 'Convenient' Becomes 'Captive'
Consolidating on a single vendor ecosystem at pre-seed makes sense. Fewer integrations to manage, predictable billing, faster setup — when your team is three people and every hour counts, these are real advantages. You were not wrong to make this tradeoff early.
The risk is not that you used managed services. The risk is a specific type of dependency that only becomes visible when it is expensive to unwind.
There is a meaningful distinction between healthy ecosystem consolidation and problematic lock-in. Using Vercel for deployment, Supabase for your database, and Stripe for billing is not a lock-in problem. Each is widely adopted, well-documented, with clear migration paths and strong independent support ecosystems. You could migrate any one of them without touching the others. That is healthy — you are moving fast on reliable tools that have known off-ramps.
The pattern that creates real exposure looks different: using a single low-code or no-code platform for your core application logic, your data model, and your customer-facing API simultaneously. When your product roadmap and your infrastructure vendor's roadmap are the same thing, you have lost the ability to make independent decisions about either. That is a fundamentally different kind of dependency.
It surfaces in two specific places at Series A. First, technical due diligence reviewers flag single-vendor dependency as a business continuity risk. The question they will ask — one you should be able to answer before they do — is: 'What happens to your product if this vendor raises prices by 3x, changes its terms of service, or gets acquired by a competitor?' If your honest answer involves a significant engineering project to execute, that is a risk sophisticated investors will price into the deal. Not necessarily a deal-breaker, but a variable.
Second, your future engineering team will have limited leverage to optimize costs or architecture without switching the entire foundation. That constraint gets more expensive as the team grows.
The practical lens: use managed services aggressively — at this stage, you absolutely should. Ask two questions about each one: does it have a clear migration path, and does your core application logic live somewhere you own? If both answers are yes, you have speed-optimized infrastructure. If either answer is no, you have a structural dependency worth understanding before someone else explains it to you in a diligence call.
The Pre-Diligence Audit: Three Questions to Ask Before Your Next Raise
Think of this as running the diligence yourself first — so you control the narrative rather than react to it.
Question One: The Hiring Test
If you needed to hire three mid-level engineers in the next 90 days using your current stack as the job description, how large is the available talent pool — and how long would onboarding realistically take?
Do not treat this as rhetorical. Run the actual search. Open LinkedIn, filter for engineers with your primary framework, set the geography to your target hiring market, and count. A thin pool is immediately obvious — you will see the same 40 profiles cycling through the same searches. Thin means two things at the business layer: higher salary premiums to compete for scarce talent, and longer time-to-productivity because you are hiring people who need to learn the stack rather than people who already know it. Both reduce how far your Series A capital stretches.
Question Two: The Compliance Readiness Test
If your most promising enterprise prospect required SOC 2 Type II as a condition of signing, what would it cost you — in time and money — to get there from your current infrastructure?
If the answer is more than four months or more than $100,000, that cost belongs in your financial model right now. Not as a future scenario — as a near-term capital requirement that will arrive before your next funding event if your pipeline has any enterprise motion in it at all. The founders who get surprised by this question in diligence are the ones who never asked it of themselves first.
Question Three: The Explainability Test
Can you walk a technically literate investor through the three most consequential architectural decisions in your stack, explain the business reasoning behind each, and describe what changes as you scale from 100 to 10,000 customers?
Notice what this is actually testing. Not deep technical knowledge — business intent. That is the signal a Series A technical advisor is actually looking for. Not perfection. Not sophistication. Intentionality. A founder who can say 'we chose this because it gives us access to the widest engineering talent pool in our market and it has a clear migration path when we need to split it' is in a fundamentally stronger position than one who says 'our CTO picked it' and moves on.
If all three questions produce clean, confident answers, your stack is likely a non-issue in diligence. If one or more surfaces a gap, you now have a prioritized list of what to address before the raise — which is a far better position than discovering those gaps in the room with a term sheet on the line.
What Are the Most Important Tech Stack Decisions for Startups in 2026?
Building a scalable tech stack for a growing business comes down to five decisions that compound well before you reach Series A. The window between pre-seed and Series A is the last moment when foundational changes are affordable. Not cheap — affordable. With a smaller team, lower velocity, and no investor milestones on the clock, you can make structural improvements in weeks that would take months post-raise. After the round closes, with new engineers onboarding, quarterly targets in play, and a board expecting product velocity, the cost of touching the foundation rises with every passing month.
This is not a reason to panic. It is a reason to act with intention in the next 60 to 90 days.
Framework and language relative to your post-raise hiring plan: is your stack pointing at the widest available talent pool, or a narrowing one? Choosing the right tech stack for your startup starts here — your language choice is also a hiring strategy.
Infrastructure architecture relative to your compliance roadmap: does your infrastructure make SOC 2 a 60-day conversation or a 12-month project?
Architectural complexity relative to your current team size: does your system match your headcount, or does it imply a team three times larger than the one you have?
Vendor dependency relative to your business continuity risk: can you answer the 3x price increase question with a credible migration plan?
AI integration readiness relative to where your product category is heading: does your stack let you ship AI-native features in days, or require months of custom bridging first?
None of these require a full rebuild to address. Some require a documented plan. Some require a direct conversation with your CTO. Some require a managed service swap that takes a week. The point is to know which ones apply to you — and in what order — before someone else tells you.
Choosing the Right Tech Stack for 2026: What Good Looks Like Now
Founders who walk into Series A with a clear, honest, business-translated view of their scalable tech stack for a growing business — and a documented plan for how it evolves — consistently come out of diligence in a stronger position than those who encounter architectural questions for the first time in the room. It signals maturity. It keeps the technical narrative in your hands rather than a VC's technical advisor's.
If you want to run through this with someone who has sat in these conversations — not to sell you a rebuild, but to give you an honest read on where you stand and what to address first — that is exactly the conversation Semicolon has with founders at this stage. Sixty minutes. No cost. The founders who find it most useful are reliably the ones who came in fairly confident they did not need it.
You have built something real. The decisions you made to get here were right for the stage you were in. The question now is not whether those decisions were good — it is whether they are still the right ones for the stage you are heading into.
That is worth knowing before someone else tells you in a diligence call.
Frequently Asked Questions
What is the best tech stack for a startup in 2026?
For most web-based startups in 2026, the TypeScript/Next.js/Node.js combination offers the best balance of hiring pool depth, AI integration readiness, and due diligence legibility. It represents approximately 42% of new web venture starts and gives you access to the widest available engineering talent market. That said, the best stack is the one your team can hire around, maintain, and explain — not the most fashionable one. If you have a specific performance requirement or domain need that points elsewhere, that is defensible. 'Our first engineer knew it' is not.
How do I know if my tech stack will scale?
Ask three questions: Can you hire mid-level engineers for it in under six weeks in your target market? Does it have a documented migration path for each major component? And can your CTO explain in business terms what changes architecturally between 100 and 10,000 customers? If the answers are yes, yes, and yes, your stack is likely to scale cleanly through Series A. If any answer is no, that gap is worth addressing before your next funding conversation — not after.
What tech stack should I use for a Series A startup?
By Series A, your stack needs to pass two tests beyond pure technical merit: it needs to support rapid hiring (your framework should have broad adoption and a deep talent pool), and it needs to be explainable to a non-engineer investor in business terms. Managed infrastructure over custom, a monolith with clean internal service boundaries over premature microservices, and frameworks with mature AI SDK support all correlate with cleaner diligence outcomes in the current fundraising environment.
How much does it cost to change your tech stack at Series A?
A mid-stage architectural rewrite typically consumes 6 to 18 months of engineering bandwidth. For a four-person team spending half its capacity on the rewrite, that represents $360,000 to $900,000 in fully-loaded engineering cost before a single new feature ships. Full framework migrations or database changes can push past $1.5 million — and almost always land at the worst possible moment: immediately after a raise, when your growth plan requires your team to be shipping product.
Does my tech stack affect Series A fundraising?
Yes, directly. Technical due diligence is now standard at Series A and the questions are increasingly specific: talent pool size for your framework, compliance readiness, architectural complexity relative to headcount, and vendor dependency risk. A stack that is hard to hire around, requires a costly SOC 2 retrofit, or implies a team three times your current size will surface as a variable investors price into the deal — or flag as a condition of close.
---
# In-House vs Outsourced Software Development in 2026: What the Numbers Actually Say
Source: https://smicolon.com/blog/in-house-vs-outsourced-software-development-2026
Updated: 2026-08-26T15:33:46.891Z
In-House vs Outsourced Software Development in 2026: The Engineering Resourcing Decision That Already Cost Someone Else Six Months of Runway
If you're weighing in-house vs outsourced software development in 2026, your skepticism of every available option is the correct starting position. The failure rates are not reassuring: outsourced IT projects fail outright at 17 to 31 percent (Standish Group CHAOS Report; McKinsey), and up to 45 percent experience significant overruns on scope, budget, or timeline. Full in-house hiring carries a 45 to 62-day average time-to-hire in North America — before a single line of production code ships. And the dedicated-team model, the most commonly recommended option for founders who want to outsource software development for startups at Series A, fails more often than its proponents admit. This article covers the honest cost data, the real failure modes for all three models, and a five-minute decision framework built for where you actually are — not where a vendor pitch assumes you are.
Eighteen months post-Series A. Burn rate running 20% ahead of the hiring plan you showed your board. And somewhere in your recent past — or your near future — an engineering resourcing decision you are not confident you will get right.
Maybe you already made it. Maybe an offshore shop delivered a codebase so tightly coupled and sparsely documented that your new backend hire spent her first six weeks just mapping what existed. Maybe you ran the in-house hiring math, watched three senior engineering salaries clear payroll before a single production feature shipped, and felt the runway clock accelerate in a way that made your stomach drop. Or maybe you sat through a pitch from a "dedicated team" partner that turned out, on closer inspection, to be a staff augmentation shop with a nicer slide deck.
All three failure modes are real. They are not edge cases.
Those failure rate numbers sound manageable until you translate them: a board conversation about why engineering velocity is six months behind the roadmap you committed to, a team morale problem you cannot fully explain, and a competitive window that will not reopen on your schedule. The dollar loss is almost the least of it.
This article is not a sales funnel dressed as a framework. Every model here gets its honest failure analysis first — including the dedicated-team and hybrid partner model, which is the one most likely to fit your stage and which fails more often than its proponents admit. By the end, you will have a diagnostic you can run against your own context, a vetting framework to separate genuine engineering partners from vendors speaking partner language, and a decision tree that produces a specific next action — not more to think about.
Start with why your skepticism of every available option is the correct prior.
Why Your Skepticism of All Three Models Is Structurally Correct in 2026
Loss aversion at eighteen months post-Series A is not anxiety. It is rational signal. A failed six-month engagement does not set you back six months — it sets you back six months, plus the time to diagnose what went wrong, plus the time to find a replacement path, plus the compounding cost of whatever shipped late or not at all during that window. That asymmetry makes skepticism the correct starting position, not a psychological obstacle to overcome.
Your existing premises are accurate. Project-based outsourcing carries coordination overhead that compounds on short runways. Every handoff, every asynchronous clarification cycle, every sprint review conducted across time zones without shared context erodes throughput in ways that never appear in the original proposal. Full in-house hiring has a 45 to 62-day average time-to-hire for software engineers in North America (LinkedIn Talent Insights, 2024–2025) — and that clock starts after you have decided exactly what you need. Add 30 to 60 days of onboarding ramp before a new hire is operating at full capacity, and you are four to five months out before you see return on that investment. At a fully-loaded annual cost of $180,000 to $230,000 per mid-level US engineer — salary, benefits, payroll taxes, equipment, and management overhead — that is a significant runway commitment before a single feature ships.
Dedicated-team models, meanwhile, vary so wildly in execution that the label itself tells you almost nothing. It can mean anything from a genuinely integrated engineering partner with continuity, architectural investment, and outcomes accountability, to a staff augmentation shop that assigns you three developers simultaneously staffed across five other clients who will rotate off the moment a higher-margin opportunity appears.
One variable makes most existing comparison content on this topic obsolete: AI coding tools. GitHub Copilot data from 2024 shows augmented developers complete tasks up to 55 percent faster than unaugmented counterparts. That is not a productivity footnote — it structurally changes the cost-per-feature math underpinning every in-house vs outsourced software development comparison you have read. A three- or four-person in-house team with a mature AI toolchain can now approach the output previously associated with eight to ten outsourced developers, under the right conditions. Any framework that treats this as a trend mention rather than a first-order variable is giving you a map of 2021's territory.
One more structural reality worth naming: more than 70 percent of the comparison content on this topic is published by outsourcing agencies, IT staffing platforms, or developer marketplaces with a direct commercial interest in the conclusion. That is why none of it has felt trustworthy enough to act on. The analysis is not always wrong — but the incentive structure makes independent verification impossible. You noticed that. You were right to.
Is In-House or Outsourced Development Cheaper for Startups in 2026? Model One — Project-Based Outsourcing
The structural failure mode of project-based outsourcing is not incompetence. It is incentive misalignment. Fixed-scope contracts optimize for the vendor's ability to close an engagement cleanly, not your ability to own and extend what they built. Requirement drift — not an aberration but a normal feature of software development at your stage — becomes adversarial the moment it threatens a vendor's margin. The result is a codebase that technically meets the spec, produced by a team with every incentive to minimize scope and documentation and none to think about what your next engineer will need when they open the repository for the first time.
The hidden cost stack is what makes hourly rate comparison actively misleading. What you are actually buying:
Management overhead: 20 to 30 percent of a senior in-house engineer's time, consumed by coordination, review, and requirement translation
Onboarding drag: two to six weeks before a new vendor team reaches productive throughput on your domain
Rework cycles: industry estimates place these at 10 to 15 percent of total project cost on average, higher when the original spec was underspecified
Opportunity cost of shipping delay: in a competitive window that does not pause for your vendor's sprint velocity
None of these appear in the proposal deck.
Project outsourcing fails hardest under three conditions that describe most of the work that matters at Series A. Pre-product-market-fit discovery, where the spec is expected to evolve and often should — the iterative nature of pre-PMF development is structurally incompatible with fixed-scope contracts; the incentive architecture runs in exactly the wrong direction. Anything requiring iterative UX feedback loops, where you need a team that updates its mental model of the user problem, not one executing against a static requirements document. And any engagement where the definition of success might change, which is to say almost everything that matters before you have found repeatable growth.
There is a narrow window where project outsourcing is actually the right tool: well-defined, time-bounded, peripheral work. Data migrations, legacy system integrations, specific API builds with contractually specifiable inputs and outputs, compliance tooling where the requirement is an external standard rather than an internal hypothesis. If the deliverable can be specified, ownership transferred cleanly, and the work is non-core to your IP, project outsourcing can be efficient and appropriate. The problem is that Series A founders routinely hire project shops for work that does not meet these criteria.
Red flags in proposal language that signal ticket execution, not engineering partnership:
SLA definitions that measure response time rather than outcome quality
No mention of documentation standards or handoff protocols
IP assignment language that requires legal scrutiny to interpret — it should be unambiguous by default
No code escrow provisions
Milestone definitions tied to deliverable submission rather than functional acceptance
No named senior architect accountable for technical decisions — just a team composition
Model Two — Full In-House Hiring: The Runway Math That Looks Different at Month Fourteen
You remember when the hiring plan started to feel different. Not wrong, exactly — different. The Series A deck showed a clean linear relationship between headcount and velocity. Month fourteen shows you that engineering salaries clear payroll with precise regularity whether or not a production feature shipped, and the 45 to 62-day recruiting clock you budgeted for did not account for the three candidates who accepted offers elsewhere, the two who made it to final rounds and misrepresented their systems experience, or the 30 additional days the eventual hire needed before operating independently.
The honest cost comparison: a mid-level software engineer in the US runs $180,000 to $230,000 fully-loaded annually. A dedicated developer in Poland or Romania costs $55,000 to $90,000. Nearshore Latin America — Mexico, Colombia, Argentina — runs $35,000 to $65,000, with time-zone alignment that has made this the fastest-growing segment for US startups seeking to outsource software development for startups, per Accelerance's 2024–2025 Global Software Outsourcing Report. That is a 40 to 75 percent labor cost difference before coordination overhead. This is not an argument for outsourcing — it is the honest input you need to run your own calculation against your actual runway.
Because in-house hiring has genuine structural advantages no outsourced model replicates at equivalent cost. Institutional knowledge accumulates differently when the people holding it will still be at your company in two years. Architectural alignment with long-term product vision happens when engineers live inside the strategic context, not when they receive briefs about it. Team culture coherence and the speed advantage of a team working on ambiguous problems with shared context — these compound over time in ways that favor the in-house model, particularly post-product-market fit.
The AI augmentation variable deserves more than a mention here. A three- or four-person in-house team with a mature toolchain — Copilot, Cursor, or equivalent — has materially compressed the output gap relative to larger outsourced teams. But the conditions matter. It requires engineers with the technical maturity to use these tools effectively and a codebase with enough architectural coherence to support AI-assisted development. A tangled codebase does not get rescued by Copilot — it produces tangled mess faster. The teams that extracted the most from lean in-house configurations in 2024–2025 were not necessarily those with the best tools. They were those with codebases structured from day one for AI-assisted extension — a decision made in the first 90 days that compounded for the following 24 months.
In-house hiring is the wrong first move when:
Time-to-first-feature is under 90 days and your runway cannot absorb 45-plus days of recruiting plus 30 to 60 days of onboarding
The domain expertise you need does not exist in your immediate hiring network and sourcing it will take longer than the window allows
Your burn rate is already running ahead of plan and adding three fully-loaded salaries before productive throughput begins is not a risk the runway can absorb
Outsourcing Software Development for Startups: The Dedicated Team Model in 2026
Start here, because every vendor in this category will lead with the benefits. You have already heard the pitch. The failure modes are what you need to understand first.
The most common failure is not dramatic. It is quiet. The team is "dedicated" in name but rotated on client demand, because the vendor's resource pool is shared and your account is not large enough to protect its composition when a higher-margin client has an urgent need. You find out three months in when your best developer on the engagement — the one who understood your data model — has been quietly moved to another account and replaced by someone who needs four weeks to get up to speed. The velocity you budgeted for was never going to hold.
A subtler failure mode: the team contributes to sprint velocity without anyone developing end-to-end ownership of the system. Individual developers produce good output. But no one on the vendor side holds the full architectural picture, so when an edge case exposes a wrong design assumption, the team routes it back to you instead of resolving it. You are functioning as the architect of a codebase being built by people who cannot architect it. This does not appear in the proposal, but it will consume your CTO's time in ways that compound.
Three stage conditions where even a well-executed dedicated model fails regardless of partner quality:
Internal technical leadership is too thin to provide meaningful architectural direction. A dedicated team mirrors your clarity — it does not substitute for it. If your direction is confused, the team will build a confused system efficiently.
Product direction is still in significant flux. Dedicated teams need a stable enough target to build toward. The cost of architectural pivots compounds when you are paying for continuity across a team that has to unlearn what it built.
The engagement is too short to recover the onboarding investment. A dedicated team operating below full throughput for the first six to eight weeks of a four-month engagement is a poor trade.
The 48 percent of enterprises shifting from project-based to dedicated and staff-augmentation models, per Gartner's 2025 CIO Survey, is not a marketing trend. It is a structural response to the failure modes at both extremes — project outsourcing's adversarial incentive structure and full in-house hiring's runway drag — and it reflects operational learning from a cohort of companies who experienced both.
What actually differentiates a true dedicated partner from a staff augmentation shop using partner language: team composition continuity that is contractually protected, not promised verbally; developer accountability to outcomes rather than hours logged; architectural participation, meaning a senior engineer who contributes to design decisions rather than just implements them; and a codebase at engagement end that a new CTO can walk into and understand, because that standard was an explicit deliverable from day one.
What Does Outsourced Software Development Actually Cost in 2026? The Decision Framework
Run through this against your actual company context. The goal is not to arrive at a predetermined answer — it is to surface which model your current inputs disqualify.
Self-Assessment Scoring Matrix
Input Variable | Your Current State | Weight
Runway remaining | __ months | High
Time-to-first-feature requirement | __ days | High
In-house engineering headcount + seniority | __ engineers, __ senior | High
Spec definition: % of work contractually specifiable | __% | High
AI toolchain maturity | None / Partial / Full | Medium
Work classification | Core IP / Peripheral | High
Internal technical leadership capacity | CTO full-time / Part-time / Absent | High
Model indicators by input profile:
Project outsourcing is indicated when spec definition is high (70 percent or more of the work is contractually specifiable), the work is peripheral rather than core IP, the engagement is time-bounded with a clean handoff, and IP assignment language is unambiguous before you sign. If any of these conditions is absent, the model is contraindicated regardless of cost appeal.
In-house hiring is indicated when runway exceeds 18 months, time-to-first-feature tolerance exceeds 90 days, the work is foundational IP you will build on for three or more years, and your hiring network can source senior talent within 30 days. If your runway is under 14 months and burn rate is already running ahead of plan, in-house hiring as your primary build strategy requires timeline confidence that is probably not warranted.
Dedicated partner is indicated when spec definition is moderate (you know enough to provide architectural direction but expect iterative discovery), the engagement runs at least six months, your internal technical leadership can provide meaningful direction at least 20 percent of their working time, and you have verified — contractually — that team composition will be protected for the duration.
Hard Disqualifiers
Any outsourced engagement where IP assignment is ambiguous. Eliminate regardless of rate, timeline, or relationship warmth. You cannot negotiate this after the code exists.
Any in-house hiring plan where the first productive commit is more than 90 days out on a sub-12-month runway. The math does not close.
Any dedicated partner without a documented code handoff protocol and escrow provisions. If they have not done this before, you will be the engagement that teaches them why it matters.
Software Development Outsourcing Cost Comparison 2026: In-House vs Outsourced (12-Month, Mid-Level Developer)
Cost Component | Project Outsourcing | In-House US | Dedicated Nearshore
Base labor cost | $40–80K (project) | $130–170K salary | $35–65K
Benefits / employer taxes | Not applicable | $25–40K | Not applicable
Management overhead | 20–30% of senior eng time | 10–15% of senior eng time | 15–20% of senior eng time
Onboarding drag | 2–6 weeks lost throughput | 4–8 weeks lost throughput | 4–6 weeks lost throughput
Rework cycle estimate | 10–15% of project cost | 5–10% of project cost | 5–10% of project cost
Opportunity cost of shipping delay | High — short engagement, misaligned incentives | Moderate to high — ramp lag | Moderate — continuity advantage
True total range | $65–130K, high variance | $180–230K, lower variance | $55–100K, moderate variance
Hourly rate represents, at best, 50 to 60 percent of the true total cost of engagement when you account for the full stack above. Any proposal that leads with hourly rate is not giving you the number you need.
Vetting Questions That Separate Engineering Partners from Vendors in Partner Language
Can you share architectural decision records (ADRs) from a prior engagement of comparable complexity? If they do not use ADRs, they are not operating as an engineering partner.
What is the ratio of senior to mid-level developers on the proposed team, and how is that protected contractually? The answer reveals whether the proposal was built around what you need or what their bench looks like.
Walk me through how your team handles a situation where the spec is incomplete or contradictory. Vendors describe escalation. Partners describe resolution.
What are your documentation standards, and how are they enforced during the engagement rather than at handoff? Handoff documentation is written at handoff. Continuous documentation is a process signal.
What is your code escrow and IP assignment structure? Non-negotiable. The answer tells you whether clients who understood the stakes have asked this before.
What the Companies That Got This Right Actually Did Differently
A Series A logistics software company — 20 months post-funding, $9 million raised, two in-house engineers — contracted a project-based shop in Southeast Asia to build their core carrier integration layer. The spec was detailed by their standards. The vendor came recommended by a portfolio company. Seven months later, they received a working integration their two in-house engineers could not extend. No meaningful documentation. Extensive coupling between modules. The vendor's team had turned over twice during the engagement, so the reasoning behind architectural decisions existed nowhere in writing. The company spent four months and roughly $180,000 in senior engineering time rebuilding the integration layer before it could support a new carrier.
What kept this from being unrecoverable: airtight IP assignment and an insistence on a code handoff meeting. The code was unusable as delivered, but it was theirs. They could rebuild rather than abandon. The companies that do not recover from this failure mode are the ones where IP assignment was ambiguous and the vendor's terms created legal exposure around a clean rebuild.
A second case: a B2B SaaS founder at month 14 post-Series A, $6.2 million runway remaining, three months from a board deadline for a demonstrable PMF signal. Full in-house hiring was the plan until she ran the actual math — three senior hires at her target profile, fully-loaded, against the timeline and remaining runway. She would hit the board milestone with a partially staffed team mid-ramp, which was worse than either alternative. She chose to outsource software development for her startup's near-term build using a nearshore dedicated team in Colombia — four developers with a senior architect — at roughly $85,000 total for six months, approximately one-third what two additional in-house hires would have cost for the same period. The signal that told her the transition back to in-house was right: the dedicated team started asking her architectural questions rather than answering them. That role reversal was the inflection point — the moment the team had hit the limit of what they could contribute without senior product-technical leadership sitting inside the company.
Both companies retained architectural control. Both made that decision contractually, before the engagement began. It was not a recovery strategy. It was the starting condition that made recovery possible.
Your Decision in Five Minutes
What is your current runway?
→ Under 12 months: In-house hiring as a primary strategy is likely disqualified by the time-to-throughput math. Move to the spec definition question.
→ 12 to 18 months: In-house hiring is possible if time-to-feature tolerance is above 90 days. Otherwise, move to spec definition.
→ Over 18 months: All three models are potentially viable. Proceed to spec definition.
What percentage of your near-term roadmap is contractually specifiable?
→ 70 percent or higher, and the work is non-core IP: Project outsourcing is a candidate. Apply the red flag checklist. Eliminate if IP assignment is ambiguous.
→ Under 70 percent, or the work is core IP: Project outsourcing is disqualified. Move to time-to-feature.
What is your time-to-first-feature requirement?
→ Under 90 days: In-house hiring is disqualified unless you have a candidate in your network who can start within two weeks and has done this domain before. Move to dedicated partner criteria.
→ Over 90 days and runway supports it: In-house hiring is viable. Run the fully-loaded cost comparison against your runway and board timeline.
For dedicated partner — three criteria to verify before committing:
Can your internal technical leadership provide meaningful architectural direction 20 percent of the time for the engagement's duration? If not, the team will mirror your confusion.
Is team composition protection contractual — not verbal? If not, negotiate it before signing.
Is IP assignment unambiguous, code escrow documented, and documentation standards specified in the contract? Any one of these absent is not a red flag — it is a disqualifier.
The next concrete action at each branch:
Project outsourcing: Write the contractual specification and IP assignment terms before you contact vendors. If you cannot write the spec, the model is wrong.
In-house hiring: Start recruiting immediately and budget the throughput lag explicitly into your milestone timeline. Do not show your board a feature date that assumes full productivity before month five.
Dedicated partner: Prepare the vetting questions above. Run them against every candidate. Ask for architectural decision records before a demo or a rate discussion.
Frequently Asked Questions
How much does it cost to outsource software development in 2026?
The true cost of outsourcing software development in 2026 depends heavily on model, region, and engagement structure. Project-based outsourcing typically runs $65,000 to $130,000 for a 12-month mid-level developer equivalent when you factor in management overhead, rework cycles, and onboarding drag — not just base labor. Dedicated nearshore teams (Mexico, Colombia, Argentina) cost $55,000 to $100,000 fully-loaded for the same period. Eastern European dedicated developers (Poland, Romania) run $55,000 to $90,000 in base labor alone. Hourly rate covers only 50 to 60 percent of the true engagement cost; any proposal that leads with hourly rate is omitting the number you actually need.
Is outsourcing software development worth it for startups?
It depends on stage, runway, and what you are outsourcing. Outsourcing software development for startups is most worth it when: your runway is under 18 months and time-to-first-feature is under 90 days (eliminating in-house hiring on timeline grounds), the work is core IP requiring iterative discovery (eliminating fixed-scope project outsourcing), and you have internal technical leadership capable of providing architectural direction at least 20 percent of the time. Under those conditions, a dedicated nearshore team at one-third the cost of equivalent in-house hires can be the right trade. It is not worth it when IP assignment is ambiguous, team composition is unprotected, or the work is pre-PMF discovery being handed to a fixed-scope vendor.
What is the difference between dedicated team and project outsourcing?
Project outsourcing uses a fixed-scope contract: you define the deliverable, the vendor builds it, the engagement ends. Incentives optimize for clean closure, not your ability to extend the codebase. Dedicated team outsourcing assigns a specific team to your account for a defined period, with continuity across sprints and (in genuine implementations) architectural accountability. The practical difference: project outsourcing works for well-specified, peripheral work; dedicated teams work for iterative, core-product development where requirement evolution is expected. The risk with dedicated teams is that "dedicated" is often verbal rather than contractual — team composition rotates when the vendor has a higher-margin need.
How do I vet an outsourcing partner for my startup?
Ask for architectural decision records (ADRs) from a prior engagement of comparable complexity. Request the ratio of senior to mid-level developers on the proposed team and confirm it is contractually protected. Ask how they handle incomplete or contradictory specs — vendors describe escalation, partners describe resolution. Confirm documentation standards are enforced during the engagement, not written at handoff. Verify IP assignment is unambiguous and code escrow is documented before signing. Any one of these absent is a disqualifier, not a negotiating point.
When is in-house hiring better than outsourcing for a Series A startup?
In-house hiring outperforms outsourcing when runway exceeds 18 months, time-to-first-feature tolerance exceeds 90 days, the work is foundational IP you will build on for three or more years, and your hiring network can source senior talent within 30 days. The in-house model compounds over time — institutional knowledge, architectural alignment, and team culture coherence are structural advantages that no outsourced model replicates at equivalent cost. The AI augmentation variable has also changed the math: a three- to four-person in-house team with a mature Copilot or Cursor toolchain can now approach the output historically associated with eight to ten outsourced developers, under the right codebase conditions.
What are the biggest risks of outsourcing software development in 2026?
The three primary risks are: (1) IP ownership ambiguity — if assignment language requires legal scrutiny to interpret, it is not unambiguous; negotiate before a line of code is written. (2) Team composition rotation — dedicated teams that are not contractually protected will rotate developers when the vendor has a higher-margin need; you learn this at month three when your best developer disappears. (3) Architectural accountability gaps — no one on the vendor side holds the full system picture, so edge cases and wrong design assumptions get routed back to you, consuming internal technical leadership time in ways that compound across the engagement.
One Honest Acknowledgment Before You Decide
The framework tells you which model fits your context. It does not tell you whether the specific partner in front of you will execute it well. The failure rate data — 17 to 31 percent outright failure, 45 percent overrun rate — is not evenly distributed across all vendors. Some of it is selection. Some of it is engagement structure. A meaningful portion is the contractual decisions made on day one.
The framework is a map of the territory. The vetting questions are how you evaluate the specific road.
You now have enough to make this decision with your eyes open — which is a different thing from having permission to make it, and a far more useful thing. The question is no longer which model is right in theory. It is which one is right for where you actually are, and whether the partner in front of you can be held to the standards that make it work.
---
# Long-Term Maintainability When AI Writes Half Your Codebase: 5 Metrics Product Owners Should Track
Source: https://smicolon.com/blog/long-term-maintainability-when-ai-writes-half-your-codebase-5-metrics-product-ow
Updated: 2026-09-03T02:01:24.966Z
Your team is shipping faster than it has in years. Sprint dashboards are green. Stakeholders like the pace.
Long-Term Maintainability When AI Writes Half Your Codebase: 5 Metrics Product Owners Should Track
Your team is shipping faster than it has in years. Sprint dashboards are green. Stakeholders like the pace.
Now picture the same product twelve months from now, when a small change takes three sprints and every bug fix creates two more.
That gap is what long-term maintainability measures: the cost, speed, and safety of changing your code later. It is not a code-quality vanity score. It decides how fast your business can answer a customer, launch a product, or change direction without spending the roadmap on rework.
AI coding is a genuine advantage. But output tells only half the story. You also need to know whether AI-generated code maintainability is improving or whether your codebase is becoming harder and more expensive to own.
Below are five core metrics and the exact question to ask your engineering team for each one. This is a practical measurement guide for product leaders focused on long-term AI code maintenance.
The Speed Illusion: Why AI-Generated Code Looks Like a Win Until It Isn't
AI coding tools shorten the path from idea to working code. That gain is easy to see. More tickets close, prototypes arrive sooner, and nobody starts from a blank file.
The long-term cost is harder to see.
A codebase can depreciate quietly while the delivery dashboard stays healthy. This challenge is closely linked to the AI verification gap, where output velocity outpaces review capacity. The warning signs surface months later: estimates grow, developers avoid certain modules, and a change described as small turns into a week of investigation and regression fixes.
GitClear's research puts numbers on the tension: refactoring fell 70% and long-term legacy maintenance fell 74% compared with 2022. More code is being produced while less effort goes into simplifying and caring for what already exists. The same analysis reports higher duplication, weaker connectivity between new and existing code, and elevated churn.
The message is not that AI-written code is bad. It is that feature volume alone cannot tell you whether AI code maintenance will stay affordable.
So long-term maintainability belongs beside velocity, cycle time, and roadmap progress in your product reporting. Engineering can calculate the numbers. Product leadership should own the business conversation around them, because maintainability always resurfaces as a product decision:
Can we answer a major customer request this quarter?
Can a new developer work safely in this area?
Why did the estimate for a familiar change double?
Are our AI productivity gains surviving once rework is counted?
Once those questions reach a roadmap meeting, maintainability is already a business problem.
What Is the Impact of AI-Generated Code on Long-Term Maintainability?
The impact of AI-generated code on long-term maintainability is a rise in structural technical debt—specifically higher code duplication (up 81%) and lower code connectivity (down 35%). While AI accelerates initial writing speed, it frequently compromises long-term code health by generating redundant logic and isolated components that increase future rework costs.
More duplication means paying repeatedly for the same future change. If one pricing rule lives in five places, a developer has to find, update, test, and review all five. Miss one copy and customers get inconsistent behavior.
Lower connectivity means new code sits apart from the system around it. Instead of reusing established components, it invents a second way to solve the same problem. Debugging, onboarding, and every future change get more expensive.
That cost can swallow the productivity gain that justified AI adoption in the first place. IBM's guidance on technical debt reports that ignoring technical debt can cut AI return on investment by 18–29%, while fully accounting for it in AI business cases correlates with 29% higher ROI.
Volume also creates review pressure. When newly added code is revised days after it lands, some of that output is not surviving contact with the real system. If review capacity and maintenance work do not rise with production, the apparent gain turns into rework. Knowing how to run an AI code audit helps teams catch these architectural issues before tech debt compounds.
None of this is an argument against AI coding. It is an argument for measuring what AI coding does to a valuable business asset over time. The scorecard below makes that visible before it reaches your delivery dates.
Metric 1: Code Churn — How Much New Code Gets Rewritten Right Away
What it costs you: The team looks fast this sprint, then spends the next three sprints correcting or replacing its own recent work.
Code churn is the share of newly written code that is significantly revised or deleted shortly after it is created. High churn usually means the first solution did not fit the system, the requirements, or the existing architecture.
Some churn is healthy. Product development involves learning, and early feedback should change code. The warning sign is a sustained rise after AI coding adoption, especially when scope and team composition have stayed broadly stable.
The question to ask your engineering team"What share of the code we wrote in the last two to four weeks has already been significantly changed or removed, and which way is that trend moving?"
Ask for a trend line, not a single percentage. Compare churn before and after AI adoption, or compare product areas with different levels of AI-assisted development.
Then connect the trend to delivery. Is the rework concentrated in rushed features? Does it cluster in one part of the application? Are the same tickets reopening?
There is no universal threshold. Your own baseline matters more than someone else's benchmark. If churn rises while reported productivity also rises, find out whether rework is quietly eating the gain.
Metric 2: Duplication — The Copy-Paste Tax on Every Future Change
What it costs you: When the same logic lives in five places, every future fix means five changes, five tests, and five chances to miss one.
Duplication happens when identical or near-identical blocks of code appear across a system instead of sharing one reusable implementation. GitClear's reported 81% rise in duplicated blocks suggests AI assistants often write a plausible new answer rather than reuse the logic that already exists.
Picture five copies of the same contract. Updating one does not update the rest. The versions drift apart, and nobody notices until someone relies on the wrong one.
In software, that shows up as inconsistent prices, permissions, calculations, or customer journeys.
The question to ask your engineering team"How is our duplication percentage moving month by month, and can we separate AI-assisted code from human-written code where that is practical?"
The split is useful, but it should never become a reporting project. The main goal is to see whether duplication is growing and which product areas account for most of the increase.
Not every repeated line is a crisis. Some repetition is clearer and safer than a tangled shared abstraction. Watch for a rising trend in repeated business logic: the rules that change when your product, pricing, or operations change.
That trend tells you whether today's output is multiplying tomorrow's work.
Metric 3: Time-to-Change — The Truest Test of Long-Term Maintainability
What it costs you: Estimates grow even for changes that look familiar and small.
Time-to-change measures how long it takes to go from deciding on a modification to releasing it safely in a specific part of the product. It covers implementation, review, testing, and the work needed to avoid breaking what already works.
This is the metric closest to business value. A maintainable system keeps common changes cheap. An unmaintainable one wraps every request in investigation, dependencies, and regression risk.
The question to ask your engineering team"How long do similar-sized changes take now compared with six months ago, and which product areas are slowing down fastest?"
Compare like with like. A new payment integration is not a text change. Group recurring work instead: adding a report field, changing a pricing rule, adjusting permissions, extending an existing workflow.
Watch the estimates as well as the delivery time. If experienced developers keep inflating estimates for small tasks in one area, they are pricing in complexity you cannot see.
Rising time-to-change usually appears before customers notice anything. The product still works; the team just needs longer to change it. Treat that as an early warning light, not an engineering complaint.
It is also why cutting development corners rarely stays cheap. Deferred structural work comes back as slower product execution.
Metrics 4 and 5: Review Lag and Safe Editability — Can Humans Still Keep Up?
These two metrics show whether your team can absorb AI-assisted output today and still own it tomorrow.
Metric 4: Review Lag
What it costs you: Work waits longer for approval, or reviewers wave it through to keep the queue moving.
Review lag is the time between a change becoming ready for review and getting a meaningful response. As AI produces more code in larger batches, review capacity becomes the bottleneck.
Fast approval is not automatically good news. If change volume climbs while review time drops sharply, review depth is shrinking. The goal is not faster sign-off. It is meaningful review that keeps up without a growing queue.
The question to ask your engineering team"How long do changes wait for review, how large are they getting, and are we still reviewing them with the same depth?"
Track median review lag, the size of changes in the queue, and how often a change needs another round after feedback. Review lag is a leading indicator: it shows whether production volume is outrunning your team's ability to understand what enters the codebase.
Metric 5: Safe Editability in Six Months
What it costs you: Only the original author can safely touch the code, so every resignation and routine maintenance ticket becomes a delivery risk.
Safe editability asks a simple question: can a developer who did not write this code change it six months from now without breaking something?
It is forward-looking, so no single number captures it. Use practical proxies:
Tests cover the important behavior in newly added code.
Documentation explains unusual decisions and dependencies.
Developers outside the original feature team can make changes successfully.
Changes to older AI-generated areas do not keep causing regressions.
The question to ask your engineering team"Could someone who did not write this code safely change it in six months, and what evidence gives us that confidence?"
Ask the team to review a small sample of recently completed features each month. Note whether the code has clear ownership, useful tests, the documentation it needs, and a track record of safe modification.
Review lag is the leading indicator. Safe editability is the lagging outcome. When review gets rushed, future developers inherit code that fewer and fewer people understand.
Building Your Long-Term Maintainability Scorecard: A 30-Day Starting Plan
You do not need a re-platforming project or an executive dashboard. You need one monthly scorecard, reviewed next to your delivery metrics.
Metric | Business Question | Direction to Watch
Code Churn | Are we paying to rewrite recent work? | Rising after AI adoption
Duplication | Is every future change spreading across more places? | Sustained growth
Time-to-Change | Are familiar product changes getting slower? | Longer delivery for comparable work
Review Lag | Can human review keep up with output? | Longer queues, or suspiciously shallow reviews
Safe Editability | Can another developer safely own this code later? | More regressions, missing context, concentrated ownership
Week 1: Set Churn and Duplication Baselines
Use the repository data your engineering team already has. Record current churn and duplication, then pull whatever history is available. Do not wait for perfect data. A usable baseline today is enough to start tracking direction.
Week 2: Start Measuring Review Lag
Measure how long changes wait for a first meaningful review and for final approval. Record change size alongside it, so nobody chases better numbers by splitting or rubber-stamping work.
Weeks 3 and 4: Benchmark Change Speed and Editability
Pick a few recurring types of product change and document their recent time-to-change. Then set up a monthly safe-editability review on a small sample of completed work.
Evaluating automated code maintenance strategies alongside aligning AI-generated code with engineering standards provides a complete framework for sustainable delivery.
Keep the conversation constructive. These metrics create shared visibility, not surveillance. Never use churn or review time to rank individual developers. AI-generated code maintainability is a system outcome shaped by architecture, workload, incentives, and delivery pressure.
Review the Scorecard Monthly
Look for relationships between the measures. Rising duplication often precedes longer time-to-change. Growing review lag tends to show up later as weaker safe editability. High churn explains why apparent output is not turning into roadmap progress.
Trends matter more than thresholds. The point is to catch degradation early, see where it lives, and price it into planning.
That is how the scorecard connects to IBM's findings. If ignoring technical debt can cut AI ROI by 18–29%, maintenance cannot stay an unpriced engineering concern. These five signals give product owners a practical way to put future ownership costs into the AI business case.
Speed and Sustainability Aren't a Trade-Off — If You Measure Both
AI coding helps teams explore, build, and ship faster. That advantage lasts when the team tracks the condition of the codebase as deliberately as it tracks output.
The five-metric scorecard keeps the discipline simple:
Code churn shows how much recent work is being rewritten.
Duplication reveals whether future changes are multiplying.
Time-to-change measures the real cost of adapting your product.
Review lag shows whether human understanding is keeping pace.
Safe editability tests whether the code will still be workable in six months.
Together they answer the question velocity cannot: are we shipping faster while protecting our ability to keep shipping?
That makes long-term maintainability a business metric, not an engineering detail. Product owners who track it protect roadmap speed, development spend, and AI ROI.
Smicolon works as a dedicated technology partner for companies building and scaling digital products. We design for long-term maintainability from day one through sound architecture, disciplined review, and clear measurement, instead of waiting for hidden costs to become a delivery crisis.
Want to know what your five metrics look like right now? Book a Discovery Call and we will walk through your codebase health and build a maintainability scorecard around your product, team, and growth plans.
---
# How AI Helps With Code Reliability When Your Product Changes Faster Than Ops Can Keep Up
Source: https://smicolon.com/blog/how-ai-helps-with-code-reliability-when-your-product-changes-faster-than-ops-can
Updated: 2026-09-05T02:00:45.455Z
> **Key Takeaway:** As AI acceleration increases deployment velocity, traditional operational habits fail. **AI SRE** (Site Reliability Engineering) improves **AI code reliability** by using AI anomal
How AI Helps With Code Reliability When Production Changes Faster Than Your Team Can TrackKey Takeaway: As AI acceleration increases deployment velocity, traditional operational habits fail. AI SRE (Site Reliability Engineering) improves AI code reliability by using AI anomaly detection to spot regressions, reducing Mean Time to Mitigate (MTTM) by compressing time-to-context, and enforcing governed, automated remediation.
The AI Code Avalanche: Why Reliability Suddenly Belongs to Everyone
Your team shipped four times yesterday. Two of those releases touched services nobody has looked at closely in months. At 3 a.m., checkout starts failing for customers on one payment method — and the main dashboard still looks green.
That gap between how fast code ships and how fast people understand production is why engineering leaders are asking how AI helps with code reliability.
Coding assistants now produce features, tests, integrations, and infrastructure changes at unprecedented speed. Every one of those releases reshapes production. Dependencies shift, services interact in new ways, and dashboards drift out of date. The mental model your operations team built last month may already be obsolete.
InfoWorld calls this the "AI code avalanche": production changes faster than the people responsible for reliability can understand it. The same article cites a 2026 CloudBees survey in which 81% of technology leaders reported more production issues tied to AI-generated code.
AI-generated code is not inherently broken. Higher release velocity simply creates more surface area for failure. Traditional operations habits — checking dashboards by hand, grepping logs, comparing deploy timelines, and asking who remembers a service — do not scale with unlimited change.
Each unwatched release adds incremental risk. Eventually, a subtle config change, a dependency conflict, or an unexpected traffic pattern reaches customers before anyone knows what happened.
So how does AI help with code reliability? In three practical ways:
It spots unusual behavior across complex operational data.
It assembles incident context and drafts likely root-cause explanations.
It carries out carefully governed remediation inside safe boundaries.
The result is earlier anomaly detection and significantly less time spent stabilizing production.
This discipline has a name: AI SRE. SRE stands for site reliability engineering — the practices that keep software available, fast, and safe after it ships. Implementing code reliability AI allows engineering teams to keep pace with rapid deployment cycles without sacrificing system health.
The same AI wave feeding the avalanche can help you manage it. But only with discipline. AI SRE works when it widens human awareness first, supports human decisions second, and acts on its own only inside proven guardrails.
What AI SRE Actually Means — and What It Doesn't
AI SRE applies machine learning models and intelligent agents to monitoring, incident investigation, root-cause analysis, and remediation in production. It helps reliability teams answer four critical questions faster:
What changed?
What is behaving differently?
What is the most likely cause?
What safe action reduces customer impact?
One boundary worth setting early: this article is about post-deployment production reliability. It is not about code review, quality audits, or verification before a pull request merges. Those practices matter — addressing the verification gap in AI-generated code deserves its own attention — but production is a fundamentally different challenge. Even well-reviewed code fails when it meets live traffic, real-world dependencies, shifting data, and distributed infrastructure.
To prevent post-deployment drift, engineering organizations are also focusing on aligning AI-generated code with standards before deployment.
The industry is moving from manual incident response toward agentic monitoring, automated context gathering, hypothesis drafting, and safe actuation. Rootly's AI SRE concepts center on shortening the path from an alert to useful context, while Traversal's AI SRE explainer describes how AI investigates incidents across complex systems.
None of that means handing production over to an unsupervised agent.
Effective AI code reliability starts with assistance. The system watches operational signals, summarizes evidence, and proposes likely causes. Engineers validate the evidence and decide what happens next.
As confidence grows, teams can authorize specific actions under strict conditions. Autonomous self-healing belongs to mature teams with well-understood failure modes — and even then, only for tightly bounded cases.
The goal is not to remove operators. It is to stop skilled operators from spending the first minutes of every incident collecting information a machine can gather faster.
How AI Helps With Code Reliability Through Anomaly Detection
Traditional monitoring leans on static thresholds: CPU passes a set percentage, errors cross a limit, or response time rises above an agreed level. Those rules are easy to reason about, but they break down in systems whose normal behavior shifts by time of day, customer segment, release, or workload.
AI anomaly detection looks for deviations from expected patterns across metrics, logs, and traces:
Metrics are quantitative numbers: error rates, latency, memory consumption.
Logs are timestamped event records from applications and infrastructure.
Traces track a single user request as it traverses microservices.
Together, these signals form observability — your ability to infer the internal state of a system based on its external outputs.
Picture a team shipping several changes in one day. Shortly after the third deploy, checkout latency climbs for customers using one payment method. Overall latency stays under the alert threshold, so the main dashboard looks fine.
An AI-assisted system compares deploy timing against trace patterns, payment-service logs, and segment-level latency. It flags the behavior as anomalous even though no global threshold was crossed. The alert is specific: this customer journey changed right after that release.
Better signal quality also cuts alert fatigue. Instead of paging engineers for noisy metrics, the system groups related signals into one high-confidence incident. Result: fewer interruptions and less pager burnout.
What AI cannot do is rescue missing or unreliable telemetry. Before anomaly detection pays off, you need consistent logging, meaningful metrics, distributed tracing, synchronized timestamps, deploy markers, and a clear baseline of healthy system behavior. Poor data gives AI more ways to be confidently wrong; strong observability gives it verifiable evidence.
Incident Support: Winning Back the First 20 Minutes
An alert fires at 3 a.m. The on-call engineer opens one dashboard, then another. Searches logs. Checks recent deploys. Reads an old incident ticket. Messages the developer who knows the service.
Twenty minutes gone before anyone has a credible hypothesis.
That is the time-to-context problem: responders spend the opening stretch of an incident hunting across dashboards, deploy timelines, tickets, and tribal knowledge instead of mitigating. AI SRE compresses that search by collecting the evidence and presenting it in one place.
It lists recent changes, summarizes unusual signals, maps affected dependencies, pulls up similar past incidents, and drafts possible root causes. The engineer opens a structured briefing instead of an empty query box.
What the Published Results Show
Google SRE reports that AI-generated incident hypotheses reduced Mean Time to Mitigate (MTTM) by 10%. MTTM is the average time required to reduce or stop an incident's impact on customers.
Google also reports that Investigation Dashboards surfaced 195% more findings and cut MTTM by roughly 44% for supported incidents. These dashboards aggregate relevant operational evidence into one incident-specific view so responders investigate from a unified picture.
AI does not always find the definitive root cause instantly, nor does it need to. The value lies in putting relevant evidence in front of responders sooner.
Comparison: Manual vs. AI-Assisted Incident Response
Incident Step | Manual Response | AI-Assisted Response
Detect the issue | Fixed alert fires once a static threshold is crossed | Anomaly detection spots an unusual pattern across related signals
Find recent changes | Responder searches deploy tools and asks the team | Incident summary lists relevant deploys and config changes
Understand impact | Engineers manually inspect several dashboards | System groups affected services, journeys, and dependencies
Form a hypothesis | Responder correlates evidence by hand | AI drafts ranked hypotheses with supporting evidence
Take action | Team decides and manually executes fix | Human approves suggested action or follows a documented rollback path
Back to the 3 a.m. scenario: with AI assistance, the responder sees that errors began six minutes after a deploy, affect one checkout path, and resemble a previous dependency timeout. The system suggests a connection-pool setting may be involved and links that hypothesis directly to supporting logs and traces.
The human still checks it. Maybe the deploy is unrelated; maybe the evidence points elsewhere. AI assembles the case; the engineer applies judgment. That split protects reliability and prevents responder overwhelm.
The Guardrails: How to Let AI Act Without Losing Control
The idea of an AI agent modifying production should make any engineering leader cautious. Autonomous remediation done poorly is genuinely dangerous. An agent can misread a symptom, exacerbate an outage, obscure the root cause, or execute harmful actions in a loop.
The solution is not to avoid AI, but to grant authority progressively:
Read-only assistance: AI observes, summarizes, and recommends.
Assisted actions: AI prepares an action; a human approves it.
Self-healing: AI executes specific remediations inside predefined boundaries.
Never skip stages. Incorporating proper human checkpoints in agentic workflows is critical whether agents are writing code or managing infrastructure.
Google's reliability guidance describes a Safety Trifecta for production AI:
Transparency: Operators can inspect what the AI observed, what it proposes, and why.
Real-time risk evaluation: The system checks current conditions before acting rather than assuming an action is always safe.
Progressive authorization: The AI earns narrow permissions as its performance becomes measurable and trusted.
Non-Negotiable Controls for Autonomous Remediation
Any AI allowed to act in production requires:
Role-Based Access Control (RBAC): Permissions tied strictly to explicit roles and scopes.
Approval Requirements: Mandatory human sign-off for higher-risk actions.
Audit Trails: Comprehensive records of evidence, recommendations, approvals, and execution logs.
Stop Conditions: Automatic kill-switches that halt automation when uncertainty rises.
Rollback Paths: Fully tested mechanisms to reverse every automated change.
Every action should be bounded, reversible, measurable, and governed. Restarting an unhealthy stateless pod is a reasonable automated action; altering a shared database configuration across production is a vastly higher risk class.
Guardrails make adoption possible. Engineers accept AI recommendations when they can inspect the evidence, predict the action, and undo it safely. Further along the maturity curve, platforms like Harness AI SRE enable fix-forward remediation, applying controlled corrections that restore service while preserving valid changes.
A Four-Stage Roadmap for Adopting Code Reliability AI
AI SRE should grow alongside your operational maturity. A staged rollout lets you prove value, contain risk, and build team trust before expanding permissions.
1. Strengthen the Observability Foundation
Make operational evidence consistent and accessible. Review logs, metrics, traces, service ownership, deploy markers, incident records, and dependency maps. Confirm that a responder can trace a customer-facing symptom back to the services and changes behind it.
Measure success with: Data coverage, signal consistency, alert usefulness, and baseline time-to-context.
2. Add Read-Only AI Assistance
Deploy AI for anomaly detection, incident summaries, deploy correlation, past incident retrieval, and hypothesis drafting. Grant zero production write access.
Measure success with: Time-to-context, alert precision, useful findings, hypothesis accuracy, and reduction in MTTM.
3. Introduce Assisted Actions
Once the team trusts the system's context, allow it to prepare selected actions for human approval (e.g., drafting a rollback or isolating an unhealthy node). RBAC limits what it can touch, and full audit logs record every step.
Measure success with: Approval rates, action success rates, rollback frequency, and human decision latency.
4. Graduate Proven Cases to Governed Self-Healing
Authorize autonomous remediation only for repetitive, well-understood incidents with safe, tested responses. Define narrow scopes, clear stop conditions, and strict escalation rules.
Measure success with: Mitigation speed, automated remediation success rate, customer impact reduction, and policy adherence.
Most engineering teams should remain in Stages 1–3 for a substantial period. Restraint builds trust and keeps automated capabilities from becoming your next operational risk.
Keep Shipping Fast Without Breaking Trust
AI-accelerated development has redefined reliability. When code reaches production at high velocity, static dashboards and manual log correlation no longer scale.
AI-assisted reliability provides a practical path forward: anomaly detection surfaces deviations early, incident context generation eliminates wasted investigation time, and governed remediation enables safe operational response.
Velocity and stability do not have to be opposing forces. When humans retain control and permissions expand step-by-step, AI SRE bridges the gap between rapid software delivery and production resilience.
Smicolon helps growing companies build reliable digital products and modernize operational practices for AI-accelerated development — assessing observability gaps, refining incident response, and establishing guardrails for production stability.
To evaluate your current reliability posture and identify where your team can save critical incident response time, book a discovery call with Smicolon.
---
# The Agentic AI Lifecycle: Why Most Pilots Never Become Owned Production Systems
Source: https://smicolon.com/blog/the-agentic-ai-lifecycle-why-most-pilots-never-become-owned-production-systems
Updated: 2026-09-09T02:00:26.513Z
The demo worked. The agent read the request, pulled the right records, completed the task, and produced a clean result. Then someone in the room asked how fast you could roll it out everywhere.
The Agentic AI Lifecycle: Why Most Pilots Never Become Owned Production Systems
The demo worked. The agent read the request, pulled the right records, completed the task, and produced a clean result. Then someone in the room asked how fast you could roll it out everywhere.
That question is where the agentic AI lifecycle usually goes off course. A convincing pilot proves the model can reason, but it says almost nothing about whether your business can run, govern, and pay for that agent over its operational lifespan.
The agentic AI lifecycle is the end-to-end framework for moving autonomous AI agents from proof-of-concept pilots into governed, owned, and cost-effective production systems. Without a structured lifecycle approach, organizations risk high rates of agentic AI project failure, where promising AI demos stall due to missing integrations, unclear technical ownership, and unmanaged operating costs.
What Is an Agentic AI Workflow?
If you are fielding the question "what is agentic AI workflow?" from your board, the direct definition is: An agentic AI workflow is an automated software process where AI agents independently plan, execute, use tools, and validate multi-step tasks to achieve a specific business objective with contextual human oversight.
Traditional automation and robotic process automation (RPA) follow static, fixed rules — when an event happens, perform a deterministic action. In contrast, agentic workflows in AI interpret objectives dynamically, select appropriate tools, analyze intermediate outcomes, and adapt subsequent steps based on context.
Traditional Automation: Copies a newly approved customer record into a CRM system automatically.
Agentic AI Workflow: Examines the record, identifies missing compliance fields, retrieves supporting PDF documents from storage, updates multiple backend systems, flags unusual contract terms, and determines whether onboarding can proceed.
That flexibility creates massive business value, but it expands the operating surface. An agent requires precise context, RBAC security permissions, reliable API integrations, defined guardrails, and safe fallback paths when it encounters edge cases. Smicolon's plain-English agentic workflow guide covers these core technical fundamentals.
The Pilot Trap: Why Impressive Demos Cause Agentic AI Project Failure
After a successful internal demo, slowing down feels like losing momentum. Competitors are publishing AI updates, your engineering team has invested weeks, and leadership wants to report progress to the board. However, rushing an unowned agent into production creates substantial operational liability.
Research highlights the scale of this deployment challenge: Gartner predicts that more than 40% of agentic AI projects will be canceled by the end of 2027, citing escalating costs, unclear business value, and inadequate risk controls.
Primary drivers of agentic AI project failure rarely trace back to model reasoning limits. Instead, failures stem from:
Unscoped Workflows: Testing happy-path prompts while ignoring real-world exceptions.
Brittle Integrations: Connecting agents via ad-hoc scripts rather than enterprise APIs.
Ambiguous Ownership: Failing to assign ongoing maintenance and SLA accountability.
Uncapped Cost Models: Ignoring long-term token usage, monitoring, and human review costs.
Founders can navigate these risks by structuring deployment around the four distinct stages of the agentic AI lifecycle:
Pilot: Prove an agent can complete a narrowly defined, isolated task.
Governed Production: Integrate the agent into live systems with audit logs, security boundaries, and escalation paths.
Ownership: Assign explicit technical responsibility for maintenance, evaluation, and decision rights.
Cost Model: Validate that recurring efficiency gains exceed total lifetime operating expenses.
Stage 1 of the Agentic AI Lifecycle — Pilot: Beyond the Clean Happy Path
Pilots simplify reality by design. Teams select narrow test cases, sanitize input data, grant elevated permissions, and monitor every run. When outputs drift, engineers manually re-prompt the model or correct data downstream.
Production environments remove every one of those safeguards. Industry analyses from Forbes describe the operational details that separate successful demos from failed deployments: missing database fields, duplicate records, legacy workflows, and revoked API permissions.
For example, a customer support agent tested against curated knowledge bases faces conflicting contract records, outdated return policies, and unreadable attachments in live production. Without strict boundaries, context-starved agents risk hallucinating plausible answers and executing unauthorized downstream system calls.
Rigorous Pilot Criteria
To validate a pilot for production readiness, test under adverse conditions:
Incomplete, duplicated, or contradictory data inputs.
Unresponsive APIs, permission revocations, and network timeouts.
Explicit evaluation of whether agents stop, escalate, or hallucinate when uncertain.
Clear business KPIs evaluating error rates against manual review reduction.
This mirrors lean engineering practices: focus on core viability rather than superficial features. Smicolon's framework for building a functional MVP provides detailed guidance on maintaining essential capabilities while constraining scope.
Stage 2 of the Agentic AI Lifecycle — Governed Production: Integration and Controls
Governed production begins when an agent interacts with live enterprise systems, customer data, production databases, or financial transactions. Beyond functional accuracy, production systems require observability, security, recoverability, and compliance.
In modern engineering, CIO Magazine highlights agentic AI as an emerging first-pass executor across the software development lifecycle — planning, generating code, validating, and reviewing pull requests.
Connecting autonomous agents into production environments demands deep integration across core architecture:
Legacy Monoliths: Interfacing safely with core business logic and transactional databases.
CI/CD Pipelines: Automated build, test, and deployment environments.
Identity & Access Management (IAM): Least-privilege roles restricting agent tool permissions.
Observability Suites: Structured logging, step-level tracing, and audit logs.
Governance and Checkpoint Design
Governance must be built directly into agentic workflows in AI from inception. High-stakes actions — modifying production code, authorizing funds, or altering customer contracts — require mandatory human-in-the-loop checkpoints. Lightweight tasks like generating internal summaries can use asynchronous human reviews.
Implementing structured human checkpoint patterns allows technical leaders to enforce safety thresholds without sacrificing operational speed. Additionally, open standards like Model Context Protocol (MCP) streamline tool connectivity and multi-vendor interoperability while enforcing consistent permission boundaries.
Stage 3 of the Agentic AI Lifecycle — Ownership: Assigning Operational Accountability
Unowned production software decays quickly. APIs update, schemas change, model vendor behavior shifts, and prompt performance drifts over time. Without explicit ownership, an initial deployment Becomes a compliance risk.
Recent benchmarks from BCG report that 60% of technology stack and agentic deployment decisions sit with CIOs or CTOs. Technical leadership is critical because maintaining agentic systems requires ongoing engineering rigor.
Operating Models for Production Agents
Growth-stage organizations generally implement one of two technical ownership frameworks:
Ownership Model | Primary Responsibilities | Ideal Use Case
Internal Operational Ownership | Dedicated in-house team managing monitoring, prompt tuning, API integration, and SLAs. | Core proprietary workflows linked to direct competitive advantage.
Partner-Held Operational Ownership | External specialized engineering partner managing infrastructure, security, monitoring, and integration health. | Teams lacking internal AI engineering capacity or without the appetite for the operational overhead.
Selecting the right model depends on current internal capacity and long-term strategic focus. Smicolon's development ownership framework helps founders evaluate operational trade-offs between in-house management and external engineering partnerships.
Stage 4 of the Agentic AI Lifecycle — The Cost Model: Calculating Lifetime TCO
Model API tokens represent Only a fraction of total cost of ownership (TCO). A comprehensive financial model for production agents must account for:
Initial Engineering: Workflow scoping, API integration, guardrail implementation, and testing.
Data Sanitization: Cleaning legacy schemas, setting up vector indices, and managing permissions.
Infrastructure & Tooling: Vector databases, observability platforms, and evaluation suites.
Recurring Maintenance: API maintenance, prompt optimization, model upgrades, and incident management.
Human Oversight: Labor costs associated with manual reviews, escalation handling, and auditing.
When organizations fail to model fully loaded operating costs against quantifiable outcomes, recurring expenses quickly overwhelm perceived benefits. Production authorization should occur only after defining concrete workflow boundaries, measurable output metrics, and conservative run-cost estimates.
Go/No-Go Decision Framework for the Agentic AI Lifecycle
Evaluate this readiness checklist prior to transitioning an agentic workflow into live production:
1. Workflow Scope & Validation
[ ] The agent solves a tightly bounded, specific process with defined inputs and outputs.
[ ] Pilot testing verified agent resilience against edge cases, missing data, and system timeouts.
[ ] Target KPIs measure concrete business metrics (e.g., throughput, error rate reduction) rather than raw output quality.
2. Integration & Security Architecture
[ ] The agent operates under strict least-privilege security permissions.
[ ] Integration paths for legacy databases, CI/CD pipelines, and internal tools are securely established.
[ ] Graceful fallback mechanisms handle API downtime or service revocation.
3. Operational Governance & Observability
[ ] Human-in-the-loop checkpoints gate high-risk actions (e.g., code deployment, financial transactions).
[ ] Step-level logging and audit trails record all model reasoning steps and tool execution calls.
[ ] Rollback procedures and emergency kill-switches are fully tested.
4. Ownership & Financial Viability
[ ] A named technical role or partner holds explicit SLA accountability and incident response duties.
[ ] Fully loaded TCO includes recurring infrastructure, token usage, maintenance, and review labor.
[ ] The business case remains cash-positive under conservative efficiency gains and high-cost scenarios.
Moving from AI Pilot to Production with Smicolon
Navigating the agentic AI lifecycle requires engineering discipline, system integration, governance design, and structured cost control.
Smicolon collaborates with growing companies to build owned production systems: custom workflow development, legacy system integration, enterprise guardrails, and long-term operational maintenance. You can deploy reliable agentic systems without diverting your core engineering teams from primary product goals.
Evaluate your AI initiatives before technical debt and unmanaged risks accumulate. Bring a target workflow to a strategic session, and we will analyze its lifecycle maturity, highlight integration gaps, and outline a production roadmap.
Book a discovery call to map your agentic AI lifecycle
---
# Agent UX: How to Design Interfaces When Your Product Acts, Not Just Displays
Source: https://smicolon.com/blog/agent-ux-how-to-design-interfaces-when-your-product-acts-not-just-displays
Updated: 2026-09-12T02:00:16.070Z
**Agent UX** is the practice of designing **agentic user interfaces** for software that takes autonomous action rather than just displaying information. Unlike traditional request-response interfaces,
Agent UX: How to Design Interfaces When Your Product Acts, Not Just Displays
Quick Summary: What Is Agent UX?
Agent UX is the practice of designing agentic user interfaces for software that takes autonomous action rather than just displaying information. Unlike traditional request-response interfaces, effective UI design for AI agents provides transparency, control, proactive status updates, and structured recovery paths so users can supervise and trust autonomous workflows.
The Interface Just Changed Jobs: From Showing Information to Taking Action
Software used to wait for permission. Now it acts.
For decades, an interface had one job: show information, present options, wait for a click. That contract is gone.
Today's products book meetings, resolve support tickets, update customer records, approve routine requests, and move money on a user's behalf. The interface no longer sits between a person and a database. It sits between a person and software pursuing a multi-step goal across complex systems.
That shift makes agentic user interfaces — screens built for software that acts on its own — a defining product pattern for 2026. Figma's 2026 trends outlook flags their rise, along with the obvious trap: dropping a prompt box into an existing product and calling it an agent experience.
The window to get this right is narrow. Gartner projects that task-specific AI agents will appear in roughly 40% of enterprise applications by 2026, up from under 5% in 2025. That is a steep curve, and UI design for AI agents is about to become a baseline expectation rather than a niche advantage.
So the importance of UI/UX in business success now reaches far past visual quality and ease of use. Agent UX decides whether people trust autonomous features enough to hand over real work — or switch them off after one confusing action.
That decision governs the whole AI investment. An agent may be capable of saving hours, but if users supervise every step, recheck every result, or route around it, the savings vanish. Weak agent UX is quiet budget destruction: the capability exists, and nobody trusts it enough to use it.
The 4 Pillars of Effective Agent UX
Transparency: Show what the agent plans to do, affected resources, and why.
Control: Let users pause, edit, approve, undo, or reverse actions at any stage.
Status: Communicate active progress, queued tasks, blockers, and required human input.
Recovery: Turn unexpected failures into clear, non-destructive paths forward.
Together, these four pillars turn an impressive demo into a reliable product people can safely use in production.
Why a Prompt Box Isn't an Agent Interface
Traditional interfaces follow a request-response model. A user clicks a button, submits a form, or types a query. The software processes the request and shows a result.
In contrast, agentic user interfaces support something harder: software that interprets a goal, builds a plan, takes multiple actions, monitors progress, and adjusts course with limited human input.
Compare asking software to draft a customer email with telling it to resolve overdue accounts. The second task means reviewing invoices, checking payment history, drafting messages, scheduling follow-ups, updating records, and escalating unusual cases. Every step carries a decision, a dependency, and a business risk.
A simple chat box cannot carry that complexity. It typically leaves users with:
Little visibility into what the agent is currently executing
No practical way to intervene mid-task without killing the workflow
Weak confirmation triggers before consequential actions execute
Minimal context when the agent stops, waits, or fails
No structured route for correcting partial work
The result: users cannot tell whether the agent is working, stuck, or making an expensive mistake.
Agentic interfaces also serve two audiences simultaneously: humans and AI agents. Humans need plain language, visible progress, and clear choices. Agents need semantic structure — explicitly labelled fields, predictable states, defined permissions, machine-readable actions, and unambiguous confirmation signals.
A human reads a greyed-out button as "unavailable." An agent needs an explicit state stating the action is unavailable because approval is pending. Design both layers well and you prevent accidental actions while making behavior far easier to test and audit.
That is the line between an AI demo and an AI product. A demo proves a model can finish a task in controlled conditions. A product helps real users understand, supervise, correct, and trust that behavior in messy ones.
Still mapping where agents belong in your operations? Smicolon's guide to understanding agentic workflows is a practical starting point.
Transparency in Agent UX: Show the Work, Not Just the Result
Would you let software move money without seeing its plan first?
Users need the right view of what an agent intends to do before it acts. Not technical logs or internal model calculations — a short, plain-language account of the plan, its scope, and its consequences.
Essential Transparency Patterns for UI Design for AI Agents
Intent previews: Summarize the specific goal the agent believes it received.
Plan displays: Show the primary execution steps before work begins.
Action logs: Maintain a real-time record of completed, skipped, and pending actions.
Decision summaries: Explain the rationale behind a choice without dumping raw reasoning.
Impact previews: Name the exact records, customers, systems, or funds an action will touch.
Take an agent preparing to update subscription prices. Instead of a generic "Working..." spinner, the interface should display:Planned Action: I will update 146 eligible accounts, exclude customers on fixed-price contracts, notify account owners, and schedule customer emails for Monday at 09:00. Nothing publishes until you approve the final list.
Now the user can check the scope, spot a bad assumption, and step in before damage happens.
Transparency is a core trust mechanism. When users understand what an agent is doing, they delegate more. When behavior stays opaque, they watch every step, verify the work elsewhere, or turn the feature off — erasing the productivity gain the agent was built to deliver.
What to Surface by Default
The current active objective
The next significant system action
Consequences and affected resources
Approvals or information required from the human supervisor
Any model uncertainty that could alter the outcome
Put detailed logs, supporting evidence, and completed substeps behind expandable panels. Progressive disclosure keeps routine work calm while preserving full auditability for compliance teams.
User Control: Override, Pause, and Set an Autonomy Dial
Autonomy without control feels less like assistance and more like exposure.
Agentic products should let users pause, edit, undo, or reverse actions inside the core workflow. Those controls cannot sit three menus deep in settings. They belong directly where decisions happen — especially around customer communications, production systems, financial records, and regulated data.
One pattern does most of the heavy lifting: the autonomy dial, a simple interface setting that lets a user or administrator choose how independently an agent may operate.
Autonomy Level | How It Operates | Recommended Use Case
1. Approve Every Step | Agent proposes each step and waits for explicit human sign-off. | Onboarding new workflows, high-risk financial tasks.
2. Approve Risky Steps | Agent handles routine execution automatically; flags high-impact or irreversible actions. | Operational standard; balances speed with risk management.
3. Fully Autonomous | Agent executes within bounded permissions and produces a post-execution report. | High-volume, low-risk, fully reversible background tasks.
This is how trust develops through evidence. A team starts with close supervision, reviews a few clean runs, then delegates deeper. The product earns autonomy instead of demanding it on day one.
Key Safeguard Controls to Implement
Confirmation gates before payments, record deletions, publication, or external messages
Editable plans so users can remove, reorder, or modify execution steps
Pause controls that halt the next action immediately without losing finished work
One-click rollback for quick reversal of recent changes
Scope limits on budgets, API rates, record counts, target recipients, and time windows
Permission boundaries that prevent an agent from extending its own authorization
Controls should state their consequences clearly. "Stop" is ambiguous. "Pause before sending the remaining 84 emails" tells the user exactly what happens next.
These safeguards do not dilute automation; they make enterprise adoption possible. Clear controls let teams place agents into customer-facing and financial workflows safely. If an agent touches production code or deployment pipelines, establish essential human checkpoints before execution starts.
Status and Handoff: The Most Important Screen You'll Design
Traditional software spins a loader for two seconds. Agents may work for minutes or hours. They wait on external APIs, run tasks in parallel, and hit decision thresholds they should not cross alone.
A progress spinner no longer does the job.
Effective agent UX status displays answer four critical questions at a glance:
What is running right now?
What has successfully completed?
What is queued to run next?
What is currently blocked, and why?
A strong status view shows that the agent reviewed 320 records, corrected 270, flagged 18 for human review, and paused 32 for missing data. That beats a progress percentage because it exposes actual work completed and exceptions requiring attention.
Designing the Handoff as a Decision Package
A handoff is the moment an agent halts and passes control to a person. It is frequently the single most important screen in an agentic product.
At handoff, the user interface should immediately present:
Goal Context: What the agent was attempting to accomplish.
Progress Summary: What was attempted and completed.
Blocker Reason: Exactly why the agent stopped.
Action Required: The specific decision, input, or approval needed.
Next Steps: What will happen immediately after the user responds.Example Handoff Screen:"I resolved 17 of 20 refund requests. Three are paused because their values exceed your £500 approval limit. Review the attached order histories and approve, reject, or edit each refund. I will notify the customers after your decision."
That handoff respects the human's time. It supplies context, narrows the decision, and specifies the immediate continuation. The anti-pattern is dumping the user into a raw chat thread, forcing them to investigate what went wrong.
Scale highlights why this matters. According to Salesforce reporting on agent interfaces, Agentforce handles roughly 32,000 customer conversations weekly with an 83% autonomous resolution rate. Even with high autonomy, the remaining 17% requires fast human handling. Status and handoff design decide whether exceptions become quick decisions or an unmanageable queue.
Recovery: Designing for Failure Builds More Trust Than Pretending It Won't Happen
AI agents will fail.
They will misinterpret goals, encounter offline APIs, operate on incomplete customer records, and hit permission boundaries. Saying so plainly earns far more user trust than promising flawless autonomy. The core UX challenge is turning failure into a structured, predictable recovery.
In product design, the service recovery paradox applies: handle a failure clearly and fairly, and users often trust the product more than before the error occurred because the system proved it remains safe and controllable under stress.
Effective Agentic Error Recovery Checklist
Plain-language error messaging: Explain what happened without hiding behind model codes.
Impact summaries: Clearly differentiate finished actions from unexecuted ones.
Suggested remediation: Provide concrete actionable choices, not generic "Try again".
Partial-action rollback: Allow users to safely revert completed steps if a later step fails.
Human escalation: Transfer the entire task context, log history, and state intact to support.
Safe retry controls: Explicitly state whether retrying will duplicate work or overwrite data.
Suppose an agent fails halfway through updating a product catalog. A bad error message displays: Error 500: Task failed. A useful recovery screen displays:Update Status: 214 of 300 products were updated. The remaining 86 failed because the inventory service timed out. Keep the 214 completed updates and retry the remaining 86, or roll back all changes.
Silent failure is catastrophic for user adoption. If an agent presents a task as complete while skipping actions or leaving exceptions unresolved, users uncover the gap later. They stop trusting the system, build shadow spreadsheets, and eventually abandon the agent feature entirely.
The Business Case: Agent UX Is Where AI ROI Lives or Dies
The importance of UI/UX in business success now carries an agent-specific metric: net time saved after supervision. Measure agent UX quality through active adoption, delegation depth, escalation velocity, and task completion rates — not visual polish alone.
Consider an agent that saves one hour per task in ideal conditions. If users spend that hour monitoring execution, double-checking decisions, and repairing partial failures, the net savings is zero. The underlying AI model wins the benchmark; the software product loses the account.
How UX Multiplies Model Performance
Transparency eliminates unnecessary user cross-checking.
Control makes deeper delegation safe for enterprise buyers.
Proactive status eliminates manual status checking.
Structured recovery drastically lowers the operational cost of exceptions.
Trust compounds over time. Users who experience predictable agent behavior delegate larger tasks and raise the autonomy dial, driving measurable ROI.
So evaluate your agentic features against these core criteria:
Can users inspect the agent's plan before high-impact actions execute?
Can users pause, modify, or reverse actions directly within the main workflow?
Does the UI clearly distinguish running, queued, blocked, and completed tasks?
Does every human handoff provide full context and a clear next step?
Can users recover safely when a multi-step task partially succeeds?
Do user permissions align precisely with the agent's actual execution boundary?
Model accuracy is essential, but it is not sufficient. The user interface determines whether model capability converts into actual business value.
This is why agent experience belongs in the product brief from day one. Smicolon's guide to writing a product brief helps teams map actions, permissions, risks, and approval points before committing code.
Building Agentic Products People Actually Trust
When designing or auditing any agentic user interface, verify these four operational dimensions:
Transparency: Show objectives, planned steps, affected data, and key rationale.
User Control: Embed pause, edit, approve, undo, and autonomy dials directly into the flow.
Proactive Status: Display live execution states and structure handoffs as complete decision briefs.
Structured Recovery: Anticipate failures, explain impact, and offer safe, non-destructive recovery paths.
Getting this right requires product design and engineering depth working together. Agent behavior and interface design cannot be built sequentially. Execution plans, permission checks, confirmation gates, reversibility, audit logging, and human handoffs form a unified system architecture.
That integration matters most when moving from prototype to production. An MVP still requires the structural features that make autonomous actions safe and understandable. Smicolon's framework for building a viable MVP helps product leaders retain the core usability features that drive adoption.
Smicolon partners with ambitious companies building and scaling AI-powered software products — combining custom UI/UX design with full-stack engineering, cloud architecture, and strategic product thinking so agent capabilities become software experiences users adopt with total confidence.
Building an agentic product this year? Book a discovery call — bring your product roadmap, and we will pressure-test the plans, permission models, and human handoffs your users need to trust it. No sales pitch, no obligation — just an expert working session with engineers and designers who ship autonomous software.
---
# Your Agents Aren't Slow — Your Platform Is: What Must Exist Before an Agentic Coding Workflow Multiplies Engineering Output
Source: https://smicolon.com/blog/your-agents-aren-t-slow-your-platform-is-what-must-exist-before-an-agentic-codin
Updated: 2026-09-16T02:01:56.435Z
- **The Real Bottleneck:** An **agentic coding workflow** accelerates code authoring, but traditional delivery platforms create severe verification and code-review bottlenecks.
Your Agents Aren't Slow — Your Platform Is: What an Agentic Coding Workflow Needs Before It Multiplies Output
Key Takeaways: Scaling Platform Engineering for AI
The Real Bottleneck: An agentic coding workflow accelerates code authoring, but traditional delivery platforms create severe verification and code-review bottlenecks.
Platform Requirements: High-performing AI coding agents infrastructure requires four core pillars: isolated ephemeral environments, millisecond provisioning, declarative API-driven infrastructure, and automated deterministic validation.
Governance at Speed: Modern platform engineering AI replaces ticket-based approvals with automated guardrails, policy-as-code, and machine-speed safety checks.
Optimized Review: Senior engineers must focus on architecture and security risk rather than basic code syntax or build failures.
AI Made Code Cheap. It Did Not Make Shipping Cheap.
An agentic coding workflow can write the code in minutes. Your company still needs days or weeks to ship it.
That gap is where most AI investments quietly stall. Teams adopt AI coding agents. Output climbs. Pull requests pile up. Release dates barely move, and senior engineers get busier instead of freer. If you are new to these concepts, read our guide on what are agentic workflows to understand their foundation.
The investment wasn't wrong. The bottleneck moved.
In high-adoption multi-agent workflows, teams merged 98% more pull requests. Review times grew 91%. Pull requests became 154% larger, according to Moderne's analysis of the code-review bottleneck.
More code entered the system. The system could not safely absorb it.
Think of AI agents as aircraft. Buying more planes does not move more passengers when you have one runway, a crowded control tower, and a ground crew working from paper requests. The aircraft are fast. The operation around them sets the real limit.
Software delivery works the same way. An agentic coding workflow is only as fast as the platform underneath it:
How quickly can an agent get an isolated environment?
Can it provision dependencies without opening a ticket?
Can it run realistic tests against safe data?
Does validation happen before a human review starts?
Can senior engineers focus on risk and architecture instead of basic defects?
Those questions matter most for growing companies. You want AI-assisted delivery speed without standing up an internal platform department your roadmap can't yet afford.
Your team isn't failing, and your agents probably aren't slow. Your platform was never built for this volume or pace.
Where the Agentic Coding Workflow Bottleneck Actually Moved
The business consequence is simple: more code does not create more customer value when verification stays slow.
Before AI coding tools, authoring consumed a large share of engineering time. An engineer had to understand the task, read the codebase, write the implementation, test it, and prepare it for review. Agents compress much of that from hours to minutes.
The downstream work does not disappear. Someone or something must still:
Confirm the code solves the right problem
Provision an environment where it can run
Check dependencies and configuration
Run tests and inspect failures
Review security and operational risk
Decide whether the change is safe to merge
This is the Theory of Constraints in practice: a system moves only as fast as its tightest constraint. When review and provisioning are already full, faster code generation adds inventory, not throughput. The inventory is unfinished pull requests.
That creates a human problem. Senior engineers become the toll booth on a ten-lane freeway. They receive more changes, larger changes, and changes written by systems that produce plausible code without understanding every business assumption behind it.
One of two failures follows. Reviewers inspect everything carefully, which causes gridlock and quiet burnout. Or they move fast enough to keep flow, which raises the risk of rubber-stamping code nobody fully understands.
That is why the verification gap deserves more attention than raw generation speed. Signadot's analysis and the freeCodeCamp review handbook both treat review capacity as a core constraint in AI-assisted delivery.
The goal is not to remove humans from engineering. It is to stop spending scarce human attention on checks software can run earlier and more consistently.
Once writing code is cheap, trusted verification becomes the valuable part of the system.
Why Human-Centric Platforms Break Under Agentic Load
A platform built for occasional human requests turns into an expensive queue the moment agentic workflows start running continuously.
Many engineering organizations still run on TicketOps — infrastructure work managed through manual tickets, approvals, and handoffs. A developer requests an environment. An operations engineer reviews the ticket. Someone configures access through a dashboard. The request waits for a shared staging slot. Cleanup happens later, if anyone remembers.
That works, barely, at a few requests a week. It is structurally incompatible with modern AI coding agents infrastructure.
Agents create, test, revise, and discard work repeatedly in a short window. Each cycle may need compute, dependencies, credentials, test data, network access, and an environment that resembles production. Manual gates cannot absorb that frequency without turning your platform team into a permanent help desk.
The failure modes are predictable:
Environment contention: agents and developers compete for the same shared staging system.
Provisioning queues: work waits hours or days for infrastructure it needs for minutes.
Configuration drift: development and test environments behave differently from production.
Approval fatigue: reviewers keep approving low-risk, routine requests.
Orphaned resources: short-lived work leaves behind databases, services, and credentials.
Dashboard dependence: a human must click through screens before an agent can continue.
As Port's discussion of agentic workflows explains, platform operations have to move past human-paced interfaces. Agents need to become first-class platform consumers.
That means APIs instead of dashboards, machine-readable policies instead of wiki instructions, and programmatic lifecycle management so an agent can request a resource, use it, produce evidence, and tear it down without waiting on a person.
None of that removes control. It moves control into platform engineering AI frameworks.
A highway has lane markings, speed limits, barriers, and entry rules. Those controls let traffic move safely at speed. Requiring every car to request individual permission would make the highway safer only because nobody could use it.
Agent-scale delivery needs controls that run at machine speed, not human queues dressed up as governance.
The Four Pillars of an Agent-Ready Platform
Platform readiness is not a vague transformation project. Score your current system against four concrete capabilities designed for an efficient agentic coding workflow.
Pillar | Traditional Human Platform | Agent-Ready Platform | Key Benefit
Environments | Shared staging, high contention | Ephemeral, isolated per task | Zero resource collisions
Provisioning | Ticket-based, hours/days | Instant APIs, milliseconds/seconds | Eliminates idle agent wait time
Infrastructure | Manual dashboard clicks | Declarative Infrastructure as Code | Auditable, repeatable environments
Validation | Post-PR human review | Automated deterministic check loops | Clean PRs with evidence pre-attached
1. Isolated, ephemeral environments
Every agent needs a safe place to work without colliding with another agent, a developer, or a shared test system.
An ephemeral environment is a temporary environment created for one task and destroyed when that task ends. It should carry the filesystem, dependencies, network boundaries, test databases, and configuration needed to run the change realistically.
Isolation limits the blast radius. An agent can install a dependency, modify files, execute code, and test a migration without contaminating anything shared. Parallel tasks stop fighting over the same database or deployment slot.
The environment also has to be disposable. If cleanup depends on someone remembering to delete it, agent volume turns temporary infrastructure into permanent cost and permanent security exposure.
2. Near-instant provisioning
A temporary environment helps only if it appears immediately.
When an agent finishes a task in minutes but waits far longer for an environment, infrastructure silently caps throughput. Teams then blame the model, the prompt, or the orchestration tool while the delay sits underneath all three.
Guidance on infrastructure for AI agents stresses fast, isolated development environments. Sandboxes can target provisioning around 100 milliseconds; more complex environments may take seconds. The standard is simple: setup should feel like part of execution, not a separate project.
That is the difference between giving aircraft an open runway and asking each pilot to help pour the concrete.
3. Declarative, API-driven infrastructure
Agents need a reliable way to request resources without improvising configuration or filing tickets.
Infrastructure as code (IaC) means defining infrastructure in version-controlled configuration instead of clicking it together in a dashboard. Declarative infrastructure describes the desired result; the platform works out the steps to get there.
Pair IaC with APIs and programmatic lifecycle management, so an agent can:
Request an approved environment template.
Receive scoped credentials and network access.
Deploy and test its change.
Collect logs and results.
Tear down resources automatically.
Infrastructure becomes repeatable and auditable. Drift drops, because agents and humans use the same approved paths.
4. Deterministic validation inside the loop
A pull request should not be the first place anyone learns whether the code builds. Before handing work over to reviewers, make sure you are aligning AI-generated code with your team's technical standards.
Deterministic validation means repeatable checks that return the same pass-or-fail result from the same inputs. Before an agent asks for review, the platform should run the required builds, tests, policy checks, and dependency scans.
The pull request then arrives with evidence:
Build status and logs
Unit and integration test results
Environment details
Changed dependencies
Migration results where relevant
Policy and security-check outcomes
A short explanation of scope and known risks
That changes the reviewer's starting question. Instead of "Does this run?" they can ask, "Is this the right design, and does it meet the business requirement?"
Score your platform
Give yourself one point per statement:
Agents get isolated environments for each task.
Environments include realistic dependencies and safe test data.
Provisioning finishes in milliseconds or seconds, not ticket cycles.
Approved infrastructure is available through APIs.
IaC defines environments consistently.
Resources expire or tear down automatically.
Validation completes before human review.
Every pull request ships with logs and proof from those checks.
A low score doesn't mean AI coding can't help your team. It means more agents will expose platform weaknesses faster than they create delivery capacity.
The four pillars turn AI output into controlled throughput: isolation, fast provisioning, programmable infrastructure, and evidence before review.
Governance Without Gridlock: Platform Engineering AI Needs Guardrails
Giving agents infrastructure access raises a fair question: doesn't autonomy invite security and operational chaos?
It does, if autonomy means unrestricted access. That is not the goal.
The better model uses guardrails that run automatically: policy as code (operational and security rules written as machine-enforceable configuration), complete audit trails, scoped permissions, spending limits, network boundaries, and approved environment templates.
An agent might be allowed to create a temporary test database but never touch production customer data. It might deploy to an isolated sandbox but not promote a release. It might pick from approved dependencies while escalating an unknown package for review.
That supports incremental autonomy:
Start narrow. Isolated sandboxes, synthetic data, limited credentials, strict expiration.
Observe behavior. Record requests, actions, validation results, failures, and resource use.
Expand by evidence. Widen permissions only after the platform proves its controls and audit trails hold.
Keep high-risk gates human. Production access, sensitive data changes, and major architectural decisions stay restricted.
The Agentic Platform Engineering project puts governance, observability, and controlled platform interaction at the center of this model. The broader discussion of agentic platforms draws the same line between basic automation and systems that act within explicit boundaries.
Good governance is not an approval queue bolted onto every action. It is a paved road with barriers in the right places.
For a growth-stage company, heavy enterprise governance can hurt as much as none at all. You need enough control to protect customers, systems, and budgets, without building a bureaucracy that eats the speed you bought AI for.
Well-designed guardrails let you say yes faster, because routine safety no longer depends on a meeting.
Fixing the Review Layer: Make Human Attention the Last Gate
Review capacity cannot scale linearly with agent output. Hiring a reviewer for every jump in generated code just rebuilds the cost structure AI was supposed to fix.
The platform has to pre-filter work before it reaches a senior engineer.
Start by making successful validation a condition for requesting review. A failed build, a missing test, an unapproved dependency, or a policy violation goes straight back to the agent. Humans should not hunt for defects the development loop can catch itself.
Next, shrink each decision. Agents can produce sweeping changes quickly, but speed is no reason to bundle unrelated work. Ask for one behavior change, one migration, or one bounded refactor per pull request. Smaller changes are easier to test, understand, revert, and approve.
Then route reviews by risk instead of treating every change the same:
Low risk: documentation, bounded tests, and approved mechanical changes can follow a mostly automated path.
Medium risk: application changes get focused ownership review with full validation evidence.
High risk: authentication, payments, sensitive data, infrastructure permissions, and architectural changes get deep human scrutiny.
This reshapes the senior engineer's role. They stop acting as line-by-line filters for an endless queue. They design validation rules, define risk tiers, improve environment templates, and weigh the decisions where judgment matters.
That role is more sustainable and more valuable. It also respects what sits behind the review metrics. A reviewer buried in oversized, machine-generated pull requests is not a slow employee. They are a scarce expert absorbing work the platform failed to filter.
This is how teams keep the value of 98% more merged PRs without accepting 91% longer reviews and 154% larger changes as the price. The answer is not faster clicking. It is better evidence, smaller units of work, and fewer routine failures reaching people.
For product owners, understanding human checkpoints in agentic workflows offers a practical way to decide where judgment has to stay.
Humans should review intent, risk, and architecture. The platform should prove the code builds, runs, and follows the rules.
Build vs. Partner: Getting Agent-Ready Without Stalling Your Roadmap
Agent-ready platforms take real work. There is no credible shortcut.
Someone has to define infrastructure templates, create ephemeral environments, expose safe APIs, automate cleanup, build validation pipelines, implement permissions, and wire evidence into the review process. Existing applications often need modernization before they run reliably in disposable environments.
For a large organization, a dedicated platform team is a sensible long-term investment. For a startup, SME, or mid-market company, building that capability from scratch pulls in the same engineers your product roadmap depends on.
That opportunity cost is easy to miss. Every quarter spent on internal platform plumbing is a quarter customer-facing work spends waiting. The gap compounds, too: competitors who fix the platform layer convert each new agent capability into delivery speed, while teams on manual infrastructure plateau.
The real choice is not "build everything internally" versus "hand control to a vendor." A delivery partner can build the foundations alongside your team while you keep product context, technical ownership, and roadmap control. Our in-house versus outsourced framework helps clarify which capabilities belong inside the company and where outside depth creates value faster.
Smicolon works as that kind of partner. We help growth-stage companies put in the cloud foundations, IaC, environment automation, validation pipelines, and modernization work that AI-speed delivery depends on. We don't hand over a platform and disappear. We work alongside your team, fit the architecture to your roadmap, and leave you with a system your engineers can operate and extend.
You can capture AI velocity without paying for a full platform team before you need one.
Your Platform Readiness Checklist — and Your Next Step
The constraint isn't the agents. It's everything around them: provisioning, environments, validation, governance, and review capacity.
Run through this before you expand your agentic workflows:
Each agent works in an isolated, ephemeral environment.
Environments include the dependencies, network controls, and test databases needed for realistic validation.
Provisioning takes milliseconds or seconds, not hours or days.
Agents request approved infrastructure through APIs, not tickets and dashboards.
IaC keeps environments repeatable and version controlled.
Resources expire automatically when the task ends.
Pull requests arrive with passing tests, build logs, policy results, and evidence of correctness.
Permissions are scoped, actions are auditable, and autonomy grows only as confidence grows.
Reviews are routed by risk, with senior attention saved for decisions that need judgment.
If several boxes stay empty, more coding agents will create more queues, not more releases. That's a useful diagnosis, not a failure. It gives your team a clear order of operations.
First build the runway. Then add aircraft.
Smicolon can assess the platform you have, name the constraints holding delivery back, and build the missing foundations alongside your team — tied to your product priorities, not a generic infrastructure program.
Book a discovery call and we'll map where your delivery bottleneck actually sits, and what it would take to remove it.
---
# Accessibility Is a Ship Requirement in 2026: What SMEs Must Build Into Every Product
Source: https://smicolon.com/blog/accessibility-is-a-ship-requirement-in-2026-what-smes-must-build-into-every-prod
Updated: 2026-09-19T02:00:48.916Z
**Quick Takeaway:** Digital accessibility in 2026 is a mandatory product requirement driven by the European Accessibility Act (EAA) and US ADA enforcement. For small and medium enterprises (SMEs), ach
Accessibility Is a Ship Requirement in 2026: What SMEs Must Build Into Every Product
Quick Takeaway: Digital accessibility in 2026 is a mandatory product requirement driven by the European Accessibility Act (EAA) and US ADA enforcement. For small and medium enterprises (SMEs), achieving compliance requires adopting WCAG 2.1 Level AA as the technical baseline across design, engineering, and testing processes.
Ship your product tomorrow. Would it pass an accessibility audit? Would an enterprise procurement team sign off on it?
That question now sits beside security, performance, and data privacy in every release discussion. Accessibility is not final polish. It is a fundamental ship requirement, shaped by legislation, procurement checklists, and the millions of users who rely on keyboards, screen readers, voice controls, and other assistive technologies.
Two critical regulatory forces define digital accessibility in 2026:
European Union: The European Accessibility Act (EAA) entered its active compliance phase for covered digital products and services in June 2025.
United States: Under Title II of the Americans with Disabilities Act (ADA), state and local government entities face an April 24, 2026 compliance deadline requiring adherence to Web Content Accessibility Guidelines (WCAG) 2.1 Level AA.
The practical reality for product managers and engineering leaders: you cannot patch accessibility the week before launch. Late retrofits create expensive rework across design, development, content, and QA—always when release deadlines are tightest.
Teams that integrate accessible design and engineering into continuous delivery ship with higher confidence, enter regulated markets faster, pass enterprise procurement reviews, and avoid costly redesigns. This guide breaks down what UX design for SMB compliance requires and how to build a scalable delivery framework.
The European Accessibility Act Applies to SMEs Selling Into the EU
European Accessibility Act web requirements do not stop at the EU border. If you sell a covered digital product or service to businesses or consumers in the EU market, the EAA applies regardless of where your company is incorporated.
Covered categories include e-commerce platforms, digital banking, electronic communications, e-books, and various software applications. For a practical breakdown of covered product categories and corporate obligations, see the European Accessibility Act guidance from Accessible.org.
The Microenterprise Exemption Is Narrow
The EAA contains a narrow exemption for certain microenterprises providing services. A microenterprise is strictly defined as an entity with fewer than 10 employees and an annual turnover or balance-sheet total under €2 million.
Most established SMEs and scaling mid-market companies exceed these bounds. If you are assessing risk, do not rely on an informal assumption—verify your headcount, global revenue, and product scope across all target markets.
Even where legal exemptions exist, building accessible UX for small business platforms remains a critical commercial strategy. Enterprise buyers frequently mandate WCAG conformance in vendor procurement contracts regardless of statutory minimums. Furthermore, growing companies lose exemption status the moment they cross headcount or revenue thresholds while building scalable MVP features.
What EAA Compliance Means for Product Teams
Digital experiences covered under the EAA must align with EN 301 549, the European standard for ICT product accessibility. For web applications and software interfaces, EN 301 549 directly incorporates WCAG 2.1 Level AA criteria.
WCAG structures digital accessibility around four core principles (POUR):
Perceivable: Information and UI components must be presentable to users in ways they can perceive (e.g., text alternatives for non-text content, captions for audio, and minimum color contrast ratios).
Operable: User interface components and navigation must be operable via keyboard, switch device, or alternative input methods without relying on precise mouse pointer interaction.
Understandable: Information and interface operations must be clear, predictable, and forgiving of user error.
Robust: Content must be robust enough to be interpreted reliably by a wide variety of user agents, including current and future assistive technologies.
These principles translate directly into engineering specifications. A modal dialog that traps keyboard focus violates operability. An error state indicated only by red outline violates perceivability. An icon button lacking an aria-label attribute fails robustness.
Enforcement occurs at the EU member-state level, where authorities can issue corrective orders, administrative fines, or force non-compliant products off the market. For details on enforcement mechanisms, review the Level Access EAA overview.
Meanwhile in the US: ADA Enforcement Converges on WCAG 2.1 AA
While the US private sector is governed by case law under Title III of the ADA rather than a single explicit federal web deadline, court rulings, DOJ guidance, and settlement agreements consistently establish WCAG 2.1 Level AA as the legal benchmark.
For public entities, statutory clarity is already here. Under the updated Title II regulations, state and local public bodies serving populations over 50,000 must achieve full web and mobile accessibility compliance by April 24, 2026. Review the April 24, 2026 ADA deadline overview for detailed coverage requirements.
Why Public Sector Deadlines Affect Commercial SMEs
Commercial software vendors, SaaS providers, and agency partners supplying tools to government entities, educational institutions, or enterprise buyers must support their customers' compliance mandates. Failing accessibility checks in vendor qualification reviews leads to immediate disqualification.
The strategic advantage: EU and US technical requirements share a single underlying standard. A digital product engineered and verified against WCAG 2.1 AA satisfies core compliance criteria under both EN 301 549 and ADA Title II/III frameworks.
Adopting WCAG 2.1 AA provides product teams with a single, verifiable baseline for digital accessibility in 2026.
Why "We'll Fix It Before Launch" Fails: The Case for Continuous Compliance
Attempting to retrofit accessibility late in the software development lifecycle multiplies costs and delays launches.
When accessibility issues are discovered during pre-release audits, designers must rework visual hierarchies and component libraries; developers must rebuild navigation logic, focus management, and form elements; content specialists must rewrite microcopy and alt text; and QA engineers must re-test end-to-end user journeys.
Retrofitting accessibility onto an existing code base is like attempting to pour a foundation after a building is constructed. It incurs the same friction detailed in our guide on the cost of bad software: short-term compromises create exponential technical and financial debt.
Furthermore, accessibility is an ongoing process, not a static milestone. A single update—such as adding an unlabelled navigation drawer, modifying brand colors, or embedding an unvetted third-party widget—can instantly introduce compliance regressions.
Shifting Accessibility Left
Continuous accessibility compliance requires moving validation checks directly into early stage delivery workflows:
Define accessibility criteria in initial user stories and acceptance criteria.
Audit component contrast, focus states, and typography in design systems.
Add automated accessibility linters and axe-core checks to CI/CD pipelines.
Include manual keyboard navigation checks in pull request templates.
Combine automated testing with periodic screen reader evaluation.
Automated testing tools catch approximately 30% to 50% of WCAG defects (such as missing alt attributes or invalid contrast ratios). Human evaluation remains essential to verify whether alternative text is contextually accurate or whether navigation order makes logical sense.
Technical Implementation Checklist for SMEs
Integrating accessible UX for small business applications into standard delivery workflows requires explicit ownership across every discipline.
1. Design Phase Requirements
Color Contrast Ratios: Ensure a minimum contrast ratio of 4.5:1 for standard body text and 3:1 for large text (18pt / 24px or 14pt / 19px bold) and user interface components.
Visible Focus Indicators: Design high-contrast focus rings for all interactive elements (buttons, links, inputs).
Touch Target Sizing: Maintain interactive target sizes of at least 44x44 CSS pixels for mobile interfaces.
Multi-Cue Status Signals: Never rely solely on color to convey information (e.g., combine color status with icons and descriptive text).
Responsive Reflow: Ensure layouts reflow seamlessly down to 320px width without loss of content or horizontal scrolling.
Integrating these rules directly into your Figma component library aligns visual design with technical execution. To examine how structured design choices drive commercial conversions, review our conversion-first UX playbook.
2. Engineering Phase Requirements
Semantic HTML Markup: Use native HTML elements (
 Technology Consulting
 Idea to MVP
 AI-Assisted Development
 Smicolon AI Coming Soon
 Web & Mobile Development
 UI UX Design
 Cloud Hosting
 Testing and QA
 Data Analytics & Insights
 Application Management
 Workflow Automation System
 Continuous Optimization